Tales at Scale - Analytics at 1000 QPS and Beyond
Explore high-performance analytics techniques for handling 1000+ queries per second, covering Apache Druid, CPU/IO optimization, and scaling strategies for heterogeneous workloads.
Deploying ML at Scale with Kubernetes and TFX
Learn to deploy machine learning models at scale using Kubernetes and TensorFlow Extended (TFX), enhancing your ability to manage and scale ML workflows efficiently.
Navigating the Challenges of Offer Categorization in E-commerce - Strategies for Accurate and Scalable Classification
Explore strategies for accurate and scalable offer categorization in e-commerce, addressing challenges, leveraging automation, and improving search relevance and product sorting.
Challenges and Learnings of Machine Learning at Scale
Explore challenges and learnings of training millions of models efficiently, optimizing costs, and achieving high-performance daily predictions in machine learning.
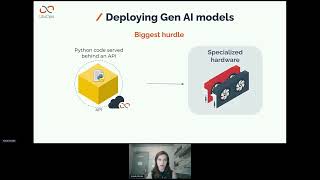
Deploying Generative AI Models - Best Practices and Interactive Example
Explore best practices for deploying generative AI models at scale, with an interactive example using UbiOps for serverless and cloud-agnostic implementation.
Inference at Scale with Apache Beam
Learn to deploy and scale machine learning models efficiently using Apache Beam for distributed inference on CPUs and GPUs, with practical insights on parallelizing workloads.
Through the Looking Glass: Key Architectural Choices in Flink and Kafka Streams
Explore architectural differences between Apache Flink and Kafka Streams, gaining insights into stream processing fundamentals and design choices for improved system performance.
Solr Eclipse - Zomato's Journey to 64 Million Search Queries a Day
Explore Zomato's journey scaling Apache Solr to handle 64 million daily searches across 100 million restaurant items in 13 languages, powering their homepage and overcoming technical challenges.
Git for Data Lakes: How LakeFS Scales Data Versioning to Billions of Objects
Learn how lakeFS enables Git-like versioning for data lakes, solving challenges of object storage and scaling to billions of objects without compromising performance. Explore branching, committing, and merging for petabyte-scale data management.

Delta Format and Live Tables - Pioneering Data Innovation
Explore Delta format and Live tables, understanding their role in scalable big data pipelines and modern data engineering innovations.
Apache Celeborn: Making Spark and Flink Faster, More Stable and More Resilient
Explore Apache Celeborn's high-performance Shuffle service for Spark and Flink, enhancing stability, performance, and cost-efficiency in large-scale data processing environments.
Building a Real-Time Analytics Database
Odkryj tajniki tworzenia bazy danych do analityki w czasie rzeczywistym. Poznaj kluczowe koncepcje i najlepsze praktyki w tej dziedzinie.
ML Monitoring ML: Scalable Monitoring of ML Models in Production Environments
Explore scalable ML model monitoring in production. Learn key performance measures, anomaly detection techniques, and an open-source agent for automated tracking and alerting of model issues.
MLOps at Scale: Predicting Bus Departure Times Using 18,000 ML Models
Explore MLOps at scale through a case study on predicting bus departure times using 18,000 ML models. Learn practical insights for implementing large-scale machine learning projects.
MLOps Without Much Ops - Building Efficient Machine Learning Systems
Discover modern, no-nonsense data pipelines for efficient machine learning systems. Learn PaaS advantages and explore real-world applications with open-source code. Gain insights on ML's future for organizations of all sizes.
Speeding Up Innovation with Cloud-Native and Continuous Delivery
Discover modern best practices for accelerating innovation through continuous delivery, cloud-native architecture, and chaos engineering, drawing from global organizational experiences and practical implementations.
Transforming Search with AI - Perplexity's Approach to Answer Engines
Explore AI-powered search innovation with Perplexity's CTO, discussing technical challenges, speed optimization, and the future of AI in delivering precise, fast answers to user queries.
Simplify GenAI App Development with Secure, Custom AI Agents
Explore best practices for managing AI model lifecycles, focusing on governance, monitoring, and performance tracking to ensure compliance and optimize delivery in production environments.
Solving Optimization Problems on Databricks for the Ad Industry
Explore scalable optimization techniques for ad industry using Databricks. Learn algorithms and tuning methods to process data efficiently and solve large-scale problems while integrating with existing infrastructure.
Data Warehousing Performance, Scale and Security with Databricks SQL
Explore high-performance data warehousing with Databricks SQL, focusing on scalability, security, and resource management for enterprise environments. Learn about latest advancements in scheduling and caching.
Optimizing Lakehouse Architecture Costs with Intel Software and Databricks
Enhance large-scale data processing for AI with autonomous CPU optimization, cost-effective resource management, improved scalability, and streamlined Spark operations using Intel's solutions for Databricks Data Intelligence Platform.