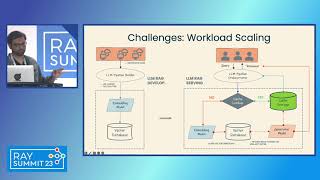
Enterprise Vector-based Information Retrieval and Prompt Engineering at Scale Using Open Source on AWS
Build enterprise-scale vector-based information retrieval systems using open source technologies on AWS, addressing challenges in Retrieval Augmented Generation for accurate, hallucination-free results.
Easily Scale to Production-Ready Generative AI with NVIDIA and Anyscale
Scale generative AI to production with NVIDIA and Anyscale's partnership. Learn how their combined technologies optimize performance, lower costs, and enable secure deployment of AI services at scale.
A Ray-based ML Platform for Early Cancer Detection
Explore how Ray enhances scalability and efficiency in machine learning for early cancer detection, focusing on improved model development and evaluation for potential diagnostic applications.
Fast and Scalable Model Training with PyTorch and Ray
Learn distributed model training with PyTorch and Ray. Migrate code, scale AI workflows, and optimize performance for large-scale training and fine-tuning on Anyscale.
Scalable and Cost-Efficient AI Workloads with AWS and Anyscale
Learn to scale and productionize GenAI and LLM workloads cost-effectively using AWS compute instances and Anyscale's capabilities for ambitious AI projects.
Scalable and Flexible Distributed Reinforcement Learning Systems
Explore scalable distributed reinforcement learning systems, focusing on flexible training loops, statement management, and GPU allocation. Gain insights into building efficient RLHF systems for large-scale applications.
From Two Strong Oxen to Billions of Fleas - The Evolution of Massively Parallel Distributed Supercomputers
Explore massively parallel distributed supercomputers, focusing on distributed-memory parallelism and RDMA through MPI. Gain insights into current designs and future challenges in high-performance computing.
HammingMesh: A Network Topology for Large-Scale Deep Learning
Explore a novel network topology for large-scale deep learning systems, enhancing data movement efficiency and job scheduling flexibility for future AI training infrastructure.

Harnessing Proprietary Data in the Era of Generative AI - Insights from AWS
Explore AWS's mission to democratize machine learning, offering customization capabilities for proprietary data. Learn about security, data governance, and scalable GenAI development for startups building innovative AI solutions.
Lies, Damned Lies and Timeouts Engineering
Explore the complexities of timeouts in distributed systems with Twitter's Principal Software Engineer. Learn to interpret and utilize timeouts effectively for robust system design.
Unlocking Scalability and Simplifying Multi-Cloud Management with Karmada and PipeCD
Explore Karmada and PipeCD for seamless multi-cloud management, addressing challenges in resilience, performance, security, and deployment across multiple cloud environments in the AI era.
Ensuring Success with Kyverno in Production - What You Must Know
Explore essential strategies for successful Kyverno deployment in production environments, covering policy creation, enforcement, scalability, and integration with existing workflows. Gain insights on optimizing performance and maintaining stability.
Leveraging Multi-Cluster Architecture for Resilient and Elastic Hybrid Cloud - Xiaohongshu Case Study
Explore multi-cluster architecture for resilient, elastic hybrid cloud. Learn about challenges, solutions, and best practices for efficient application distribution and secure migration in large-scale Kubernetes environments.
Model Service Mesh: A New Paradigm for Large-Scale AI Model Service Deployment and Management
Explore Model Service Mesh, a new paradigm for efficient deployment and management of large-scale AI model services in cloud-native environments, addressing scalability, security, and performance challenges.
Managing Kubernetes Watch Events End-to-End Flow in Extremely Large Clusters
Optimizing Kubernetes watch events in large clusters: Measuring latency, defining SLOs, identifying bottlenecks, and improving performance across components for enhanced stability and efficiency.
Building a High-Performance Time Series Database from Scratch - Optimization Strategies
Explore optimization strategies for high-performance time series databases, including string interning, caching, goroutine management, and efficient resource allocation using sync.Pool.
OpAMP - Scaling OpenTelemetry with Flexibility
Explore OpAMP's role in revolutionizing OpenTelemetry scalability through remote management, status reporting, and centralized control of diverse data collection Agents, enhancing flexibility and efficiency.
A Decade of Cloud-Native Journey: The Evolution of Container Technology and the Kubernetes Ecosystem
Explore the decade-long evolution of cloud-native technologies, focusing on container technology and Kubernetes ecosystem's impact on software development and enterprise operations.
Scaling Kubernetes: Best Practices for Managing Large-Scale Batch Jobs with Spark and Argo Workflow
Optimize Kubernetes for large-scale batch jobs using Spark and Argo workflows. Learn to tune control plane, improve pod scaling, and implement best practices for efficient cluster management.
Unleashing the Power of Cluster API - Extensibility and Customization
Explore Cluster API's extensibility for custom Kubernetes cluster management. Learn best practices for developing controllers, integrating tools, and creating bespoke workflows to address unique operational challenges.
Extend Kubernetes to Edge Using Event-Based Transport
使用基于事件的传输技术扩展Kubernetes至边缘,实现可扩展的中央控制平面,轻松管理数百万边缘集群,克服网络不稳定性挑战,适用于电信、零售等行业