Presto on Apache Spark - A Tale of Two Computation Engines
Explore the integration of Presto and Spark, combining low-latency evaluation with robust execution for enhanced SQL experience in both interactive and batch use cases at Facebook scale.
Designing the Next Generation of Data Pipelines with Apache Spark - Zillow's Approach
Zillow's data engineering team shares their journey in redesigning data pipelines using Apache Spark, focusing on scalability, maintainability, and robustness while reducing code complexity.
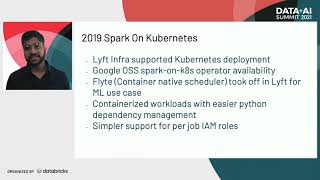
Hybrid Apache Spark Architecture: Optimizing YARN and Kubernetes for Lyft's Workloads
Explore Lyft's hybrid Apache Spark architecture using YARN and Kubernetes, addressing scalability challenges and optimizing workload management for improved reliability and efficiency.
DataSketches: A Production Quality Sketching Library for Big Data Analysis
Explore sketching algorithms for efficient big data analysis, enabling fast approximate answers to complex queries and real-time processing of massive datasets in production environments.
Portable and Scalable Data Visualization Techniques for Apache Spark and Python Notebooks
Explore portable and scalable data visualization techniques for Apache Spark and Python notebooks, covering strategies, packages, headless rendering, animations, and big data integration.
Composable Data Processing with Apache Spark - Scaling Development and Error Handling
Learn about SIP, an extensible plugin framework for Apache Spark that enhances data processing efficiency, error handling, and scalability in Adobe's Experience Platform.
How to Automate Performance Tuning for Apache Spark
Discover techniques to automate Apache Spark performance tuning, addressing common issues and exploring tools for efficient, scalable data pipeline maintenance in production environments.
Apache Spark on Kubernetes - Lessons Learned from Launching Millions of Spark Executors
Lessons learned from running massive Spark workloads on Kubernetes at Apple, covering orchestration, resource management, monitoring, and optimization for scalability and performance.
Accelerating Apache Spark Shuffle for Data Analytics on Cloud with Remote Persistent Memory Pools
Innovative solution for accelerating Apache Spark shuffle operations using remote persistent memory pools, improving performance, scalability, and reliability in cloud-based big data analytics.
How to Become a Networking Master with Jordan Harbinger
Discover effective networking strategies with Jordan Harbinger. Learn to build meaningful connections, reverse engineer your approach, and create scalable relationships that enhance your career and personal growth.
From Buy to Build - The Case for Building a Digital Automation Platform
Explore the shift from buying to building digital automation platforms, focusing on microservices architecture and process orchestration for enhanced business agility and scalability.
Securing Microsoft Teams - Automating Provisioning and Governance for Scalable Collaboration
Automate creation of secure Teams, manage external collaboration, and implement governance controls using Microsoft Graph, Azure Identity Governance, and Power Platform for enterprise-scale secure collaboration.
Scale Your Machine Learning Practice and Streamline Collaboration with Azure Machine Learning
Enhance collaboration across IT, data science, and development teams with Azure Machine Learning's latest features for seamless ML lifecycle management and improved organizational efficiency.
Kubernetes: The Cornerstone of Modern Data Engineering
Explore Kubernetes' impact on data engineering, focusing on open-source tools, scalability, and efficiency. Learn how it's shaping the future of data processing and management.

Scaling Fluentd From 0 to Millions of Events - Performance Optimization and Architecture
Explore Fluentd scaling strategies, performance optimization, and deployment architectures for handling millions of events efficiently in large-scale environments.
Systems Challenges in Graph Analytics
Explore challenges in building scalable graph analytics systems, focusing on algorithm behavior, resource allocation, and efficient hardware utilization for large-scale data processing.
Secure IoT Command, Control, and Exfiltration Using Apache NiFi and Apache MiNiFi
Explore secure IoT data collection and control using Apache NiFi and MiNiFi. Learn to prioritize, analyze, and encrypt data at the edge while ensuring compliance with local governance policies.
Introducing Kubeflow for Machine Learning and AI on Kubernetes
Explore Kubeflow for seamless machine learning model deployment, from laptop to production. Learn about its components, scalability benefits, and integration with tools like TensorFlow and Apache Spark.
Rook Deployed Scalable NFS Clusters Exporting CephFS
Explore scalable NFS clusters using Rook and CephFS for Kubernetes storage. Learn about dynamic deployment, high availability, and efficient management of distributed storage systems.
Introducing Kubeflow with TensorFlow and Apache Spark
Explore Kubeflow's role in streamlining machine learning workflows, from model development to production deployment on Kubernetes, with insights on scalability and integration with TensorFlow and Apache Spark.
Self-serve Feature Engineering Platform Using Flyte and Feast
Explore a self-serve feature engineering platform leveraging Flyte and Feast technologies, enhancing data science workflows and machine learning model development.