Building RAG Applications with PDFs Using LlamaIndex - Comparing Gemini Pro and Nvidia NIM Llama 3.2
Master RAG implementation using LlamaIndex to create PDF-based conversational agents with Gemini Pro and Nvidia NIM Llama 3.2, leveraging PymuPDF for text and image extraction.
Langchain: QA and RAG Components with Your Own Data
Build QA and RAG components using Langchain to integrate custom data for enhanced machine learning and generative AI applications.
Multimodal RAG Application Development with LlamaIndex, Google AI, Gemini Pro and Qdrant
Master building multimodal RAG applications using LlamaIndex, Google AI Studio SDK, and Gemini models to extract and process information from images with Qdrant vector storage integration.
RAG - How to Extract Information from PDF with LlamaIndex and OpenAI GPT-4
Master PDF information extraction techniques using LlamaIndex and GPT-4, enabling efficient document processing and data retrieval through practical implementation steps.
RAG: Building Document Question-Answering with Nvidia NIM and LlamaIndex Integration
Descubre cómo implementar RAG utilizando LlamaIndex y Nvidia NIM para interactuar con documentos privados, integrando LLama 3.2 3B y Phi3 3.5 Small para procesamiento de lenguaje natural.
RAG Integration with Nvidia NIM and LlamaIndex - Building Document Query Applications
Explore building a RAG application using LlamaIndex and Nvidia NIM to effectively query private documents with LLama 3.2 3B and Phi3 3.5 Small 128k models.
RAG vs PEFT - Comparing LLM Domain Adaptation Methods
Delve into LLM 도메인 적용을 위한 RAG와 PEFT 방식의 비교 분석과 SK브로드밴드의 실제 구현 사례를 통한 AWS 환경 구축 및 모델 개발 노하우
Automating Dark Web CTI Reports with RAG Insight for MISP Sharing
Discover how to automate Cyber Threat Intelligence reports from the dark web using RAG Insight, enabling efficient MISP sharing and enhanced threat detection capabilities.
Automated Evaluation for RAG Chatbot or Other Generative Tool - Conf42 LLMs 2024
Explore automated evaluation techniques for RAG chatbots and generative tools, covering string matching, semantic similarity, LLM-led evals, and grading rubrics.
The Power of GenAI: Generate Growth and Innovation with Data
Explore how GenAI and data drive innovation, growth, and personalized experiences. Learn about RAG, vector embeddings, and building data foundations for AI applications.
Measuring Hallucinations in RAG - Retrieval Augmented Generation
Explore techniques to measure and mitigate hallucinations in Retrieval-Augmented Generation (RAG) systems, with practical examples and insights on improving LLM-based applications.
AI-Augmented Platform Engineering
Explore AI-augmented platform engineering: principles, components, evolution, and real-world applications. Learn to implement domain-specific RAGs for enhanced developer experience in BFSI.

How to Improve LLMs with RAG - Overview and Python Code
Learn to enhance LLMs using Retrieval Augmented Generation (RAG). Explore its principles, implementation, and practical application in improving a fine-tuned model for YouTube comment responses.

Unify Project Demo - RAG Playground with LangChain
Explore a LangChain RAG Playground for document analysis, comparing LLM performance across providers for optimal speed, latency, and cost using dynamic routing.
Conquer RAG Retrieval Errors: 5-Step Tuning Process in Snorkel Flow
Optimize RAG retrieval with a 5-step tuning process in Snorkel Flow. Learn to identify errors, improve document chunking, and enhance embedding models for better accuracy and performance.
Digging Into RAG and the Future of AI - With Douwe Keila
Explore RAG applications, AI's enterprise future, and the role of data in improving AI systems with industry experts Alex Ratner and Douwe Keila.
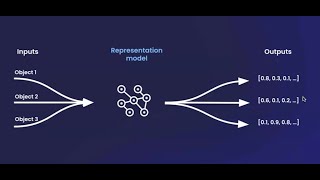
Best Practices and Tips for Fine-Tuning Representation Models
Discover techniques to enhance generative applications through representation model fine-tuning. Learn data quality strategies, augmentation methods, and optimization tips for RAG-based pipelines.
Building a Retrieval Augmented Generation System: Challenges and Best Practices
Explore the challenges and best practices in building a Retrieval Augmented Generation system, focusing on data quality, query engines, and contextualization for informed decision-making in your projects.
Navigating via Retrieval Evaluation to Demystify LLM Wonderland
Explore retrieval evaluation's crucial role in LLM applications, focusing on its impact on response quality. Delve into the link between retrieval accuracy and answer quality, emphasizing thorough evaluation methods.
Retrieval Augmented Generation (RAG) for LLM-Powered Apps
Explore retrieval augmented generation (RAG) for enhancing LLM-powered applications, gaining insights into its importance and practical implementation.

Building Local AI Agents with LangGraph and Ollama
Explore building local AI agents using LangGraph and Ollama. Learn integration techniques, code implementation, and compare with vLLM. Gain insights on Ollama's effectiveness for agent development.