PyScript for Data Science: Writing Python in the Browser
Explore PyScript's potential for data scientists to write Python in browsers, revolutionizing web development and enhancing data science workflows.
Deploying Generative AI Models - Best Practices and Interactive Example
Explore best practices for deploying generative AI models at scale, with an interactive example using UbiOps for serverless and cloud-agnostic implementation.
Pandas 2, Dask or Polars? Quickly Tackling Larger Data on a Single Machine
Explore Pandas 2, Dask, and Polars for efficient large data processing on a single machine. Compare features, performance, and ecosystem compatibility to choose the best tool for your research workflow.
Machine Learning with Apache Beam
Explore Apache Beam for distributed data pipelines in machine learning, covering inference, data processing, and training with hands-on demos for parallelizing ML workloads.
Visualization with Python Tutorial
Learn Python visualization techniques for geophysical fluid dynamics, covering data representation and analysis tools essential for atmospheric and oceanic research.

Data Engineering with Databricks - Leveraging the Lakehouse Platform for ETL Pipelines
Leverage Databricks Lakehouse Platform to build ETL pipelines, use Delta Live Tables, and orchestrate tasks with Workflows for efficient data processing.
Automate Boring Tasks - Techniques for Streamlining Repetitive Work
Discover how to automate repetitive tasks like filling timesheets, posting updates, and managing environments using REST APIs, Selenium, and Python. Learn practical tips for identifying and simplifying tedious processes.
scverse: An Introduction to Single-Cell Data Analysis in Python
Explore Python's ecosystem for single-cell data analysis with scverse, a community-driven initiative coordinating omics data work.

How to Build Data Pipelines for ML Projects with Python Code
Learn to build data pipelines for machine learning projects using Python. Explore ETL vs ELT, extraction, transformation, loading, and orchestration. Includes practical example of processing YouTube video transcripts.

Detecting Power Laws in Real-world Data with Python Code
Learn to detect power laws in real-world data using Python, covering log-log and maximum likelihood approaches with practical examples using artificial and social media datasets.

Introduction to Decision Trees - Gini Impurity and Python Code
Learn decision tree fundamentals, including Gini impurity and Python implementation, through a beginner-friendly introduction with concrete examples and code for sepsis survival prediction.

Causal Effects via Propensity Scores - Introduction and Python Implementation
Explore propensity scores for causal effects in observational data. Learn three methods: matching, stratification, and inverse probability weighting. Includes Python example and cautionary notes.

Automating Data Pipelines with Python and GitHub Actions - Code Walkthrough
Automate data pipelines using Python and GitHub Actions. Learn to create ETL scripts, set up repositories, configure workflows, and implement ML applications for efficient data processing.

Building Machine Learning Solutions with Python - Code Walkthrough
Develop a semantic search tool for YouTube videos using Python, focusing on experimentation, evaluation, and UI building in machine learning solutions.
Jupyter Notebook vs Classical IDEs - Do You Have to Choose?
Explore the strengths and limitations of Jupyter Notebooks and traditional IDEs, understanding when to use each for optimal coding efficiency and productivity.
How to Create Data-Cleaning Auto-Pipelines With Python
Develop automated data cleaning pipelines using Scikit-Learn to streamline data processing, reduce time spent on preprocessing, and enhance reproducibility in your data science projects.
RPA, TDD, and Embedded - A World Glued Together with Python
Explore RPA, TDD, and embedded systems integration using Robot Framework and Python. Learn to maximize testing potential in microcontroller environments through practical examples.
Caching for Jupyter Notebooks
Aprenda técnicas de caching para acelerar o desenvolvimento em Jupyter Notebooks, melhorando o fluxo de trabalho e reduzindo o tempo de espera em células dispendiosas.
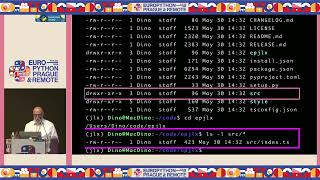
Creating Your Own Extensions for JupyterLab
Learn to create custom JupyterLab extensions, enhancing functionality and integrating complex tasks. Explore the extension infrastructure and build a step-by-step app with styling and parameter options.
DBT and Python - How to Write Reusable and Testable Pipelines
Develop reusable and testable data pipelines using DBT and Python. Learn best practices for version control, DAGs, and unit testing in SQL and Python-based models.

chDB - The Blazing Fast SQL Engine for Data Science
Explore chDB, a high-performance SQL engine for Python data ecosystem. Leverage its extensive data source support, ANSI SQL compliance, and seamless integration with popular libraries for efficient data analysis.