Running Apache Kafka in Production - 6 Key Recommendations
Discover essential recommendations for optimizing Apache Kafka in production environments, covering operational aspects, serialization, architecture, and advanced features for efficient data streaming.
Decoupling with Event-Driven Architecture: Implementing Data Mesh Using Galapagos
Explore event-driven architecture with Galapagos, an open-source tool for Apache Kafka. Learn how to decouple teams, improve data management, and enhance business communication through event-driven thinking.
Improving Apache Kafka Scalability and Elasticity with Tiered Storage
Explore tiered storage in Apache Kafka for improved scalability and elasticity. Learn implementation, benefits, and impact on performance from a Confluent engineer.
Building a Winning Data Engineering Culture
Learn to build a successful data engineering team and culture, empowering engineers and partners for efficient data systems and fruitful projects. Explore critical roles and strategies for data-driven decision-making success.
Rule Based Asset Management Workflow Automation at Netflix
Explore Netflix's innovative approach to automating asset management workflows using rule-based systems, enhancing efficiency and scalability.
OpenMessaging Benchmark - Measuring the Performance of Streaming Systems
Explore OpenMessaging Benchmark to measure and compare performance of streaming systems, enhancing data infrastructure decisions for real-time applications.
Business Event-Driven Architecture and Governance in Action
Implement Event-Driven Architecture effectively with a Center of Excellence. Learn from real-life experiences in large industries to set up strong foundations, define designs, and guide development teams.
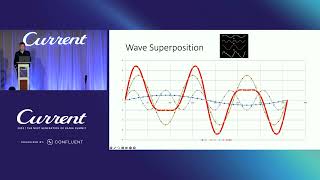
Fast Fourier Transform (FFT) of Time Series in Kafka Streams
Explore digital signal processing with Kafka Streams, transforming time-domain signals to frequency domain using FFT. Learn to build a precise frequency alert system and visualize results in real-time.
Approaching Kafka Replication at Scale - Go Big or Go Home
Explore scaling strategies for Kafka, including horizontal and vertical scaling, replication techniques, and routing events between clusters. Learn to overcome bottlenecks and manage large-scale data processing effectively.
Configuring Kafka Connect for Scalability - Best Practices
Optimize Kafka Connect clusters for scalability. Learn best practices to configure and manage Kafka Connect effectively, ensuring successful integration of external systems with Apache Kafka at scale.
Maximizing Real-Time Data Processing with Apache Kafka and InfluxDB - A Comprehensive Guide
Learn to create powerful data pipelines by combining Apache Kafka and InfluxDB for real-time processing, analysis, and visualization of large-scale data, especially in IoT applications.
Evolution of Streaming Pipeline at Lyft - Real-Time Optimization Platform
Explore Lyft's real-time optimization platform evolution, focusing on streaming infrastructure for marketplace balance, scalability, and decision-making using Kafka and data science tools.
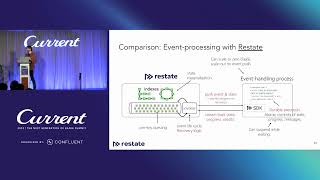
Restate: Stream Processing for Microservices
Explore a novel system for microservices that handles state, communication, and consistency. Learn how it complements event-processing systems for complex control flow and coordination in distributed applications.
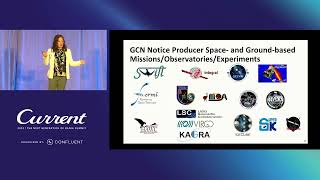
General Coordinates Network: Harnessing Kafka for Real-Time Open Astronomy at NASA
Explore NASA's use of Kafka for real-time astronomy data sharing, including architectural choices and OAuth2 implementation for public access in the General Coordinates Network.
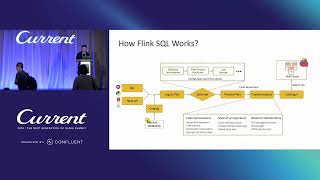
Flink SQL: The Challenges to Build a Streaming SQL Engine
Explore challenges in building a streaming SQL engine like Flink SQL. Learn about late data handling, change data processing, event ordering, nondeterminism, and state storage in stream processing.
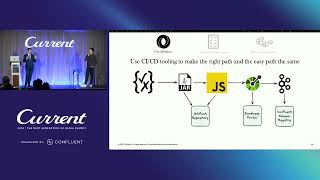
Beyond Monoliths: Thrivent's Lessons in Building a Modern Integration Architecture
Explore strategies for modernizing data architecture, from technical aspects like JSON Schema and OpenTelemetry to human factors like building trust and adopting a product-focused mindset.
Debezium Snapshots Revisited - Incremental Snapshots for CDC Pipelines
Explore innovative incremental snapshot techniques for Debezium CDC connectors. Learn to pause, resume, and parallelize snapshots, and customize snapshot contents for efficient data pipeline management.
Dynamic Change Data Capture with Flink CDC and Consistent Hashing
Implement dynamic Change Data Capture for large databases using Flink CDC connectors and consistent hashing. Overcome challenges with incremental snapshotting and Postgres replication slots.
Automatically Detect and Remediate Degraded Storage in Kafka
Discover an automated system for detecting and remediating degraded storage in Kafka, improving cluster performance and availability. Learn about monitoring, algorithm formulation, and mitigation strategies.
From Raw Data to an Interactive Data App in an Hour - Powered by Snowpark Python
Develop a Streamlit data app to visualize advertising ROI using Snowpark Python. Learn data ingestion, transformation, ML modeling, and interactive visualization techniques.
Time-State Analytics for Multidimensional Event Streams
Explore multidimensional time-state analytics for complex, large-scale metrics tracking. Learn about architectural and algorithmic solutions to improve performance, reduce costs, and simplify development.