What Breaks Our Systems - A Taxonomy of Black Swans
Explore categories of unforeseen, catastrophic system failures and strategies to fortify against them, including capacity testing, incident management, and communication.
Testing in Production at Scale
Explore real-world insights on implementing testing in production for large-scale microservices, focusing on architecture, capacity planning, and infrastructure components.
Lessons Learned in Black Box Monitoring 25,000 Endpoints
Explore black box monitoring of 25,000 government endpoints, learning strategies to monitor resistant systems and improve digital services across the US government.
Datacenter RPCs Can Be General and Fast
Efficient RPC library for datacenter networks offering high performance without sacrificing generality. Handles packet loss and congestion while achieving low latency and high bandwidth on commodity hardware.
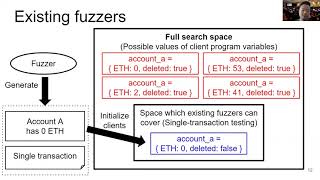
Finding Consensus Bugs in Ethereum via Multi-transaction Differential Fuzzing
Explore multi-transaction differential fuzzing for detecting Ethereum consensus bugs, improving security and reliability in blockchain networks.
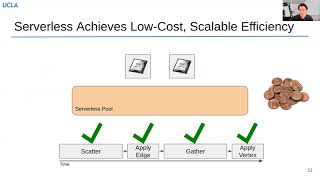
Dorylus - Affordable, Scalable, and Accurate GNN Training with Distributed CPU Servers and Serverless Threads
Distributed system for training Graph Neural Networks using serverless computing, offering affordable scalability for billion-edge graphs with improved performance-per-dollar compared to GPU servers.
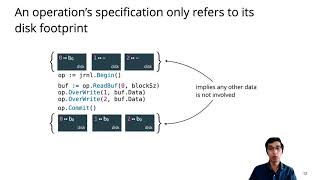
GoJournal - A Verified, Concurrent, Crash-Safe Journaling System
Explore GoJournal, a verified concurrent journaling system for storage applications. Learn about its implementation, performance, and the challenges overcome in its development and verification process.
Prediction-Based Power Oversubscription in Cloud Platforms
Explore power oversubscription in cloud platforms using prediction-based techniques to optimize datacenter resources, increase efficiency, and minimize impact on critical workloads.
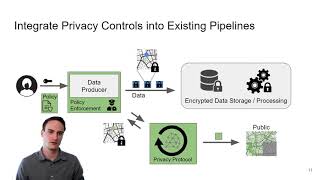
Zeph - Cryptographic Enforcement of End-to-End Data Privacy
Cryptographic system for enforcing user-defined privacy policies in real-time data analytics, ensuring compliance and protection against breaches while maintaining scalability and low latency.
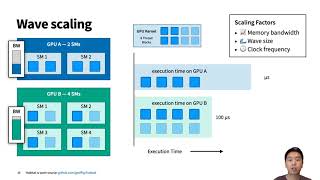
Habitat - A Runtime-Based Computational Performance Predictor for Deep Neural Network Training
Explore a runtime-based technique for predicting GPU performance in deep neural network training, aiding cost-efficient hardware selection for researchers and practitioners.
SKQ - Event Scheduling for Optimizing Tail Latency in a Traditional OS Kernel
Explore SKQ, a FreeBSD Kqueue redesign that significantly improves application tail latency and low-latency throughput through scalable architecture and event scheduling policies.
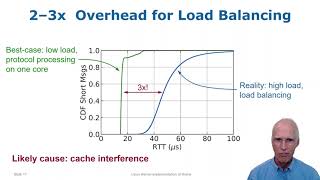
A Linux Kernel Implementation of the Homa Transport Protocol
Explore Homa/Linux: a high-performance transport protocol outperforming TCP and DCTCP in latency and congestion control, with potential for further optimization through software overhead reduction.
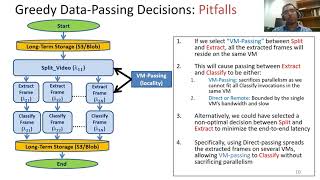
SONIC - Application-Aware Data Passing for Chained Serverless Applications
Optimizes data passing in serverless workflows, adapting to dynamic factors for improved performance and cost-efficiency in analytics applications.
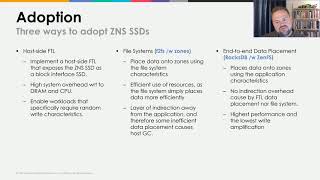
ZNS - Avoiding the Block Interface Tax for Flash-based SSDs
Explore Zoned Namespace SSDs: improved efficiency, higher throughput, and lower latency for flash storage. Learn about interface changes, software adaptations, and performance benefits in Linux and RocksDB.
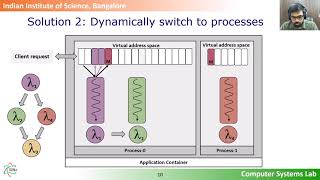
Faastlane - Accelerating Function-as-a-Service Workflows
Accelerating FaaS workflows by executing functions as threads, providing lightweight isolation, and dynamically identifying parallelism opportunities to enhance performance and reduce latency.
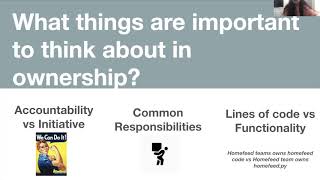
Building Actionable Code Ownership
Discover Pinterest's scalable API ownership framework, designed to manage 1700+ endpoints across 70+ teams, addressing challenges and implementing effective solutions for large-scale code management.
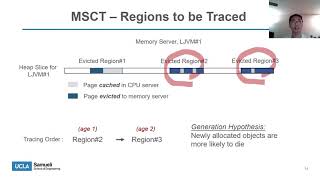
Semeru - A Memory-Disaggregated Managed Runtime
Innovative distributed JVM for memory-disaggregated environments, featuring a universal Java heap, distributed garbage collection, and efficient swap system to enhance managed cloud application performance.
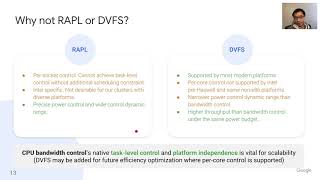
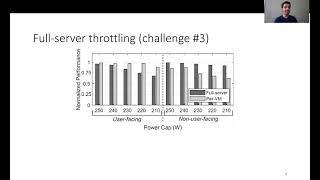
Thunderbolt - Throughput-Optimized, Quality-of-Service-Aware Power Capping at Scale
Explore power capping in data centers with Thunderbolt, a system optimizing throughput and quality of service. Learn about hardware-agnostic solutions for safe power oversubscription and task-level QoS differentiation.
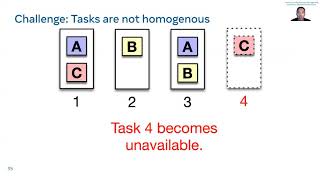
Twine - A Unified Cluster Management System for Shared Infrastructure
Explore Facebook's Twine, a unified cluster management system for shared infrastructure, scaling to manage one million machines across data centers with innovative approaches to workload customization and resource allocation.
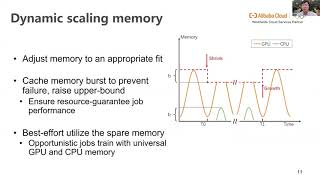
AntMan - Dynamic Scaling on GPU Cluster for Deep Learning
Dynamic scaling system for efficient GPU utilization in deep learning, improving memory and computation usage without compromising fairness or performance in large-scale clusters.
Command and KubeCTL - Real-World Kubernetes Security for Pentesters
Explore Kubernetes security challenges, attack techniques, and practical advice for pentesters and security practitioners in containerized environments.