IISAN: Efficiently Adapting Multimodal Representation for Sequential Recommendation - M2.6
Explore efficient multimodal representation adaptation for sequential recommendations using decoupled PEFT in this innovative research presentation.
Pre-training and Fine-tuning of Code Generation Models
探索代码生成模型的构建过程,包括StarCoder的训练、负责任的AI实践,以及如何利用开源库来部署和使用这些强大的模型。
MLOps: Optimización PEFT para Resumen de Diálogos con Flan-T5 (LoRA) - Español
Aprende a optimizar modelos Flan-T5 con PEFT (Lora) para resumir diálogos eficientemente, incluyendo técnicas de prompt tuning y evaluación de resultados.
MLOps MLflow: Fine-Tuning Mistral 7B con PEFT y QLora - Español
Aprende a ajustar Mistral 7B utilizando técnicas avanzadas como PEFT y QLora, integrando MLflow para un seguimiento eficiente del proceso de fine-tuning.
Coding RLHF on LLama 2 with LoRA, 4-bit Quantization, TRL and DPO
Master advanced LLM fine-tuning techniques using RLHF, implementing DPO and PPO methods on Llama models with 4-bit quantization and LoRA for optimized performance and human feedback integration.
Fine-tuning Gemma Models with PEFT and LoRA Using HuggingFace Datasets
Master parameter-efficient fine-tuning techniques for Gemma 2B model using PEFT and LoRA, with hands-on code implementation and custom dataset creation for optimized model training.
Understanding 4-bit Quantization and QLoRA - Memory Efficient Fine-tuning of LLMs
Dive into memory-efficient fine-tuning of large language models through 4-bit quantization and QLoRA, combining theoretical foundations with practical implementation in Colab.
Parameter Efficient Fine-Tuning with Multiple LoRA Adapters for Large Language Models
Dive into parameter efficient fine-tuning with LoRA adapters, exploring matrix factorization, SVD, and advanced configurations for optimizing large language models.
LLama 2 and PEFT Documentation - Building Interactive LLM with Retrieval Augmented Generation
Master building a RAG-enhanced LLM system using Llama 2 through hands-on coding. Learn web scraping, embedding generation, vector indexing, and semantic search to create an AI that leverages external knowledge sources.
Fine-tuning LLama 2 with PEFT, LoRA, 4-bit Quantization, TRL and SFT
Master advanced LLama2 fine-tuning techniques using PEFT, LoRA, and 4-bit quantization while creating synthetic datasets with GPT-4 for customized model training.
Stanford ALPACA 7B LLM: Fine-tuning Guide with Code and Datasets
Discover how to fine-tune and implement Stanford's ALPACA 7B language model using LLaMA, exploring practical applications and cost-effective methods for creating custom AI solutions.
Fine-tuning Vision Language Models with PaLiGemma-3B - A Practical Guide
Master fine-tuning techniques for Vision Language Models using PyTorch and JAX FLAX, with practical examples for PaliGemma-3B implementation on free compute platforms like Google Colab and Vertex AI.
Optimizing LLM Fine-Tuning with PEFT and LoRA Adapter-Tuning for GPU Performance
Master efficient fine-tuning of large language models using PEFT and LoRA techniques, optimizing GPU memory usage through INT8 quantization and adapter-tuning for cost-effective model development.
Parameter-Efficient Fine-Tuning with LoRA - Optimizing LLMs for Local GPU Training
Master PEFT LoRA techniques to efficiently fine-tune large language models on local GPUs through low-rank adaptation, reducing memory requirements while maintaining model performance.
Fine-Tuning Code Language Models - A Practical Guide
Master the process of fine-tuning Code LLMs using instruction datasets, from environment setup to implementation, with hands-on demonstrations using StarCoder and practical GPU requirements guidance.

Fine-Tuning LLMs with PEFT and LoRA
Explore efficient fine-tuning of large language models using PEFT and LoRA techniques, with a focus on practical implementation and uploading to HuggingFace Hub.
Generative AI and Large Language Models: Fine-tuning with SageMaker, PEFT, RLHF and PPO
Master advanced LLM fine-tuning techniques using Amazon SageMaker, exploring PEFT, RLHF, and PPO methodologies for optimized AI model performance and customization.
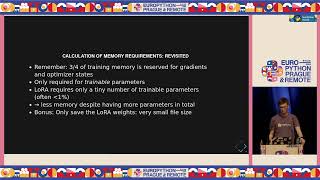
Fine-tuning Large Models on Local Hardware Using PEFT and Quantization
Explore Parameter-Efficient Fine-Tuning (PEFT) and quantization techniques to train large neural networks on modest hardware using the PEFT library and Hugging Face ecosystem.
RAG vs PEFT - Comparing LLM Domain Adaptation Methods
Delve into LLM 도메인 적용을 위한 RAG와 PEFT 방식의 비교 분석과 SK브로드밴드의 실제 구현 사례를 통한 AWS 환경 구축 및 모델 개발 노하우
End-to-end Modern Machine Learning in Production - Part 2
Explore RLHF, efficient training techniques, on-device ML, and optimizations in modern machine learning production with insights from a Hugging Face lead engineer.
MLOps: Fine-tuning Mistral 7B with PEFT, QLora, and MLFlow
Fine-tune Mistral 7B using PEFT, QLora, and MLFlow techniques. Master advanced LLM optimization for improved performance and efficiency.