Apache Arrow and Substrait - The Secret Foundations of Data Engineering
Explore Apache Arrow and Substrait's impact on data engineering, including their role in interoperability, query planning, and building efficient database systems with minimal code.
Code Like a Snake Charmer Version 2.0 - Introduction to Python
Comprehensive introduction to Python for data science, covering basics and machine learning using real-world datasets. Ideal for beginners looking to integrate Python into Microsoft tools.
Scaling Machine Learning Workflows to Big Data with Fugue
Learn to scale machine learning workflows from Pandas to distributed computing using Fugue, an open-source abstraction layer. Discover how to port Python code to Spark or Dask with minimal changes, enabling framework-agnostic and scale-agnostic data scie…
Scale Data Science Using Pandas API on Spark
Discover how to scale data science workflows using Pandas API on Spark, enabling efficient processing of large datasets while maintaining familiar pandas functionality and optimized performance.
Processing and Storing Time Series Instrument Data with Pandas and PySpark
Master data processing techniques for handling large-scale time series instrument data using pandas and PySpark, focusing on efficient solutions for scientific and laboratory information management challenges.

Give Rust a Chance for High-Performance Data Processing in Python
Explore high-performance data processing in Python using Rust modules. Create Rust modules with Python bindings and discover why Rust is replacing C in data libraries.
How to Search Your Twitter Archive with Python
Learn to download, reshape, order, and analyze your Twitter archive using Python, enabling you to find and preserve your best tweets during uncertain times.

ME3255 - Python Code Examples from Discussion
Learn Python coding techniques for mechanical engineering applications through practical examples and discussions.
Getting Started with Python in Microsoft Excel - A Beginner's Tutorial
Discover how to leverage Python's powerful data analysis and visualization capabilities directly within Microsoft Excel, from basic syntax to advanced libraries like Pandas and Matplotlib.
Better Together - Unleashing the Synergy of Pandas, Polars, and Apache Arrow
Discover how to optimize data engineering workflows by combining Pandas and Polars with Apache Arrow, learning techniques to build faster, more efficient data pipelines for scalable solutions.
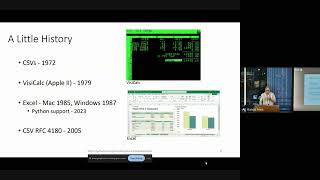
Spreadsheet Does What?! - Working with Spreadsheets in Python
Explore the intricacies of Python-based spreadsheet handling, from historical developments to common challenges and practical solutions for effective data management.
Create DataFrame Applications with Streamlit and Pandas in Python
Learn to create interactive DataFrame applications using Streamlit and Pandas with just two lines of Python code, enabling quick data visualization and manipulation.
Big Data Analytics with AI: Enhancing Pandas for Advanced Data Processing
Revolutionize data analysis by merging Pandas with AI. Automate cleaning, create smart visualizations, and perform predictive analytics using OpenAI's language models.
Pandas Parallel Transformations with Dask and Pandarallel
Optimize data processing with Dask and Pandarallel for faster Pandas transformations. Learn parallel computing techniques to enhance performance.

ME3255: Loading Data into Pandas and Boolean Indexing - Lecture 1
Learn to load data into Pandas, perform boolean indexing, and explore unique operations and color maps in this concise tutorial on data manipulation techniques.
Prediction Markets with the Kalshi API - Python Tutorial
Learn to use Kalshi's API for prediction markets in Python. Explore data collection, pandas integration, and real-time websocket functionality. Gain insights into market comparisons and semantic bet matching.
Mistral Function Calling - Integrating Applications with AI
Learn to integrate real-time data fetching into Mistral AI applications. Step-by-step guide on implementing function calls for stock prices and payment status checks, enhancing your AI development skills.
Making Beautiful, Publication Quality Tables in Python - 2024 Update
Explore techniques for creating visually appealing, publication-ready tables in Python, bridging the gap between raw DataFrame output and structured, informative displays.
Speed is Not All You Need for Data Processing
Exploring data processing frameworks beyond Pandas, challenging assumptions about speed, and emphasizing practical considerations for choosing tools that best serve data practitioners.
Vectorization Techniques for 1000x Python Speedups - No C or Spark Required
Discover techniques for achieving 1000x speedups in Python through vectorization, matrix operations, and creative optimization strategies. Learn to apply these methods to complex financial and ESG computations.
Fantastic Data Science Libraries and Where to Use Them
Discover high-performance alternatives to popular data science libraries, exploring GPU acceleration, distributed computing, and optimization techniques for faster data processing in Python.