Time Series Analytics with Apache Arrow, Pandas and Parquet - A Beginner's Guide
Discover how to build high-performance time series analytics applications using Apache Arrow Flight, Parquet, and Pandas, focusing on efficient data processing and querying techniques for columnar databases.
Empowering AWS DevOps with Python and Machine Learning
Optimize AWS DevOps using Python and machine learning techniques for efficient cloud infrastructure scaling and performance improvement.
Top 4 Python Libraries for Data Science
Explore four essential Python libraries for data science: NumPy, Pandas, Matplotlib, and Seaborn. Learn their key benefits and practical applications in fundamental data science concepts.
Pandas and Dask DataFrame 2.0 - Comparison to Spark, DuckDB and Polars
Explore Dask DataFrame 2.0's improvements and performance compared to Spark, DuckDB, and Polars. Learn about new features, benchmarks, and future developments in distributed computing with Python.
Python and SQL: Better Together, Powered by DuckDB
Explore DuckDB's integration with Python for efficient data processing, combining SQL and dataframe capabilities to handle large datasets with ease and speed.
Time Series Analytics with Apache Arrow, Pandas, and Parquet - A 101 Introduction
Explore efficient time-series data handling using Apache Arrow and Parquet. Master open-source technologies for high-performance analytics applications.
Hands-on Python: Analysis and Prediction of Bangalore House Price Data
Analyze and predict Bangalore house prices using Python, gaining practical data analysis skills for real estate market insights.
Open Standards Make MLOps Easier and Silos Harder - MLOps Podcast Episode 234
Explore open standards in MLOps for easier data system integration, scalability, and collaboration. Learn about Ibis, Apache Arrow, and their impact on data engineering and machine learning workflows.
The Missing Python Introduction for Scientists - Performance and Efficiency
Explore Python's internals, performance optimization, and essential scientific libraries. Learn to write efficient code and choose the right tools for scientific computing tasks.
EDA Techniques for Data Analysis
Explore powerful Exploratory Data Analysis techniques for cleaning, visualizing, and understanding datasets to drive insights and inform decision-making in business contexts.
Times and Dates in Pandas
Explore Pandas' powerful capabilities for handling time-based data, from parsing inputs to performing sophisticated analysis and resampling, enhancing your data manipulation skills.
Hacking Import for Speed: Writing a GPU Accelerator for Pandas
Explore Python's import system hacking to accelerate pandas on GPU using cuDF. Learn Pythonic proxy patterns and dynamic features to boost performance without code changes.

Pandas and Dask DataFrame 2.0 - Comparison to Spark, DuckDB and Polars
Explore Dask DataFrame 2.0's improvements, comparing its performance to Spark, DuckDB, and Polars using TPC-H benchmarks. Learn about new features enhancing speed, efficiency, and usability in big data processing.

Python and SQL: Better Together, Powered by DuckDB
Explore DuckDB: A powerful database system integrating seamlessly with Python, offering efficient data processing and easy-to-use SQL capabilities for data scientists and analysts.

Speed is Not All You Need for Data Processing
Exploring data processing frameworks beyond Pandas, challenging assumptions about speed, and emphasizing practical considerations for choosing tools that best serve data practitioners.

Making Beautiful, Publication Quality Tables in Python - 2024 Update
Explore techniques for creating visually appealing, publication-ready tables in Python, bridging the gap between raw DataFrame output and structured, informative displays.

Times and Dates in Pandas
Explore Pandas' powerful capabilities for handling time-based data, from parsing inputs to performing sophisticated analysis and resampling, enhancing your data manipulation skills.

Hacking Import for Speed: Writing a GPU Accelerator for Pandas
Explore Python's import system hacking to accelerate pandas on GPU using cuDF. Learn Pythonic proxy patterns and dynamic features to boost performance without code changes.
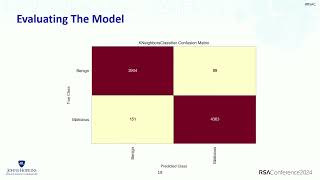
Threat Hunting with Python and Pandas - Data Science Techniques for Cybersecurity Analysis
Explore data science techniques for efficient threat hunting using Python, Pandas, and Scikit-Learn. Gain insights into applying these tools for enhanced cybersecurity analysis and operations.
Python in Cloudflare Workers - Running Pyodide on the Edge
Explore serverless Python deployment on Cloudflare Workers, featuring demos of scalable apps with database, storage, and AI integrations. Dive into technical challenges of running Pyodide in a serverless environment.

Ruff: An Extremely Fast Python Linter and Code Formatter Written in Rust
Explore Ruff, a high-speed Python linter and formatter in Rust. Learn its functionality, performance optimizations, and design choices that make it significantly faster than alternatives.