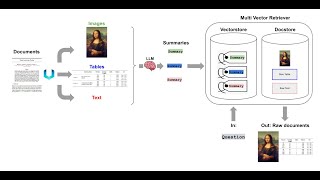
Using LangChain with Multimodal AI to Analyze Images in Financial Reports
Learn to analyze financial reports with images using GPT-4 Vision and LangChain. Explore multimodal RAG techniques, codebase implementation, and result evaluation for enhanced document analysis.

Introduction to Large Language Models - Future and Security Challenges
Comprehensive introduction to Large Language Models, covering their functionality, training, future potential, and security challenges. Explores applications, scaling, tool use, and emerging paradigms in AI.
LLaVA: The New Open Access Multimodal AI Model
Explore LLaVA, a cutting-edge open-access multimodal AI model. Learn about its capabilities, live demo, GitHub repository, research papers, and available models on Hugging Face.
Exploring Gemini 1.5 Pro: Large Context Window and Multimodal Capabilities
Explore Gemini 1.5's capabilities with a 1 million token context window through demos on document querying, code writing, and multimodal processing of video and images.
AI News Roundup - Sora, Gemini 1.5, V-JEPA, and More
Comprehensive overview of recent AI breakthroughs, including OpenAI's Sora, Gemini 1.5, and V-JEPA, with insights on industry developments, model releases, and ethical considerations in AI advancement.
Google I/O 2024 - Key AI Advancements and Their Implications
Explore Google I/O 2024's AI innovations: Gemini upgrades, Veo video generation, Trillium TPUs, enhanced search, and Gemini Nano for Android, revolutionizing user interactions across devices and services.
Gemini: Google's Large Language Model - API Integration and Applications
Explore Gemini, Google's multimodal LLM, and learn to integrate it into applications using Java and LangChain4j. Discover techniques for data extraction, text classification, and knowledge extension with RAG.

Claude 3.5 Sonnet - Anthropic's Latest AI Model Challenging GPT-4
Explore Claude 3.5 Sonnet's advanced capabilities in language, coding, and multimodal tasks. Learn how it compares to GPT-4 and its potential impact on AI development.

Emu Video Generation - From MAE Pre-training to Multimodal Embeddings
Explore Emu Video generation with Ishan Misra from Meta, covering SSL, multimodal data, and recent advancements in video AI technology.
Machine Learning Day: From Generative AI to Vector Databases
Explore cutting-edge Machine Learning topics with expert talks on multimodal generative AI, OpenAI embeddings, vector databases, and building products in the GenAI era.
In Conversation with the Godfather of AI
Explore AI's future and societal impact with Geoffrey Hinton, pioneering AI researcher, as he discusses reasoning, efficiency, jobs, multimodal AI, bias, social policy, and existential risks in AI development.
Meet FLAVA: A Unified Vision and Language Foundation Model
Explore FLAVA, a unified vision and language model, its architecture, and performance across 35 tasks. Learn about the journey towards creating this holistic foundation model for multimodal AI applications.
Getting Started with GPT-4 in Spring AI - Chat and Vision Capabilities
Learn to integrate GPT-4's chat and vision capabilities into Spring applications, enhancing AI functionality for more advanced and interactive features.
Nearest Neighbor Normalization for Improving Multimodal Retrieval
Discover how Nearest Neighbor Normalization enhances multimodal AI retrieval accuracy by addressing hubness problems, improving specificity, and reducing biases - all without additional training.
Understanding Task Vectors in Vision-Language Models - Cross-Modal Representations
Explore how Vision-Language Models create task vectors - internal representations enabling cross-modal performance through text and images, revolutionizing AI's ability to understand and execute diverse tasks.
Multimodal RAG Application Development with LlamaIndex, Google AI, Gemini Pro and Qdrant
Master building multimodal RAG applications using LlamaIndex, Google AI Studio SDK, and Gemini models to extract and process information from images with Qdrant vector storage integration.
에이닷의 이미지 이해와 생성 기술 발전 - AI 이미지 대화와 모션 프로필 서비스
Discover how A.dot evolved to understand and generate images, featuring insights into AI image dialogue systems and motion profile services using advanced Vision AI technology and LLM integration.
Multimodal AI 시대를 준비하는 4D NAND 설계 기술
Discover SK하이닉스의 혁신적인 4D NAND 기술과 멀티모달 AI 시대를 위한 메모리 반도체의 진화 과정을 통해 차세대 메모리 설계의 핵심 기술과 발전 방향을 파악하세요.
Retooling AI Training Sets for Improved Model Performance
Explore DataComp, a benchmark for innovating AI training datasets. Learn how improved data curation outperforms model tweaks, enhancing multimodal AI performance with less compute.

Llama 3.2 - Multimodal and Edge Computing Advancements
Explore Llama 3.2's multimodal capabilities, edge computing potential, and performance benchmarks. Learn about its vision-tuned models, lightweight versions, and integration with Ollama.
Five Trends in Generative AI - Insights from Tom Mitchell
Explore five key trends in generative AI with Tom Mitchell, including advancements in language models, multimodal systems, and open-source development. Gain insights into AI's future applications and implications.