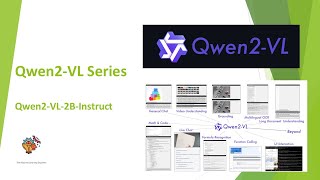
LLM Review: Qwen2 VL 2 Billion Parameter Instruct Model for Data Science and Machine Learning
Explora las capacidades del modelo Qwen2 VL de Alibaba Cloud para análisis de video y respuesta a preguntas mediante ejemplos prácticos.
Roblox's Journey to Supporting Multimodality on vLLM - Ray Summit 2024
Explore Roblox's integration of multimodal language models into vLLM, uncovering technical challenges and insights for developers seeking to enhance their LLM deployments with advanced AI capabilities.
Using Promptable Image Analysis for Clinical Diagnostics - Ray Summit 2024
Explore the integration of LLMs and Vision Transformers for enhanced clinical image analysis. Discover how Ray technologies enable real-time processing of multimodal data, revolutionizing diagnostic workflows in healthcare.
Llama Interprets the World - Unlocking New Possibilities with Multimodal Reasoning
Discover how Llama's latest multimodal reasoning capabilities can enhance chatbots, virtual assistants, and unlock innovative applications for your projects.
LLMs: Revisión de Qwen2 VL - Modelo de Lenguaje Visual de 2 Billones de Parámetros
Explora las capacidades del modelo Qwen2 VL de Alibaba Cloud, con 2 billones de parámetros, para análisis de video y respuesta a preguntas.
Revisión de los Últimos Modelos Multimodales: Gemini Pro 1.5 Flash, OpenAI GPT-4o y Claude 3 Opus
Compara las capacidades de los modelos multimodales más recientes: Gemini Pro 1.5 Flash, GPT-4o y Claude 3 Opus. Explora sus fortalezas y limitaciones.
Multimodal Q&A RAG Tool with Gemini - Spanish Tutorial
Aprende a crear un componente RAG de Q&A multimodal utilizando Gemini para procesar datos no estructurados como imágenes, audio y video.
Large Multimodal Models: From Browsers to Embodied AI
Explore the evolution of large multimodal AI models and their transition from text prediction to real-world applications, emphasizing safety alignment and human-centric design principles for autonomous systems.
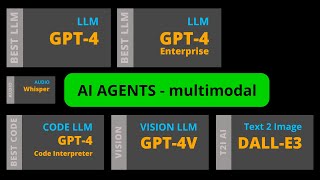
The Future of AI: From Language Models to Multimodal Agents and Video Processing
Explore the cutting-edge developments in AI technology, from multimodal agents to GPT-4's video capabilities, and discover how AI systems are evolving to handle diverse data types and tasks.
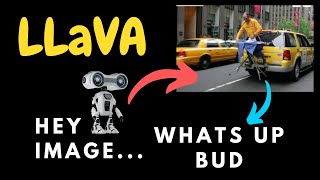
LLaVA: Large Language and Vision Assistant - Understanding the First Instruction-Following Multimodal Model
Discover how LLaVA pioneered instruction-tuned multimodal AI, combining language and vision capabilities to create a groundbreaking Large Multimodal Model for advanced visual understanding and interaction.
Scientific Problem-Solving with GPT-4 Vision - Mathematical Formula Recognition and Python Code Generation
Discover how GPT-4 Vision transforms complex mathematical problem-solving by converting formula images into executable Python code, streamlining scientific calculations and verification processes.
BLIP-2: Connecting Vision-Language Models with Q-Former for Image Chat
Explore BLIP-2's innovative approach to combining vision and language models through Q-Former, enabling advanced image-based conversations and multimodal AI interactions.
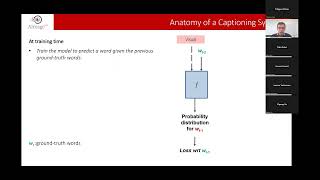
From Images to Text: New Forms of Human-AI Interaction
Explore cutting-edge techniques connecting computer vision and natural language processing, focusing on image-to-text generation, AI controllability, and embodied AI applications.
Multi-Modal Transformer Agents Controlled by StarCoder - Building AI Systems Without LangChain
Explore how StarCoder orchestrates multi-modal transformer agents on HuggingFace Hub, enabling seamless connections between audio, visual, and text transformers for advanced AI applications.
Google Gemini - Technical Report on Model Architecture, Dataset, and Training
Explore Google's Gemini AI model family: architecture, datasets, and performance across text, image, video, and speech benchmarks. Learn how it advances multimodal AI and sets new records.
Convergence of Vision and Language in AI - Recent Developments and Projects
Explore the convergence of vision and language in AI with Lucas Beyer from Google DeepMind, covering topics like ViT, PaLI, and the future of multimodal AI architectures.
Google's Gemini Video Controversy - Analysis and Implications
Analysis of Google's Gemini marketing video, examining its portrayal of AI capabilities and raising questions about authenticity and potential misrepresentation of the model's true abilities.
Google Gemini AI: Comprehensive Overview and Capabilities
Explore Google's Gemini AI: a multimodal model excelling in programming, scientific analysis, math reasoning, and creative tasks. Witness its capabilities in understanding diverse data types and generating innovative solutions.
Gemini and the Future of Generative AI Tools - Interview with Simon Tokumine
Simon Tokumine discusses Gemini, Google's multimodal AI model, exploring its impact on product development and human-machine interactions. He shares insights on AI evolution and its future implications.
Comparing AI Image Caption Models: GIT, BLIP, and ViT+GPT2
Explore a comparison of three cutting-edge AI image captioning models, analyzing their performance across diverse images and understanding their unique approaches to vision-language tasks.
ODSC East 2022 Keynote by Luis Vargas, Ph.D. - The Big Wave of AI at Scale
Explore the trend of larger AI models, their growing capabilities, and impact on language, vision, and multi-modality. Learn about research, engineering efforts, and implications for companies.