Reinforcement Learning III - Advanced Concepts and Applications
Explore advanced reinforcement learning concepts with Stanford's Emma Brunskill, covering cutting-edge techniques and applications in AI decision-making.
Reinforcement Learning in Action - Lecture 3
Explore advanced reinforcement learning concepts and applications in this lecture by Massimo Vergassola, part of a comprehensive series on soft and living matter physics.
Programmatic Strategy Synthesis: Resolving Nondeterminism in Probabilistic Programs
Explore programmatic strategy synthesis for resolving nondeterminism in probabilistic programs using deductive verification techniques and weakest precondition-style frameworks.
Training an Autonomous Pentester with Deep RL
Explore deep reinforcement learning for autonomous pentesting, using Metasploit and simulated networks to train an AI agent capable of compromising real-world vulnerable systems.
Lay Down the Common Metrics - Evaluating Proof of Work Consensus Protocols' Security
Quantitative analysis framework for evaluating security of Proof of Work consensus protocols, revealing vulnerabilities and proposing improvements for blockchain systems.
A Code-Driven Introduction to Reinforcement Learning
Hands-on introduction to reinforcement learning, covering Markov decision processes and RL algorithms. Includes live coding of a GridWorld simulation and practical steps for industrial applications.
Error Bounds for Mean-Payoff Markov Decision Processes
Explore optimal transport techniques for error bounds in reinforcement learning, focusing on mean-payoff Markov decision processes and stochastic fixed point iterations.
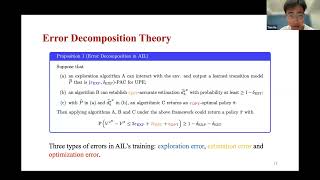
Provably Efficient Adversarial Imitation Learning with Unknown Transitions - Oral Session 4
Explore provably efficient adversarial imitation learning with unknown transitions. Discover a framework connecting reward-free exploration and AIL, and learn about the MB-TAIL algorithm's optimal performance and generalization ability.
A Friendly Introduction to Deep Reinforcement Learning, Q-Networks and Policy Gradients
Friendly exploration of deep reinforcement learning concepts, including Markov decision processes, Q-networks, and policy gradients, using examples and visuals to explain complex ideas.
Haskell for Choice-Based Learning in Machine Learning Programming
Explore language design for machine learning, focusing on choice-based learning. Combine algebraic effects, handlers, and selection monad to create powerful frameworks for decision-making models and optimization techniques.
Hindsight Learning for MDPs with Exogenous Inputs
Explore data-efficient algorithms for resource management problems using Hindsight Learning in Exo-MDPs, outperforming traditional methods in various applications including cloud resource allocation.
Reinforcement Learning via Stochastic Control
Explore reinforcement learning in continuous time and space, examining stochastic control theory's role and recent developments in this emerging field.
Towards Fast Autonomous Learners: Advances in Reinforcement Learning - 2015
Explore reinforcement learning for AI agents interacting with humans, focusing on sample efficiency and transfer learning to improve educational tools and decision-making systems.

Global Guarantees for Policy Gradient Methods
Explore global guarantees for policy gradient methods in reinforcement learning, examining theoretical foundations and practical implications.
Fixed-point Error Bounds for Mean-payoff Markov Decision Processes
Explore optimal transport techniques for deriving finite-time error bounds in reinforcement learning, focusing on mean-payoff Markov decision processes and stochastic fixed point iterations.
Intro to Artificial Intelligence - MDP and Dynamic Programming - Lecture 15
Explore Markov Decision Processes and Dynamic Programming in AI, learning algorithmic techniques for modern problem-solving in game environments.
COMP3200 - Introduction to Artificial Intelligence - MDP and Dynamic Programming - Lecture 16
Explore Markov Decision Processes and Dynamic Programming in AI, learning algorithmic techniques for modern problem-solving in game environments.
Intro to Artificial Intelligence - RL Monte Carlo Methods - Lecture 17
Explore Monte Carlo methods in reinforcement learning, applying algorithmic techniques to solve AI problems in gaming environments.
Introduction to Artificial Intelligence - Lecture 15: Intro to Reinforcement Learning
Explore reinforcement learning fundamentals, including key concepts and applications in AI problem-solving environments for modern algorithmic techniques.
Intro to Artificial Intelligence - Markov Decision Process (MDP) - Lecture 17
Explore Markov Decision Processes (MDPs) in AI, learning algorithmic techniques for modern problem-solving in uncertain environments.

Faster Saddle-Point Optimization for Solving Large-Scale Markov Decision Processes
Explore advanced techniques for optimizing large-scale Markov decision processes using saddle-point methods. Gain insights into theoretical reinforcement learning and linear programming formulations.