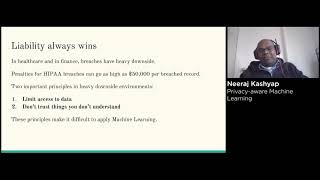
Machine Learning with Sensitive Data: Privacy-Preserving Techniques
Explore open-source ML techniques for sensitive data in finance and healthcare, ensuring privacy while maximizing data utility.
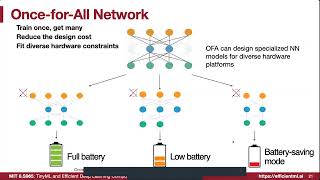
TinyML and Efficient Deep Learning Computing - Course Summary
Explore efficient machine learning techniques for deploying neural networks on resource-constrained devices, covering model compression, pruning, quantization, and more.
TinyML and Efficient Deep Learning Computing - Lecture 24: Course Summary
Explore efficient machine learning techniques for deploying neural networks on resource-constrained devices. Gain hands-on experience with mobile AI and quantum machine learning.
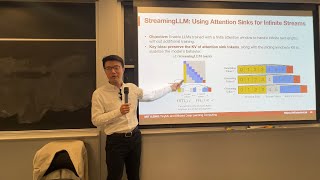
StreamingLLM: Deploying Language Models for Streaming Applications with Long Text Sequences
Explore innovative techniques for deploying LLMs in streaming applications, focusing on the "attention sink" phenomenon and efficient KV cache management.
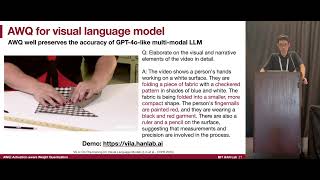
AWQ: Activation-aware Weight Quantization for LLM Compression and Acceleration
Explore activation-aware weight quantization for compressing and accelerating large language models. Learn about AWQ's innovative approach to LLM optimization.
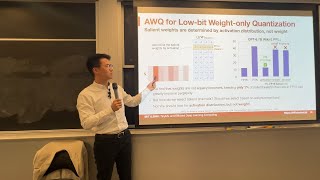
AWQ for LLM Quantization - Efficient Inference Framework for Large Language Models
Explore Activation-aware Weight Quantization (AWQ) for efficient large language model deployment, reducing memory requirements while preserving performance across domains and modalities.
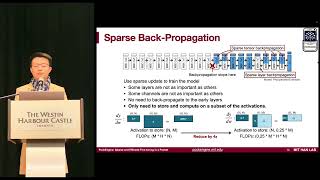
PockEngine: Sparse and Efficient Fine-tuning in a Pocket
Explore sparse and efficient fine-tuning techniques for AI models with PockEngine, enhancing performance while reducing computational demands.

10 Decision Trees are Better Than 1 - Random Forest and AdaBoost
Explore tree ensembles: Random Forest and AdaBoost. Learn bagging, boosting techniques, and their benefits. Apply knowledge to breast cancer prediction using example code.

Dimensionality Reduction and Segmentation with Decision Trees - Python Code
Explore advanced decision tree applications for dimensionality reduction and predictor segmentation, with Python code examples for breast cancer detection and sepsis risk analysis.

The Hugging Face Transformers Library - Beginner's Guide and Chatbot UI with Gradio
Explore the Hugging Face Transformers library for easy, cost-free use of open-source language models. Learn sentiment analysis, summarization, and build a chatbot UI with Gradio.

Fine-tuning Large Language Models (LLMs) with Example Code
Learn to fine-tune large language models with practical Python examples. Explore techniques like LoRA for efficient parameter tuning and implement a text classification model using distilBERT.

AI for Business: A Non-Technical Introduction
Explore AI's business value through a non-technical lens. Learn key concepts, practical applications, and five essential rules for leveraging AI effectively in your organization.

How to Improve LLMs with RAG - Overview and Python Code
Learn to enhance LLMs using Retrieval Augmented Generation (RAG). Explore its principles, implementation, and practical application in improving a fine-tuned model for YouTube comment responses.

Text Embeddings, Classification, and Semantic Search with Python Code
Explore text embeddings for classification and semantic search with Python. Learn to transform text into computable vectors for powerful NLP applications.

How to Deploy Machine Learning Solutions with FastAPI, Docker, and AWS
Deploy ML solutions using FastAPI, Docker, and AWS with a simple 3-step approach. Learn to create APIs, containerize applications, and deploy on cloud platforms for efficient machine learning deployment.
Local LLM Fine-tuning on Mac (M1 16GB) Using QLoRA and MLX
Fine-tune a local LLM on M1 Mac using MLX and QLoRA. Adapt Mistral 7b to respond like you to YouTube comments, with step-by-step guidance and code examples.

Three AI Use Cases for Analyzing Sales Data
Explore three practical AI applications for analyzing sales data, demonstrated with real-world examples from a warm outreach campaign. Learn data augmentation, structuring unstructured data, and lead scoring techniques.
Compressing Large Language Models (LLMs) with Python Code - 3 Techniques
Explore three LLM compression techniques: quantization, pruning, and knowledge distillation. Learn to implement these methods with Python code examples for efficient model optimization.
The Fragmented ML Stack and How to Fix It
Explore the fragmented ML stack, understand Ivy's role in unification, and see demonstrations of function, library, and model transpilation.

Ivy: Quickstart and Introduction to Features - Demo 01
Get up to speed with Ivy's features and capabilities for efficient machine learning development, instant sharing, and optimal deployment.

Routing to Minimize Cost and Latency in Unify - Demo 03
Optimize LLM query routing based on latency, cost, and quality budgets using Unify's Dynamic Routing with thresholds.