Getting a Job in IT Without Experience - Follow This Plan
Comprehensive guide to landing an IT job without experience, covering certifications, networking strategies, interview preparation, and common pitfalls to avoid for aspiring IT professionals.
Automated Metadata Management in Data Lakes - A CI/CD Driven Approach
Discover a CI/CD-driven approach to automated metadata management in data lakes, focusing on balancing development speed, governance, and schema evolution for rapidly growing organizations.
Accelerating Data Science Initiatives with Databricks and Privacera
Explore how Databricks' SQL Analytics and Privacera's governance capabilities integrate to provide rapid, secure data access for advanced analytics while ensuring compliance with privacy regulations.
Growing the Delta Ecosystem - Delta-RS for Rust and Python
Explore delta-rs, a Rust library extending Delta Lake beyond Spark. Learn its current capabilities, roadmap, and real-world application in kafka-delta-ingest for high-throughput data transfer.
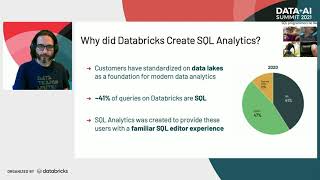
Building Lakehouses on Delta Lake with SQL Analytics
Learn to build lakehouses using Delta Lake, perform SQL analytics, and connect BI tools. Explore data management techniques, governance models, and implementation examples for efficient data processing and analysis.
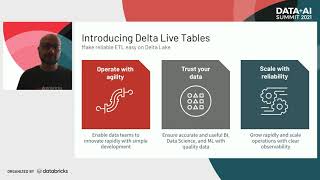
Make Reliable ETL Easy on Delta Lake
Learn to simplify ETL development on Delta Lake, improving data quality and scaling operations. Discover how Databricks streamlines the ETL lifecycle for efficient data engineering and management.
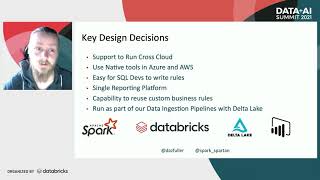
Building Data Quality Pipelines with Apache Spark and Delta Lake
Learn to build robust data quality pipelines using Apache Spark and Delta Lake. Explore rule templates, reporting models, and PowerBI integration for effective data remediation and self-healing in enterprise environments.
Why Lakehouse Architecture Now - Exploring Enterprise Data Warehouse Failures and the Need for Lakehouse Paradigm
Explore the shift from enterprise data warehouses to lakehouse architecture, focusing on benefits, challenges, and Starburst's role in powering SQL-based analytics on Delta Lake.
Creating a Lakehouse on AWS
Learn to build a Lakehouse on AWS, combining data lake affordability with data warehouse performance. Discover integration with AWS services and real-world examples of high-performance, cost-effective analytics solutions.
Democratizing Data - Leadership Insights from Rolls-Royce's CIDO - Episode 1
Explore data democratization with Rolls-Royce's CIDO Stuart Hughes. Learn about disruptive leadership, simplified data architecture, and empowering data teams to unlock the true potential of data.
Accelerating MLOps with Apache Spark and SingleStore
Learn to accelerate MLOps using Apache Spark and SingleStore. Discover how to build fast analytical applications, manage supervised learning models, and scale AI/ML operations for data science success.
Cost Efficiency Strategies for Managed Apache Spark Service with Databricks
Explore cost-efficient strategies for Azure Databricks, including resource management, tier selection, and best practices for optimizing Apache Spark workloads in a managed cloud environment.
Delta Lake: Optimizing Merge Operations
Explore Delta Lake merge optimization techniques, including inner and full outer joins, partition pruning, and file pruning. Learn tips for handling large merges efficiently.
Diving into Delta Lake: Understanding the Transaction Log
Explore Delta Lake's transaction log: its structure, functionality, and role in ACID transactions, metadata handling, time travel, and concurrent operations. Gain insights into this core component.
SQL Analytics and the Lakehouse Architecture - Data + AI Summit EU 2020 Keynote
Explore lakehouse architecture, Delta Lake, and SQL Analytics for unified data management. Learn how this approach combines data warehouse capabilities with data lake flexibility, enabling faster analytics and decision-making.
Designing the Next Generation of Data Pipelines with Apache Spark - Zillow's Approach
Zillow's data engineering team shares their journey in redesigning data pipelines using Apache Spark, focusing on scalability, maintainability, and robustness while reducing code complexity.
Simplify and Boost Spark 3 Deployments with Hypervisor-Native Kubernetes
Explore integrating Spark 3 with VMware Pacific for scalable, reliable, and high-performance big data analytics deployments using hypervisor-native Kubernetes on vSphere 7.
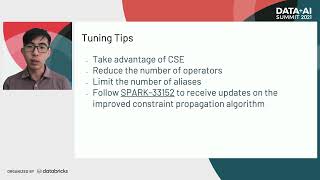
Optimizing Catalyst Optimizer for Complex Spark Plans
Optimizing Spark's Catalyst optimizer for complex plans with thousands of operators and large case statements. Techniques include memory-efficient logging, subexpression elimination, and improved constraint propagation.
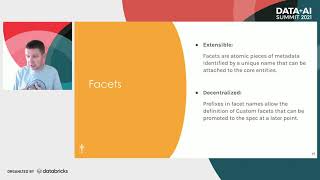
Observability for Data Pipelines with OpenLineage
Explore data pipeline observability using OpenLineage, enhancing reliability and auditability. Learn how metadata collection enables understanding of data flow and dependencies across teams and technologies.
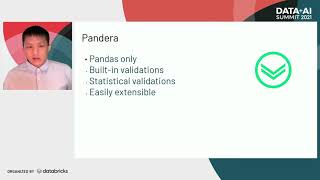
Fully Utilizing Spark for Data Validation with Fugue and Pandera
Explore lightweight data validation for Spark using Fugue and Pandera, enabling partition-specific rules and efficient big data processing without compromising on functionality.
Data Quality Tools Comparison for Continuous Data Imports
Comparison of open-source data quality tools for continuous imports, covering maturity, documentation, extensibility, and features like data profiling and anomaly detection.