Linux Power Management Features, Their Relationships and Interactions
Explore Linux kernel power management features, their interactions, and potential conflicts, using real-world examples from automotive SoC development.
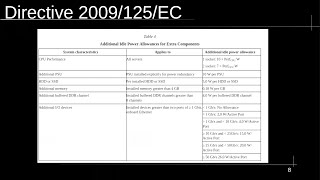
Power Efficiency of Modern Servers
Explore power distribution in servers, analyze efficiency improvements, and examine the impact of inlet temperature changes on data center energy consumption.
When Clusters Collide: The Misadventures of Disaster Recovery in Kubernetes
Explore Kubernetes disaster recovery challenges, from DNS management to data replication. Learn best practices for handling cluster collisions and implementing comprehensive DR configurations.
Kube-Nation: Exploring the Land of Kubernetes
Explore Kubernetes fundamentals through an interactive journey. Learn key concepts, deployment strategies, and best practices for managing containerized applications in a cloud-native environment.
Unlocking Insights Through Incident Management Reports
Discover how to leverage incident management reports for valuable insights, improve resource allocation, and enhance customer experience through data-driven decision-making.
Pragmatic Automation Strategies for Incident Management
Explore pragmatic automation strategies for incident management, leveraging AI and existing tools to enhance efficiency, analysis, and response in IT operations.
IT Incident Management Training and Assessment Using Generative AI
Explore innovative IT incident management training using generative AI. Learn critical skills through immersive solutions and discover how AI enhances the learning experience.
Cost and Resource Optimization in Kubernetes
Optimize Kubernetes costs and resources: Learn strategies for efficient resource allocation, scalability, and cost management using various tools. Includes practical demo.
Leveraging Incidents to Align Platform and Product Engineering
Discover strategies to align platform and product engineering through incident management, enhancing collaboration and system reliability.
Solving Migration Pipelines
Explore strategies for solving migration pipeline challenges in cloud-native environments, focusing on efficiency and scalability.
The Legend of the Arsonist Firefighter
Explore the intriguing tale of the arsonist firefighter in cloud-native environments, uncovering lessons on system reliability and incident response.
KubeVirt Alchemy - Transforming VMs into Kubernetes Workloads
Explore KubeVirt's ability to transform VMs into Kubernetes workloads. Learn deployment techniques, management strategies, and see a live demo showcasing practical implementation.
Building a Network Telemetry Platform
Explore network telemetry platform development, covering architecture, data processing, security implementation, cloud integration, and scalability for enhanced network monitoring and management.
Starting the SLOs Implementation
Learn to implement Service Level Objectives (SLOs) effectively, enhancing system reliability and performance in site reliability engineering practices.
Bell the "Chaotic Cat" with Site Reliability Engineering
Explore SRE practices for managing unpredictable systems using the "Chaotic Cat" analogy, enhancing reliability and resilience in complex environments.
What is a Data Mesh? - Understanding Decentralized Data Architecture
Explore data mesh architecture, its principles, and implementation strategies for scalable, domain-oriented data management in cloud-native environments.
Event-Driven Change Data Capture Pattern
Explore event-driven Change Data Capture patterns and their implementation using Apache Pulsar for efficient, real-time data synchronization in cloud-native environments.
DevOps Best Practices for DataOps Mesh
Discover DevOps best practices for implementing DataOps Mesh, enhancing data management and collaboration in complex environments.
Let Your Kubernetes Environment Flourish
Optimize Kubernetes environments for peak performance and security. Learn strategies to enhance resource management and safeguard deployments.
Moving from OpenStack Magnum to the Cluster API
Explore the transition from OpenStack Magnum to Cluster API for managing Kubernetes clusters, highlighting key differences and benefits.

Deep Dive into Data Mesh Principles
Explore Data Mesh principles: domain ownership, data as product, self-serve platform, and federated governance for modern business success.