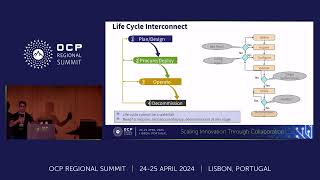
Data Center Life Cycle Manageability at Scale - A Blueprint for Hyperscale Evolution
Explore scalable data management strategies for hyperscale data centers, focusing on lifecycle representation, fleet asset management, and evolving architectural requirements.
Scaling Down While Scaling Up - Design Choices That Increase Efficiency and Performance
Discover how innovative design approaches in hyperscale systems optimize performance while reducing complexity, costs, and carbon footprint through collaborative hardware, software, and operational strategies.
Building the Compute Infrastructure of the Future - From Sustainable Silicon to Intelligent Clouds
Explore the evolution of warehouse-scale computing and future innovations in cloud infrastructure, AI-ML computing, and sustainable technology through Google's 25-year journey and upcoming developments.
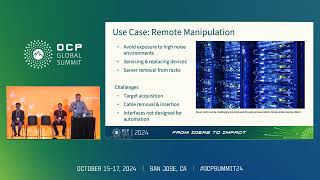
Data Center Automation: Robotic Physical Manipulation for Hyperscale Operations
Explore how leading tech giants leverage robotic automation to enhance data center operations, efficiency, and safety while addressing scaling challenges and future automation solutions.
Link Delay Measurement Using Peer-to-Peer Transparent Clocks (P2P TC)
Discover how Peer-to-Peer Transparent Clock technology enables precise link delay measurements in networks, with insights into hyperscaler applications and SAI specification updates.
GPU Profiles for Hyperscale Use Cases - Redfish Interoperability and Management
Explore GPU tray management through Redfish Interoperability Profiles, focusing on compliance testing, vendor adoption, and practical implementation for hyperscale environments.
OCP Hyperscale-Compliant AI Storage Servers with Compression and Deduplication Accelerators
Explore cutting-edge hyperscale AI storage solutions featuring advanced compression and deduplication technologies for optimized data management in enterprise environments.
Real World Implementation of the OCP Hyperscale CXL TME Specification
Explore practical implementations of OCP's Hyperscale CXL TME specification, examining real-world applications and technical considerations for memory expansion solutions.
Open Network Switching for Hyperscale Cloud AI Infrastructure
Explore how open networking architectures can revolutionize cloud AI infrastructure, enabling greater flexibility, scalability, and innovation for hyperscale operators.
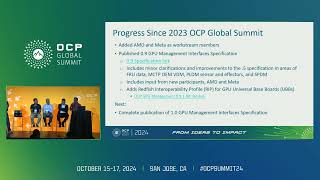
Standardizing Hyperscaler Requirements for GPU Management and Acceleration
Discover how leading tech companies are standardizing GPU management in hyperscale data centers using DMTF standards, focusing on accelerating implementation and adoption of new GPU designs.
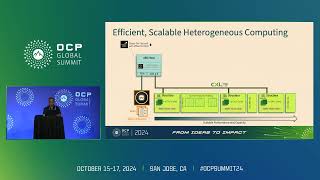
Memory Wall Mitigation and Acceleration of AI Workloads Using CXL Near Memory Computing
Explore CXL-based Near Memory Compute architectures for hyperscale environments, focusing on acceleration solutions for data-intensive workloads and memory optimization techniques.
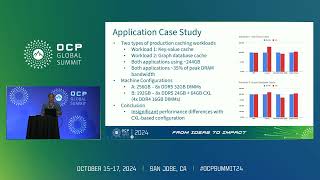
Launching CXL Memory in Hyperscale Deployments with a Holistic CXL Ecosystem
Explore the critical components and implementation strategies for deploying CXL memory solutions in hyperscale environments, focusing on tiered memory use cases and system interoperability.
MAST: Global Scheduling of ML Training across Geo-Distributed Datacenters at Hyperscale
Intelligent global scheduling system for ML training workloads across datacenters, optimizing resource utilization and eliminating regional overload through innovative design principles.
ServiceLab: Preventing Tiny Performance Regressions at Hyperscale through Pre-Production Testing
Explore Meta's ServiceLab platform for detecting minute performance regressions in large-scale systems, addressing challenges in noisy cloud environments through statistical analysis and machine factor studies.
Infrastructure Software for Hyperscale AI and GPU Clusters
Explore cutting-edge infrastructure software solutions powering large-scale AI operations and GPU cluster management for hyperscale computing environments.
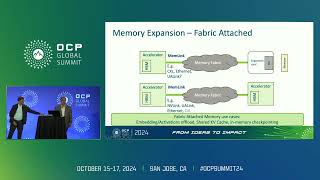
Memory Expansion Requirements for AI Systems in Hyperscale Data Centers
Explore evolving memory architecture requirements for AI systems in hyperscale data centers, focusing on GPU acceleration and infrastructure optimization for next-generation applications.
Building Hyperscale Cloud-Native SDN with Kubernetes - A Journey in Network Control Plane Transformation
Explore cloud-native SDN transformation using Kubernetes for enhanced scalability, achieving 30x port throughput and 75% VM boot time reduction through distributed micro-services architecture.

SNIA Swordfish - A Unified Approach to Open Storage Management
Discover how DMTF Redfish and SNIA Swordfish provide unified storage management for cloud environments, including configuration locking, audit logging, and recent functionality updates for hyperscale deployments.