Keeping the Bricks Flowing: The LEGO Group's Approach to Platform Engineering for Manufacturing
Explore LEGO's innovative platform engineering approach for manufacturing, focusing on Kubernetes, chaos engineering, and user engagement to ensure continuous production of bricks.

Architecting Growth: Scaling Tactics for Prometheus Metrics Collection
Explore scaling strategies for Prometheus metrics collection, from vertical scaling to high-availability and autoscaling with HPAs. Learn how Prometheus-Operator simplifies scaling operations.
Architecting Resilience: Lessons from Managing 7000+ Kubernetes Clusters at Scale
Insights on designing highly available Kubernetes clusters, addressing challenges in managing 7K+ clusters and 100K+ nodes, and lessons learned from a data center fire incident.
Kubernetes Resiliency: From Infrastructure to Applications - Devoxx Greece 2024
Explore Kubernetes resiliency strategies for infrastructure, components, and applications. Learn to identify and address single points of failure, optimize resource management, and implement robust monitoring techniques.
Open Source Databases on Kubernetes: Best Practices
Discover best practices for running open-source databases on Kubernetes, covering high availability, security, backups, and disaster recovery using Percona Operators.
Autoscaling vs High Availability in Kubernetes
Explore Kubernetes autoscaling and high availability strategies, including scheduling, load balancing, and HA implementation in large-scale clusters.
Aspects of Dependable Linux Systems
Explore key aspects of building reliable and robust Linux systems with insights from industry experts.
Red Hat Hyperconverged Infrastructure - Your Open Hyperconverged Solution
Explore Red Hat's open hyperconverged solution, its current benefits, and future roadmap. Learn about planned capabilities like deduplication and compression, and how they can enhance your business operations.
Oracle Maximum Availability Architecture Best Practices for OCI
Explore Oracle's integrated MAA best practices in OCI for eliminating downtime, increasing scalability, and ensuring zero data loss. Learn about HA and DR features to optimize business continuity.
Simplify Application Development with Oracle Real Application Clusters
Discover how Oracle Real Application Clusters simplifies development, enhances scalability, and ensures rapid recovery from failures without complex coding, allowing developers to focus on core business logic.
Never-Down Applications with Oracle Maximum Availability Architecture - Oracle Database World
Explore Oracle's Maximum Availability Architecture for full-stack data protection, ensuring uninterrupted applications and high availability across database and middle-tier layers.

From Zero to Serverless in 60 Seconds, Anywhere
Learn to deploy serverless applications using Docker and Swarm, exploring Functions as a Service, secrets, metrics, and auto-scaling for efficient and resilient hardware utilization.
The Solution for Stateful Containers
Learn to overcome common challenges in running containerized apps in production, including data persistence, high availability, and automated management across various infrastructures.
Red Hat Enterprise Linux OpenStack Platform High Availability
Explore options for maximizing OpenStack uptime and mitigating risks using Red Hat Enterprise Linux OpenStack Platform. Learn about high availability, easy deployment, and distributed layouts for fault-tolerant, scale-out workloads.
Making and Keeping Netflix Highly Available - The Role of Mesos in Operational Insights
Explore Netflix's high availability strategies, focusing on Mesos for operational insights and real-time monitoring in large-scale distributed systems.
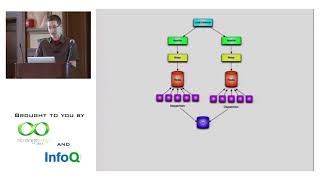
High Availability at Braintree
Explore high availability strategies at Braintree, including traffic pausing, rolling deploys, load balancing, and error handling, to minimize downtime and maintain seamless payment processing.
Availability, Latency, and Cost - Withstanding Regional Outages
Explore Netflix's multi-region strategy for improved availability and latency, including algebraic models, incident management, and design considerations for efficient failovers and user steering.
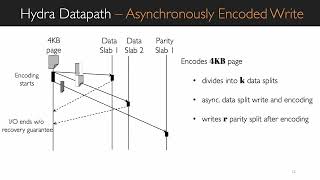
Hydra - Resilient and Highly Available Remote Memory
Resilient remote memory system with low latency, high availability, and efficient erasure coding. Improves performance-efficiency tradeoff and reduces data loss probability under correlated failures.
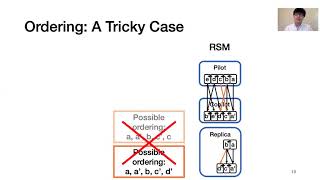
Tolerating Slowdowns in Replicated State Machines Using Copilots
Innovative consensus protocol for replicated state machines that maintains normal latency despite slowdown of any single replica, using pilot and copilot for redundancy and fast takeovers.

Systems That Run Forever - Self-Heal and Scale
Explore architectural principles for building scalable, fault-tolerant systems using isolated parallel components, error detection, and live code upgrades, with insights from Erlang's design.

Reducing Microservice Complexity with Kafka and Reactive Streams
Explore how to simplify microservices using Kafka and Reactive Streams, focusing on latency reduction, back-pressure, high availability, and message payload evolution.