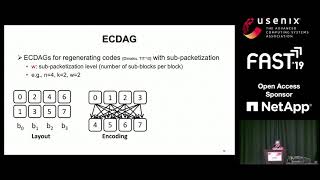
OpenEC - Toward Unified and Configurable Erasure Coding Management in Distributed Storage Systems
Unified framework for deploying erasure coding solutions in distributed storage systems, simplifying integration and optimizing repair performance.
SQL Server Big Data Clusters Architecture
Explore SQL Server 2019 Big Data Clusters architecture, including containers, Kubernetes, Spark, and HDFS. Learn to unify data sources, run big queries, and implement data preparation in an end-to-end scenario.
Analyzing Configuration of Cellular Networks at Nokia with Apache Hadoop, Apache Spark, and Presto SQL
Explore big data solutions for cellular network configuration analysis using Apache Hadoop, Presto SQL, and related technologies. Learn about challenges, pitfalls, and optimizations in building a massively parallel processing system.
Hadoop Essentials for the SQL Server Professional
Learn Hadoop essentials, including HDFS, MapReduce, and Hive, with a focus on comparisons to SQL Server. Explore on-premises and cloud options for implementing Hadoop ecosystems.
The ABCs of BDCs - Big Data Clusters for Beginners
Explore SQL Server 2019's Big Data Clusters: architecture, deployment, and capabilities for combining relational and non-relational data, enhancing your big data skills and career prospects.
A Case Study in API Cost of Running Analytics in the Cloud at Scale with an Open-Source Data Stack
Explore cloud analytics cost optimization through Uber's case study, examining I/O strategies and performance-cost trade-offs in cloud-native environments versus traditional HDFS deployments.
Data Caching for Enterprise-Grade Petabyte-Scale OLAP
Explores Alluxio local cache for petabyte-scale OLAP, optimizing data transfer efficiency in decoupled compute-storage models. Shares insights from Uber and Meta deployments.
Implementing HDFS ACLs in OneFS - A Guide to POSIX.1e Style Access Control Lists
Dive into POSIX.1e ACLs implementation in multiprotocol environments, exploring security model interactions, multithreading challenges, and practical translation methods between different ACL types.