Fast Vector Query Processing for Large Datasets Beyond GPU Memory with Reordered Pipelining
Innovative GPU-accelerated system for efficient vector query processing on large datasets, overcoming memory limitations and outperforming existing solutions in performance and cost-effectiveness.
Real-World PyTorch: From Zero to Hero in Deep Learning and LLMs - Tensors, Operations, Model Training
Comprehensive PyTorch tutorial covering tensors, operations, GPU usage, datasets, neural networks, and model training. Hands-on examples for mastering deep learning and LLMs.
Accelerating AI Workloads with GPUs in Kubernetes
Explore GPU acceleration for AI in Kubernetes, covering resource-sharing, configuration, scheduling, and scalability. Learn key capabilities and challenges for efficient AI/ML workloads in cloud environments.
Enable GPU-Acceleration Without Worrying About Managing Device Drivers
Discover an operator-based approach for seamless GPU driver management in Kubernetes, enabling AI/ML workloads with minimal disruption and supporting diverse hardware configurations.
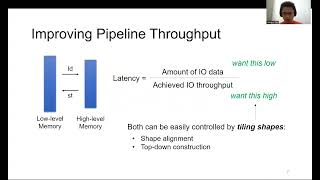
ROLLER - Fast and Efficient Tensor Compilation for Deep Learning
Introduces ROLLER, a fast tensor compilation approach for deep learning using rTile abstraction and recursive construction, generating efficient kernels in seconds for various accelerators.
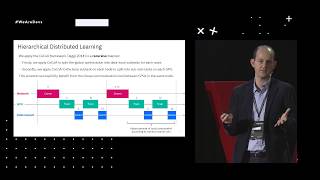
Snap ML - A Highly-Accelerated, Scalable Software Library for Machine Learning
Discover Snap ML, a high-performance framework for training generalized linear models. Learn about its GPU acceleration, pipelining, and distributed computing capabilities for faster machine learning on large-scale datasets.
VectorVisor - A Binary Translation Scheme for Throughput-Oriented GPU Acceleration
Explore VectorVisor, a novel GPU acceleration approach for server-side applications, offering improved throughput and cost-efficiency through vectorized binary translation and CPU thread emulation.
GPU Acceleration of a Global Atmospheric Model Using Python Based Multi-Platform
Explore GPU acceleration for global atmospheric models using PyMIP, a Python module integrating C, Fortran, CUDA, and OpenCL. Learn about performance improvements and multi-platform compatibility for weather forecasting and climate prediction.
Production Multi-node Jobs with Gang Scheduling, K8s, GPUs and RDMA
Explore distributed execution of DL/ML jobs in Kubernetes, covering gang scheduling, GPU acceleration, and high-speed networking for improved performance and scalability.
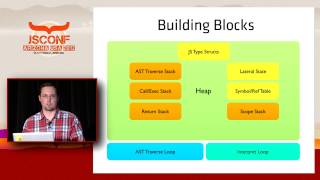
JavaScript on the GPU
Explore GPU-accelerated JavaScript programming techniques for enhanced performance and efficiency in web applications.
Ochre - Highly Portable GPU-Accelerated Vector Graphics
Explore GPU-accelerated vector graphics with Ochre, a Rust library designed for portability across diverse hardware. Learn about performance optimization and API design for modern user interfaces.
MLOps: Using GPUs in Local, Docker, and Docker Compose Environments
Aprende a instalar PyTorch con soporte GPU y configura Docker y Docker Compose para aprovechar el poder de procesamiento gráfico en tus proyectos de aprendizaje automático.
Bringing LLMs Everywhere Through Machine Learning Compilation
Explore machine learning compilation techniques to deploy large language models on diverse devices, from PCs to mobile phones, using GPU acceleration and Apache TVM.
Accelerating Python Code with Numba and CuPy for Machine Learning
Boost Python code execution with GPU acceleration and compilation using Numba and Cupy for machine learning tasks.
GPU Accelerated Containers on Apple Silicon with libkrun and podman machine
Explore GPU-accelerated containers on Apple Silicon using libkrun and podman machine. Learn to run AI workloads efficiently in containers, leveraging macOS hardware for optimal performance.
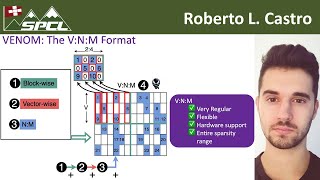
VENOM: A Vectorized N:M Format for Unleashing the Power of Sparse Tensor Cores
Explore VENOM, a vectorized N:M format for sparse tensor cores. Learn about high-performance sparse libraries and second-order pruning techniques for efficient deep learning model sparsification.
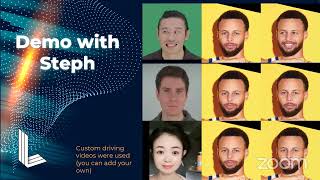
LivePortrait - Efficient Portrait Animation with Stitching and Retargeting Control
Innovative framework for video-driven portrait animation, balancing efficiency and control. Utilizes implicit keypoints, large-scale training, and advanced modules for superior performance and speed.
Best of Java Performance - JVM Language Summit 2024 Highlights
Explore cutting-edge JVM advancements: Valhalla, Leyden, Lilliput, and Babylon projects. Discover performance improvements, faster startup, better memory management, and GPU acceleration for Java.
Quant-LLM: Accelerating Large Language Model Serving via FP6-Centric Algorithm-System Co-Design
Innovative GPU kernel design enables efficient 6-bit quantization for large language models, significantly improving inference speed while maintaining quality across various applications.
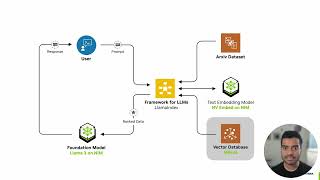
Building LLM Assistants with LlamaIndex, NVIDIA NIM, and Milvus - LLM App Development
Learn to create a Q&A chatbot using NVIDIA NIM for embeddings, Milvus for storage, Llama3 for inference, and LlamaIndex for seamless integration in this comprehensive tutorial.
Optimizing the Performance of Machine Learning in Enterprise Java SaaS with GraalVM, Python and CUDA
Enhance Java SaaS with GraalVM: integrate Python ML libraries, leverage GPU acceleration for model training, and implement recommender systems in enterprise applications.