Feature Engineering - Introduction to Dplyr Part 4
Learn advanced dplyr techniques for feature engineering, including imputing missing values, creating new columns, and combining datasets. Master data manipulation skills to enhance your R programming toolkit.
Introduction to Text Analytics with R - Overview
Explore text analytics with R: tokenization, feature engineering, classification models. Learn data cleaning, analysis, and visualization using a spam dataset. Practical introduction for aspiring data scientists.
The Key to Unlock AI Accuracy Through Feature Generation
Discover how sophisticated feature generation acts as the cornerstone for developing accurate and effective AI models, illustrated through real-world examples from DeepMind and global corporate implementations.
Building a Recommendation System for EPAM Systems
Discover how EPAM Systems builds and implements recommendation systems, exploring ML approaches, business goals, feature engineering, quality metrics, and monitoring strategies in production.
Xavier Amatriain on Practical Deep Learning Systems - November 2019
Practical insights on deep learning systems, covering data handling, model selection, architecture engineering, and real-world implementation challenges in various domains.
Leveraging Argo Workflows and Argo Events for Cloud Agnostic Enterprise Machine Learning Deployments
Explore implementing Argo Workflows and Events for efficient MLOps, including continuous deployment, model retraining, and best practices for cloud-agnostic machine learning pipelines.
Should We Teach Machine Learning Systems?
Explore feature engineering and instruction in machine learning to improve AI system output quality and reliability. Contrast with current hands-off learning approaches.
Feature Engineering and Modeling Techniques for Menu Design at HelloFresh
Discover how HelloFresh uses data-driven approaches to optimize menu design, predict recipe performance, and align product offerings with customer preferences and business strategies.
How to Build a Real-Time ML Pipeline for Fraud Prediction
Build a real-time ML pipeline for fraud prediction, addressing challenges in online feature engineering and real-time data ingestion. Learn to generate ML features, use a feature store, and monitor for drift.
LLMs for Automated Data Science - Introducing CAAFE for Context-Aware Automated Feature Engineering
Discover how CAAFE leverages large language models to enhance automated feature engineering in data science, improving model performance through context-aware feature generation and semantic understanding.
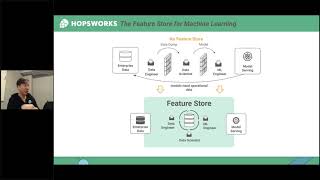
Hopsworks - The Python-Centric Enterprise Feature Store
Explore Hopsworks feature store for Python-centric ML operations, covering feature engineering, pipelines, and real-time serving with an end-to-end use case demonstration.
Discussing All the Types of Feature Transformation in Machine Learning
Comprehensive overview of feature transformation techniques in machine learning, covering standardization, scaling, MinMax, Robust Scalar, and Gaussian transformations for data preprocessing.
Feature Engineering Importance - Practical Application for Feature Engineering
Explore feature engineering techniques for data analysis and classification, including practical application to supermarket sales data. Learn to select, manipulate, and transform features for improved model performance.
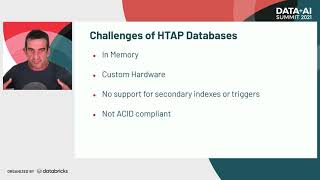
Unified MLOps: Feature Stores and Model Deployment
Explore a new MLOps approach merging databases, feature stores, and ML for scalable model production. Learn about Splice Machine's hybrid database and its applications in feature engineering and model deployment.
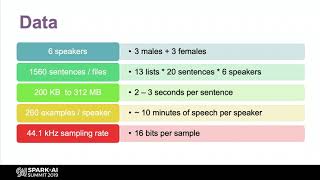
Listening at the Cocktail Party - Deep Neural Networks for Speech Separation
Explore deep neural networks for speech separation, focusing on data preparation, network architectures, and real-time implementation on embedded devices for smart audio applications.
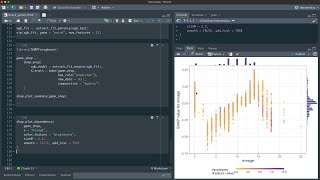
Feature Engineering & Interpretability for XGBoost with Board Game Ratings
Explore advanced modeling with board game ratings data: feature engineering, XGBoost tuning, and explainability methods for data-driven insights and predictive analysis.
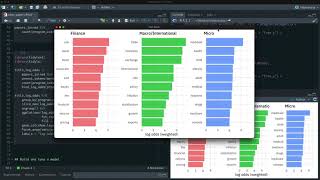
Tune and Evaluate a Multiclass Lasso Model for NBER Working Papers
Explore multiclass lasso modeling for economic research papers, covering data analysis, feature engineering, model tuning, and evaluation using #TidyTuesday data.
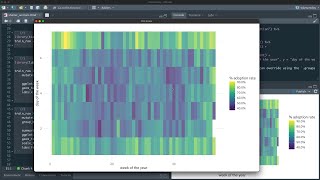
Tune XGBoost With Early Stopping to Predict Shelter Animal Status
Learn to optimize xgboost models using early stopping techniques for predicting animal shelter outcomes, featuring practical examples and efficient coding strategies.
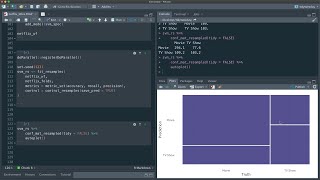
Build Features for Machine Learning from Netflix Description Text
Learn to build machine learning features from Netflix description text and train a support vector machine model using tidymodels, exploring data analysis, feature engineering, and model evaluation techniques.
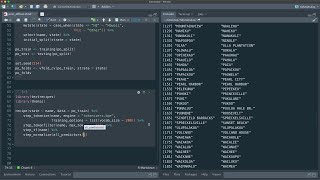
Subword Features in Machine Learning for Text
Explore machine learning techniques for text analysis using tidymodels to predict Hawaii post offices from their names, with practical code examples and performance evaluation.
Model Optimization - Series Conclusion - Introduction to Text Analytics with R
Optimize text analytics models, explore sensitivity/specificity tradeoffs, and discover resources for further study in R. Learn feature engineering and algorithm selection for improved effectiveness.