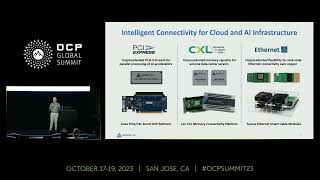
Delivering Unprecedented Scale for AI Infrastructure and Cloud Connectivity
Discover how purpose-built connectivity solutions like PCIe, CXL, and Ethernet overcome performance bottlenecks and scale memory bandwidth, processing, and rack connectivity for AI infrastructure.
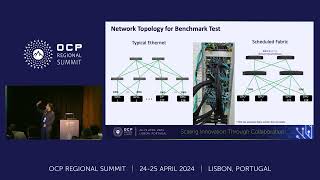
Scheduled Ethernet Fabric for Large-Scale AI Training Clusters
Discover how Scheduled Ethernet Fabric optimizes large-scale AI training clusters, enabling efficient GPU connectivity, workload management, and resilient networking for enhanced computational performance.
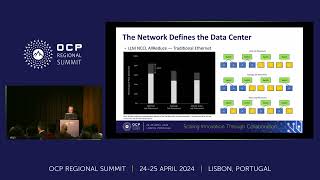
NVIDIA Spectrum-X Network Platform Architecture for AI Cloud Performance
Dive into NVIDIA's Spectrum-X networking innovations, exploring how this Ethernet platform revolutionizes AI cloud performance through advanced routing, telemetry, and multi-tenant capabilities.
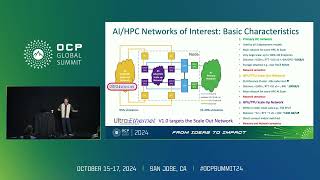
Ultra Ethernet Overview for AI and HPC Workloads
Discover how Ultra Ethernet technology enhances AI and HPC workloads, exploring its current state and key advantages for high-performance computing environments.
Falcon Reliable Transport: High-Performance RDMA at Data Center Scale
Discover Intel's FalconRT technology for high-performance RDMA transport, enabling efficient data center networking with hardware-assisted optimization and backward compatibility for existing infrastructure.
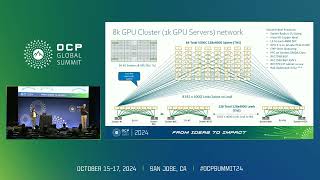
Orchestration Needs for AI Clusters at Scale - Lessons Learned from Two Leading Providers
Discover practical insights into managing large-scale AI clusters, focusing on orchestration solutions, deployment automation, and performance optimization for thousands of switches and network links.
Optimizing Networks with Infrastructure Processing Units for Cloud and Enterprise
Discover how Infrastructure Processing Units (IPUs) revolutionize datacenter performance through secure workload acceleration, improved CPU utilization, and next-generation transport protocols for cloud and AI connectivity.
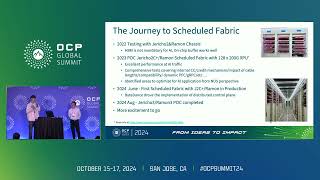
Insights from Production Scheduled Ethernet Fabric in Large AI Training Clusters
Discover how ByteDance implements Scheduled Ethernet Fabric to optimize networking performance and scalability in large-scale AI training clusters with thousands of xPU units.
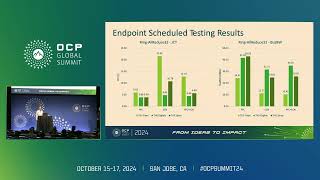
Congestion Management in Ethernet-Based Networks for AI Cluster Fabric
Explore advanced congestion control methods for AI cluster fabrics, focusing on endpoint and fabric scheduling to optimize network performance, minimize latency, and maximize throughput.
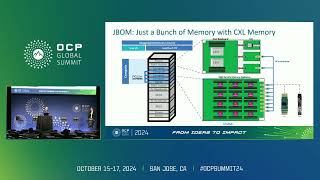
PCIe Active Electrical Cables (AECs) for Large Language Model (LLM) Computing Clusters
Explore the evolution and implementation of PCIe Active Electrical Cables (AECs) for GPU clustering in Large Language Models, focusing on retimer technology advantages and form factor considerations.
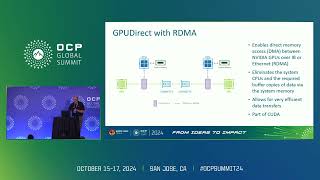
Memory Fabrics: Comparing Ethernet, InfiniBand, and NVLink Technologies
Explore memory fabric technologies - Ethernet, InfiniBand, and NVLink - and their optimal applications for AI and data-centric computing, comparing performance benefits and cost considerations.
Can Interconnects Keep Up with AI? - A Network Performance Analysis
Explore the future of AI infrastructure as industry expert Andy Bechtolsheim examines how interconnect technologies are evolving to meet the demanding requirements of artificial intelligence systems.
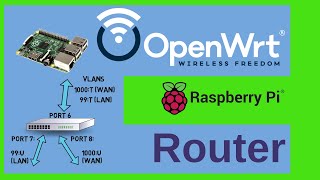
Building a Router with Raspberry Pi and Managed Switch VLANs Using OpenWrt
Transform a Raspberry Pi into a router using OpenWrt, a managed switch, and VLANs. Learn hardware setup, software configuration, security considerations, and performance optimization techniques.
OpenWRT - Realtek RTL8125B 2.5GbE Network Adapter Overview and Testing
Explore Realtek RTL8125B 2.5GbE adapter with OpenWRT: unboxing, setup, performance testing, and power consumption analysis on Zimaboard. Gain insights into network interface configuration and throughput capabilities.
EtherNET: The Present and Future of Datacenter and Supercomputer Interconnects
Explore the role of Ethernet in modern datacenters and supercomputers, examining its current state and future prospects in high-performance computing environments.

PortFast and STP Toolkit - CCNA 200-301 Course - Day 21 Part 1
Learn about PortFast in STP, enabling immediate port forwarding. Covers configuration methods, trunk port usage, and PortFast edge for efficient network setup and reduced delays.
UNIX on the PDP-11 - Installing 211BSD and Connecting to the Internet
Experience classic computing as Dave installs 211BSD Unix on a PDP-11/83, connects it to the internet, and showcases iconic games like Zork and Star Trek on vintage hardware.
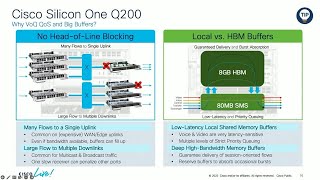
Cisco Catalyst 9500X-60L4D High Speed Ethernet Deep Dive
Dive into advanced networking capabilities of Cisco Silicon One technology, exploring 50GbE optics implementation, datacenter optimization, and service delivery improvements for enterprise networks.
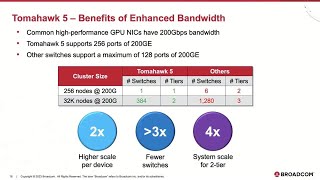
Tomahawk 5 AI Interconnect and Network Fabric Architecture
Explore Broadcom's Tomahawk AI fabric technology, featuring 800 GigE ports, advanced load balancing, and intelligent routing for optimized network performance in large-scale AI infrastructures.
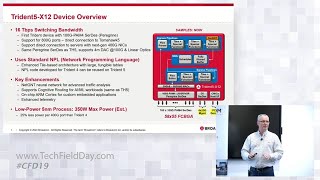
Trident5-X12 - Enhancing Cloud Infrastructure with Advanced Network Processing
Discover how Broadcom's Trident5-X12 chip revolutionizes cloud networking with NetGNT inference engine, enabling real-time traffic analysis, enhanced security, and support for 800G Ethernet ports at line rate.
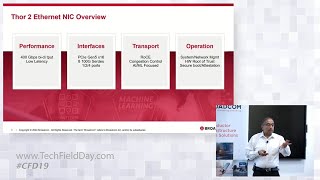
High-Performance Ethernet NIC for AI/ML - Thor 2 Architecture and Features
Explore high-performance networking solutions for AI/ML clusters, focusing on Broadcom's Thor 2 Ethernet NIC features, including RoCE support, congestion control, and end-to-end fabric management for optimal cluster performance.