Log Support in OpenTelemetry
Explore OpenTelemetry's log support, including data model, implementation in Java, collector support, and future plans. Learn about instrumentation libraries and log collection.
Open Policy Agent Intro
Introduction to Open Policy Agent: A versatile policy engine for Kubernetes, microservices, CI/CD, and cloud. Learn about its features, use cases, and the OPA Gatekeeper project.
Compliance the Easy Way - Zero-conf mTLS for Dev and Smooth Day-2 for Ops
Explore zero-conf mTLS implementation with Linkerd for secure, observable, and reliable application infrastructure in financial contexts, including insights on integration and long-term operations.
Build Trust with Your Users Workshop
Learn to define and monitor Service Level Objectives (SLOs) and Indicators (SLIs) for web applications, enhancing reliability, performance, and user trust through proactive monitoring and measurement techniques.
Application Security in an Agile SDLC
Explore integrating application security into Agile development, covering key concepts, tools, and real-world examples for creating secure software efficiently.
Securing Docker Instances
Learn essential techniques for securing Docker instances, including container spans, username spaces, and continuous controls, to enhance your containerization security practices.
Go for DevOps, Go for Microservices, and What Go Is
Explore Go's role in DevOps and microservices, its strengths and limitations, and the reasons behind its success in these domains.
Bringing AI to the Edge - On Premise Azure Cognitive Services - Open Source
Explore Azure Cognitive Services containers for on-premise AI, with demos of local Face and Text services. Learn to configure and implement edge AI solutions.
SSDT, Docker, and Azure DevOps - Cloud
Automate database deployments and testing using SSDT, Docker, and Azure DevOps. Learn to accelerate feature deployment, catch regression issues, and implement CI/CD practices for database development.
Modernizing SQL Server the Right Way
Learn essential tools and methodologies for seamless SQL Server upgrades, covering compatibility, assessment, migration, and post-migration processes to ensure successful modernization.

Getting Started with Observability Lab - Opentracing, Prometheus, and Jaeger
Hands-on lab exploring observability tools for cloud-native applications. Install and use Prometheus, Grafana, and Jaeger to monitor Kubernetes clusters and instrument microservices for improved troubleshooting and diagnostics.
Latency SLOs Done Right
Explore correct approaches to calculating latency SLOs using histograms and mathematically accurate quantiles, improving service level objectives for more effective monitoring and performance management.
A Practical Guide to Monitoring and Alerting with Time Series at Scale
Explore time series-based alerting methods and practical examples in Prometheus to reduce alert spam and improve production hygiene for more efficient monitoring at scale.
Burnout and Ops
Strategies for preventing and recovering from burnout in infrastructure engineering, with insights on setting boundaries, improving work conditions, and maintaining long-term career sustainability.
How to Copy Files
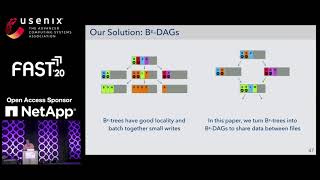
Explores efficient file cloning techniques in BetrFS, introducing "nimble clones" that optimize performance and space usage through copy-on-abundant-write policy and write-optimized key-value store.
Millions of Tiny Databases
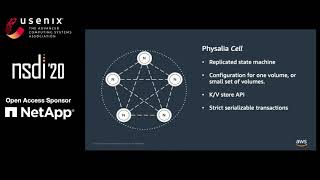
Innovative database system for cloud storage, optimizing availability and consistency through distributed architecture. Explores Physalia's design and applications in AWS, offering insights for distributed systems.
Kubernetes the Very Hard Way
Dive into complex runtime and networking challenges of large-scale Kubernetes clusters. Learn architectural improvements for scalability and performance, and explore ecosystem tools for enhanced cluster management.
A Post Incident Review Review
Explore ANZx's unique post-incident review process, focusing on safety science concepts and avoiding root cause analysis or action items tracking in a regulated industry environment.
Advanced Linux Kernel Networking Monitoring
Explore advanced Linux kernel networking monitoring for containers, focusing on troubleshooting techniques and a custom tool for identifying network issues in Kubernetes environments.
How We Drained Every Backbone Router Simultaneously
Exploring Meta's 2021 outage: causes, cascading effects, and lessons learned. Insights into network infrastructure, disaster recovery, and future improvements for preventing similar incidents.
Consul as a Monitoring Solution
Explore Consul's advanced monitoring capabilities, including intelligent health checks, automatic traffic routing, and problem-solving without human intervention for efficient cluster management.