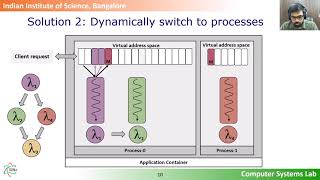
Faastlane - Accelerating Function-as-a-Service Workflows
Accelerating FaaS workflows by executing functions as threads, providing lightweight isolation, and dynamically identifying parallelism opportunities to enhance performance and reduce latency.
The Good, the Bad and the Ugly - The 3 Learnings of an SRE
Explore core SRE principles, focusing on incident management, monitoring, and proactive approaches. Gain insights from a young engineer's journey transitioning from academia to industry.
Command and KubeCTL - Real-World Kubernetes Security for Pentesters
Explore Kubernetes security challenges, attack techniques, and practical advice for pentesters and security practitioners in containerized environments.
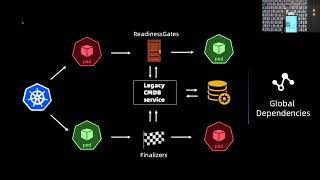
How to Not Destroy Your Production Kubernetes Clusters
Learn from real Kubernetes production incidents and best practices for maintaining high cluster availability, focusing on challenges with large-scale deployments and common operational pitfalls.
Tracing Bare Metal with OpenTelemetry
Explore how Equinix Metal implemented OpenTelemetry tracing for bare metal provisioning, improving debugging and reliability across their global infrastructure.
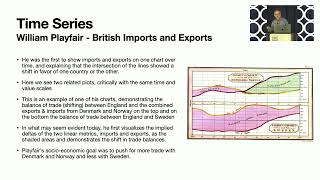
Improving How We Observe Our Observability Data - Techniques for SREs
Explore techniques to enhance observability data visualization for SREs, including multivariate relationships, small multiples, and sparklines, while avoiding common pitfalls in engineering presentations.
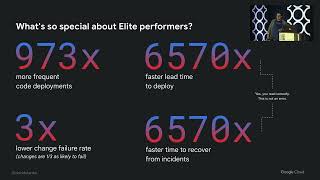
DO, RE, Me - Measuring the Effectiveness of Site Reliability Engineering
Explore the relationship between DevOps and SRE, their effectiveness, and how elite software delivery teams can benefit from modernizing technical operations.
EBPF - The Next Power Tool of SREs
Explore eBPF, a revolutionary Linux kernel technology for infrastructure observation and protection. Learn its capabilities, use cases, and implementation for enhanced system reliability and security.
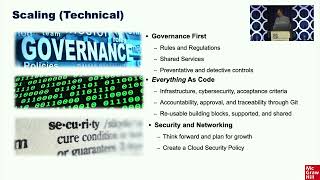
How We Survived - and Thrived - During The Pandemic and Helped Millions of Students Learn Remotely
Discover how McGraw Hill applied 'Upstream Thinking' to thrive during the pandemic, scaling services and implementing SRE principles to support millions of remote learners without compromising security or incurring high costs.
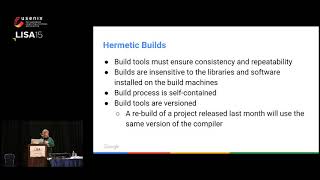
Release Engineering Best Practices at Google
Explore Google's release engineering practices, including bazel usage, branching strategies, and automated systems. Learn about disciplines, philosophies, and techniques for improving release processes.
Evolution of Observability Tools at Pinterest
Explore Pinterest's journey in scaling observability tools, from metrics to log search and distributed tracing, as the company grew from startup to web-scale platform.
Are We All on the Same Page? Let's Fix That
Explore Adaptive Paging, an innovative alert handler that uses tracing and heuristics to identify and notify the team closest to the problem, reducing alert fatigue in complex distributed systems.
Tracing Real-Time Distributed Systems
Exploring distributed tracing in real-time data streaming systems, focusing on challenges and solutions for trading platforms, including session tracking, data flow management, and storage optimization.
How to SRE When Everything's Already on Fire
Learn how Squarespace's team adopted SRE practices to transform their unreliable logging platform into a trusted system with 99.9% uptime, sharing valuable insights and strategies for improving service reliability.
How Stripe Invests in Technical Infrastructure
Explore Stripe's approach to prioritizing technical infrastructure investments, balancing firefighting and innovation, and enabling long-term success through strategic decision-making and resource allocation.
SLOs for Data-Intensive Services
Explore the journey of defining effective SLOs for data-intensive services, focusing on search engines. Learn about monitoring processes, consistency, and automated mitigation strategies for complex systems.
Control Theory for SRE
Learn to create a PID controller for autoscaling Kubernetes deployments, ensuring smooth scaling based on custom targets. Explore control theory principles and their application in SRE practices.
My Life as a Solo SRE
Transforming engineering culture: One SRE's journey from chaos to improved reliability, featuring practical tips on implementing SLIs, reducing incident response times, and fostering organizational change.
Principles of Chaos Engineering
Explore principles of Chaos Engineering to improve resilience in distributed systems. Learn techniques for surfacing inherent chaos and building confidence in system behavior at scale.
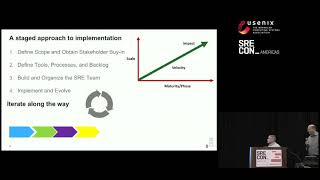
I'm an SRE Lead! Now What? How to Bootstrap and Organize Your SRE Team
Practical guide for new SRE leads on organizing teams, managing expectations, and implementing effective strategies. Covers phased approaches, lessons learned, and pitfalls to avoid in SRE journey.
DNSControl - A DSL for DNS as Code from StackOverflow.com
Explore DNSControl, a DNS DSL and compiler enabling DevOps practices for DNS management. Learn how StackOverflow.com automates complex configurations, simplifies updates, and enhances reliability.