Istio Service Mesh Security
Explora la seguridad en Istio Service Mesh con Diego Chavez. Aprende prácticas defensivas y ofensivas para aplicaciones en la nube, enfocadas en DevSecOps y microservicios.
Fileless Attack in Containers
Explore fileless attacks in containers, their detection using eBPF tools, and implications for cloud-native security. Learn about this growing threat and defense strategies from an expert developer.
Implementing SRE in a Regulated Environment
Insights on implementing Site Reliability Engineering practices in regulated environments, focusing on root cause analysis, chaos testing, and trend analysis while meeting regulatory expectations.
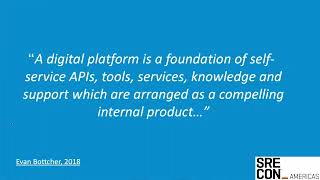
Lessons Learned from 7 Years of Running Developer Platforms
Insights on platform engineering best practices, including product management, developer retention, trust-building, and re-skilling ops staff, drawn from diverse organizations' experiences over the past decade.
Hell Is Other Platforms
Explore the pitfalls of blindly adopting others' platform strategies. Learn to retain agency, identify needs, and avoid common mistakes in platform engineering for your unique business context.
On the Wings of SREs - J.P. Morgan's Journey into the Cloud
Explore J.P. Morgan's transition to public cloud, focusing on SRE's role in overcoming regulatory, technical, and organizational challenges while ensuring stability and reliability.
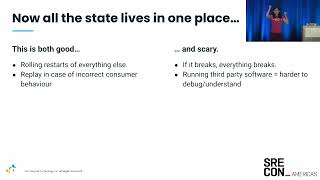
Scaling Telemetry Systems with Streaming
Explore the evolution of Honeycomb's Kafka cluster and telemetry systems, covering scaling strategies, infrastructure choices, and best practices for handling 10x data volume growth.
OpenTelemetry Metrics 101
Demystifying OpenTelemetry metrics: Learn about different metric instruments, their implementation, and how they can enhance your understanding of system performance and error rates.
How to Take Prometheus Planet Scale - Massively Large Scale Metrics Installations
Explore scaling Prometheus for massive metrics installations, covering field hint indices, query push down, GitOps deployment, and lessons learned from eBay's journey to planet-scale observability.
Building an APM with OpenTelemetry and OpenSource
Explore building an open-source APM using OpenTelemetry, Prometheus, and Jaeger. Learn implementation strategies, risks, and upcoming improvements in the OTel community for cost-effective application performance monitoring.
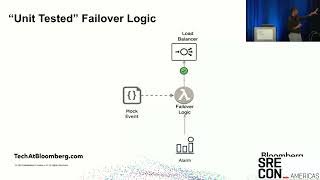
Chaos-Driven Development - TDD for Distributed Systems
Explore chaos experimentation as a test-driven development approach for distributed systems, enhancing reliability and validating changes throughout the software lifecycle.
The Revolution Will Not Be Terraformed - SRE and the Anarchist Style
Exploring SRE as a cultural force for change, examining its evolution and potential to drive reliability in organizations while drawing parallels to social movements and people-centric approaches.
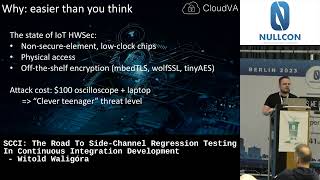
The Road to Side-Channel Regression Testing in CI Development
Explore integrating side-channel regression testing into CI development, with practical demonstrations and insights on implementing countermeasures for sample attacks.
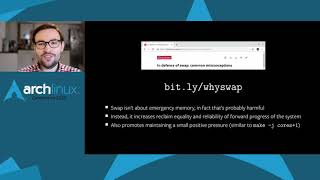
Linux Memory Management at Scale
Explore advanced Linux memory management techniques for reliable, efficient multi-container systems at scale. Learn key concepts, misconceptions, and cutting-edge technologies used in production environments.
Workadventure Selbst Betreiben - Ein Serviervorschlag
Learn to set up and operate your own WorkAdventure instance, a pixel-world platform. Discover the necessary steps, server requirements, and configuration process using Ansible and Docker on a Debian VM.
Workadventure Selbst Betreiben - Ein Serviervorschlag
Einstiegshilfe zum Aufsetzen und Betreiben einer WorkAdventure-Instanz. Minimaler Aufwand für eigene Pixel-Welt-Server mit Ansible, Docker und Debian. Ermöglicht Nutzung eigener oder öffentlicher Welt-Designs.
Hacking Containers and Kubernetes
Exploración de vulnerabilidades en contenedores y Kubernetes, detección de debilidades de seguridad mediante scripts simples y análisis de soluciones como Istio para mejorar la protección de clústeres.
Monitoring mit einer Kiste, aber mehreren Leuten
Effizientes Prometheus-Monitoring für private Server: Gemeinsame Infrastruktur nutzen, Kosten sparen und Ausfälle vermeiden. Praxisnahe Einführung mit Tipps zur Umsetzung.
CTF in a Box
Explore CIRCUS, a project addressing scalability issues in CTF platforms by allowing on-demand container spawning. Learn about challenges and solutions in this innovative approach.
Ansible All the Things
Grundlagen von Ansible: Vom ersten Host Inventory über Rollen und Playbooks bis zur Einrichtung von Raspberry Pi. Vorteile reproduzierbarer Infrastruktur und Tipps für distributionsübergreifende Playbooks.
Osmo-Config-Merge
Explore a tool for managing incremental changes to libosmocore/vty-style configuration files, including its functionality and a brief demonstration.