Orchestration Made Easy with Databricks Workflows
Discover Databricks Workflows: a managed orchestration service for streamlined data pipelines. Learn to create, run, and monitor reliable workflows, implement recovery actions, and explore new features for efficient data management.
Administrator Best Practices for Scaling and Securing Databricks Deployments
Optimize Databricks administration for enterprise-scale deployments. Learn best practices, new capabilities, and customer insights for efficient onboarding, security, and workspace management.
Securing Databricks on AWS Using PrivateLink - Deployment and Automation
Learn to secure Databricks on AWS using PrivateLink, covering architecture, setup, and automation. Gain insights on minimizing public internet data transfers for enhanced security and cost-efficiency.
Data Warehousing on the Lakehouse - Unifying Data, AI, and Analytics
Unify data, AI, and analytics with the lakehouse architecture. Learn success stories, use cases, and best practices for ingesting, storing, and governing data at scale for SQL and BI workloads using Databricks SQL.
User Defined Aggregation in Apache Spark - From Challenges to Improvements
Explore Apache Spark's User Defined Aggregate Functions (UDAFs), their evolution, and improvements in Spark 3.0. Learn to create custom aggregations, enhance performance, and contribute to the Spark community.
Cloud-Native Apache Spark Scheduling with YuniKorn on Kubernetes
Explore cloud-native Apache Spark scheduling on Kubernetes using YuniKorn. Learn about efficient resource management, quota handling, and auto-scaling for large-scale Spark jobs in cloud environments.
Building the Petcare Data Platform with Delta Lake and Spark ETL Pipeline
Explore Mars Petcare's data platform using Delta Lake and Spark ETL pipeline 'Kyte'. Learn about advantages over Azure Data Factory and leveraging Delta Lake for ETL configurations and data science.
Simplifying Testing of Spark Applications
Learn techniques to simplify testing Spark applications, covering Python UDFs, Pandas UDFs, and functional APIs. Explore practical scenarios and demos for efficient data processing and analysis.
Delta Lake - Diving into Data Lakes Without the Downsides
Explore Delta Lake's innovative approach to data management, offering enhanced reliability and performance for large-scale analytics without traditional data lake drawbacks.
Introducing Your Databricks Flight Assistant - Lakehouse AI Copilot
Explore Databricks' Lakehouse Assistant: Chat in English to generate SQL queries, scripts, and code explanations while navigating the Lakehouse with ease.
Generate Test Data Quick, Easy and in Large Volumes with the Databricks Labs Data Generator
Generate terabytes of proper test data quickly and easily using Databricks Labs Data Generator for dev environments across Azure, AWS, and GCP.
Databricks Photon and Spark SQL in Advanced Database Systems - Lecture 20
Explore Databricks Photon and Spark SQL's advanced features for efficient data processing and analysis in modern database systems.
Databricks Photon and Spark SQL in Advanced Database Systems - Lecture 18
Explore Databricks Photon and Spark SQL architectures, optimizations, and performance improvements in modern data processing systems.

Ensuring Data Quality in Databricks with Great Expectations
Integrate Great Expectations with Databricks to set, test, and enforce data pipeline expectations, ensuring accuracy and reliability in your data workflows.

Data Engineering: A Deep Dive into Databricks
Master Databricks for efficient data processing, focusing on Apache Spark transformations, ingestion methods, storage, orchestration, and best practices to optimize data engineering workflows.

Introduction to Azure Databricks
Explore Azure Databricks: Simplify big data analytics, streamline processing, and enhance data accessibility for informed decision-making.

Databricks for MLOps - Experiment Tracking, Model Packaging, and Deployment
Master MLflow in Databricks: Experiment tracking, model packaging, and deployment for efficient machine learning operations.

Data Engineering with Databricks - Leveraging the Lakehouse Platform for ETL Pipelines
Leverage Databricks Lakehouse Platform to build ETL pipelines, use Delta Live Tables, and orchestrate tasks with Workflows for efficient data processing.

Introduction to Databricks and Data Lakehouse Architecture
Explore Data Lakehouse, Databricks platform, Spark architecture, and SQL. Learn advantages and common use cases of Databricks for data processing.
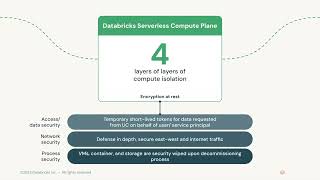
Databricks Serverless Security - Serverless Compute Isolation
Explore Databricks' serverless compute isolation techniques, including defense-in-depth strategies and multi-layered security measures to minimize risks in the intelligent data warehouse environment.
Version Control for Lakehouse Architecture - Essential Practices and Benefits
Discover how to implement data version control using lakeFS for improved data quality, reproducibility, and experimentation in Databricks data/ML pipelines, enhancing overall product value.