Code Like a Snake Charmer – Advanced Data Modeling in Python
Comprehensive Python data modeling tutorial covering extraction, cleaning, transformation, visualization, predictive modeling, validation, and deployment using popular libraries and Azure integration.
Power Query, M and Dataflow - The Lightsaber for the Data Jedi
Discover Power Query's transformation capabilities, M language benefits, and Dataflows' role in Power BI. Learn advanced features through demos to enhance your data preparation skills.
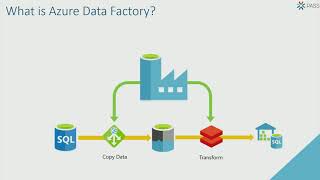
ETL in Azure Made Easy with Data Factory Mapping Data Flows
Explore Azure Data Factory's Mapping Data Flows for efficient, scalable ETL without coding. Learn to transform data using Databricks integration and graphical tools.
Data Munging to Wrangling - 7 Steps to Mastering Data Preparation for Data Science
Discover essential techniques for data preparation in AI/ML projects. Learn to source, clean, and transform data effectively, enhancing the quality and predictive power of machine learning models.
Power of Electric Snakes! PySpark for Big Data and Data Science
Learn to harness PySpark for big data analytics, covering RDDs, DataFrames, transformations, and machine learning. Gain practical skills for efficient data processing and analysis using Python and Spark.
Unlocking The Data Lake With Azure Synapse SQL Serverless
Explore and transform massive data in Azure data lakes using SQL Serverless for Synapse. Learn to leverage T-SQL for analytics, BI, and ML at petabyte scale.
ETLs with PowerBI and Introduction to Power Query
Aprende a realizar ETLs eficientes y domina Power Query en PowerBI para transformar y cargar datos de manera efectiva, mejorando tus habilidades de análisis y visualización.
Bridge to a New Universe - The End-to-End Azure Data Platform
Explore Microsoft's Azure Data Platform: Leverage SQL and Azure skills, new tools, and platforms to transform data into business insights and predictions in a comprehensive virtual environment.
Filters Beyond OrderBy and LimitTo
Explore advanced uses of AngularJS filters for data transformation, including custom filters and user-driven data manipulation, to enhance application flexibility and user experience.
Scaling Machine Learning Workflows to Big Data with Fugue
Learn to scale machine learning workflows from Pandas to distributed computing using Fugue, an open-source abstraction layer. Discover how to port Python code to Spark or Dask with minimal changes, enabling framework-agnostic and scale-agnostic data scie…
Streams, Effects and Beautiful Folds - A Winning Trilogy
Explore building a minimal streaming library using eff for async computations and origami for data extraction, learning to balance complexity and powerful abstractions in Scala.
Ducktape - Holding Scala's Productivity Together
Explore ducktape, a macro-based library for Scala 3 that streamlines JSON handling, reduces boilerplate, and enhances productivity in common development scenarios.
Gallia - Practical Data Transformation in Scala
Explore Gallia, a schema-aware Scala library for practical data transformation. Learn its benefits, usage, and comparison with alternatives like Pandas and Apache Spark through live coding demonstrations.
Building Billion Node Graphs for Machine Learning
Explore building billion-node graphs for machine learning, covering data ingestion, graph management, and algorithm execution at scale. Learn about challenges and solutions in handling massive datasets for GraphML research.
Processing Data at Scale with Rails
Strategies for handling large datasets using Rails, covering data ingestion, transformation, and storage with tools like ActiveRecord, Sidekiq, and Postgres.
Protecting Sensitive Data in Huge Datasets - Cloud Tools You Can Use
Explore tools and techniques for protecting sensitive data in large datasets, including PII detection, k-anonymity, and data transformation methods for responsible public data release.

Azure Data Factory: Cloud ETL Service for Data Integration and Transformation
Master Azure Data Factory for serverless data integration and transformation, with code-free UI and SSIS compatibility.
How to Create Pivot Tables from Multiple Excel Worksheets
Master the process of combining and analyzing data from multiple Excel sheets using Power Query and pivot tables to create powerful data summaries and insights.
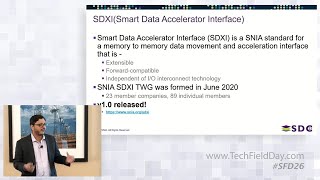
Revolutionizing Memory-to-Memory Data Movement with SNIA SDXI Standard
Discover how SNIA's SDXI standard transforms memory-to-memory data movement, offering enhanced efficiency, security, and direct accelerator access for improved system performance and data operations.
Enriching the Data vs Filtering in Apache Spark
Explore data enrichment vs filtering in Spark for improved performance and scalability in cloud-native applications, with practical examples and insights from Capital One's loyalty use case.
Building a Modern Enterprise Data Ecosystem on Cloud - Conf42 Cloud Native 2024
Explore modern enterprise data ecosystems on cloud platforms, covering storage, organization, consumption, pipelines, and machine learning. Learn key components and AWS challenges.