Gone Phishing: Lessons Learned Training a Phishing Email Classifier with Highly Imbalanced Biased Labels
Explore challenges and solutions in training a phishing email classifier with imbalanced, biased data. Learn practical strategies for evaluation and deployment in real-world scenarios.
Building a Minimal Data Science Platform
Develop a lean data science platform from scratch, scaling from individual to team projects while addressing key challenges and maximizing efficiency.
Retrieval, Search and Knowledge in the Age of LLMs and Vector Databases
Explore vector embeddings' impact on information compression, search, and knowledge retrieval. Learn how enterprises can leverage this technology to enhance customer understanding and interaction.
Applied Machine Learning in Blockchain-Based Technologies
Explore machine learning applications in cryptocurrency and NFTs, analyzing blockchain technology through deep learning models and discussing ML solutions for enhanced blockchain security.
Using Data Science to Support Mental Health
Explore how data science analyzes mental health platform usage to understand UK mental health trends and connect people with local services.
Reducing Complexity and Increasing Performance with Trino
Explore Trino's capabilities for efficient data querying across diverse sources, optimizing pipelines, and enhancing analytics performance in complex data environments.
Data Governance - A Data Scientist's Best Friend
Explore key aspects of data governance empowering data scientists to make informed decisions and extract value from datasets. Learn approaches fostering data trust and safeguarding against biases.
Using Kafka at Scale - A Case Study of Microservices Data Pipelines at Evernorth Health Services
Explore a case study on implementing Kafka-based microservices data pipelines at scale in Evernorth Health Services, showcasing real-world applications and challenges.
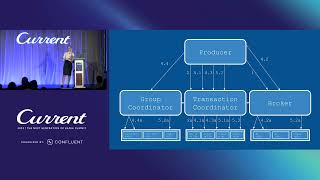
Transactions in Action: The Story of Exactly Once in Apache Kafka
Explore Apache Kafka's transaction evolution, from KIP-98 to KIP-890, covering idempotency, protocol improvements, and solutions for hanging transactions.
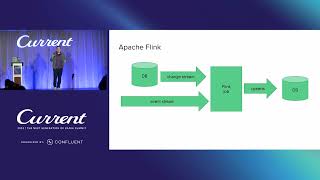
Deeply Declarative Data Pipelines with Flink and Kubernetes
Explore declarative streaming data pipelines on Kubernetes using Flink and SQL. Learn to simplify development, integrate systems, and optimize configurations for efficient stream processing.
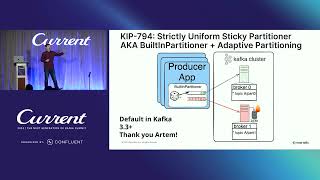
Mitigating Kafka Broker 'Gray' Failures for Key-Based Partitioners with Partition Multihoming
Explore partition multihoming (PMH) to mitigate Kafka broker gray failures, enhancing reliability for key-based partitioning. Learn implementation details, workflow, and future roadmap for virtual partitioning in Apache Kafka.
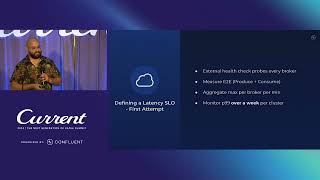
Our Multi-Year Journey to a 10x Faster Confluent Cloud
Explore the multi-year journey to enhance Confluent Cloud's performance, learning about workload design, cloud-native complexities, challenges faced, and key principles for improving data streaming systems.
Build Real-time Machine Learning Apps on Generative AI with Kafka Streams
Develop real-time ML applications using Generative AI and Kafka Streams, leveraging data in motion for intelligent, streaming-based solutions.
Working with Data Using Azure Functions
Explore Azure Functions for data interactions with Azure SQL, Cosmos DB, and Event Hubs. Learn to build lightweight, code-first APIs, integrations, ETL, and maintenance routines.
Power BI and Azure Synapse Analytics: Beginning Your Journey
Explore Power BI and Azure Synapse Analytics integration, learning effective data leveraging techniques to maximize insights and optimize your data strategy.

Agentic Architecture to Reduce Decision Paralysis in Data Science
Explore agentic architecture's role in empowering data teams, optimizing user experiences, and driving business growth through proactive decision-making in data science.

The Future Roadmap for the Composable Data Stack
Explore advancements in data processing with Wes McKinney. Learn about Parquet, Arrow, and interface libraries like Ibis and tidyverse. Gain insights into current project states and future innovations.

Streaming CDC Data from PostgreSQL to Snowflake - Challenges and Solutions
Uncover streaming ETL secrets: Postgres to Snowflake data ingestion, change data capture, dynamic tables, and Snowpipe streaming. Learn solutions for lower latency, cost savings, and enhanced scalability.

Forecasting Development Timelines - Bringing Accuracy and Predictability to Software Projects
Optimize product roadmap management using historical data for precise delivery forecasts. Explore Cardagraph's innovative technique to enhance project planning and fulfill commitments confidently.

Move Fast and Don't Break Things - How to Build a Scalable Data Platform
Explore ML Operations at scale, focusing on Hamilton for efficient model deployment. Learn practical solutions and industry comparisons for data scientists and MLEs.

Building a Flexible Data Platform for LLM Training Data
Explore LLM training data platforms: architecture, ingestion, preprocessing, and scaling challenges. Learn from Cohere's experience in managing petabyte-scale datasets for high-quality model training.