Thermodynamics of Non-Additive Systems: The Example of the Thirring Model
Explore thermodynamics of non-additive systems through the Thirring model, examining ensemble inequivalence and equilibrium states in long-range interacting systems.
Standardising and Opening Up Beneficial Ownership Data
Explore standardization and transparency in beneficial ownership data, focusing on key concepts, challenges, and best practices for open data initiatives.
Bringing Light to Risks Lurking in the Black Boxes of AI Models
Explore hidden risks in AI models and learn strategies to illuminate potential dangers lurking within these complex systems.
Apache Spark Processing with AWS EMR - Data Engineering Project
Master AWS EMR for data processing: set up, submit Spark jobs, visualize on Hadoop UI, and leverage cloud computing for efficient big data handling.

End-to-End Modern Data Engineering with DBT and BigQuery
Master modern data engineering with DBT and BigQuery. Set up, link, transform data, convert tables to views, seed data, write tests, and generate documentation in this comprehensive tutorial.
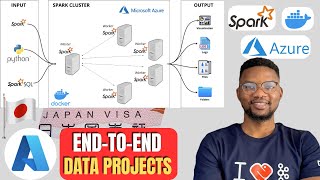
End-to-End Data Engineering on Azure Spark Cluster: Japan Visa Analysis
Set up Spark master-worker architecture in Docker on Azure, process and visualize Japan visa data using PySpark and Plotly. Clean, transform, and gain insights into visa trends through interactive data analysis.
Python Web Scraping for Beginners - Extracting Data from News Websites
Learn to extract valuable data from news websites using Python and BeautifulSoup. Master HTML parsing, efficient script writing, and data cleaning techniques for effective web scraping.
One Dataset and Three Use Cases with Microsoft Fabric
Leverage World Bank Open Data with Microsoft Fabric using various methods, model data, and create stunning reports in this demo-filled session on end-to-end solutions.
The Fundamentals of DAX Contexts
Embark on an African Safari-themed adventure to master DAX contexts, exploring row and filter contexts through captivating wildlife visuals. Gain essential skills for data analysis and business intelligence.
Build AI Quickly, Collaboratively, and Confidently with Colab Using Vertex AI
Accelerate AI development using Vertex AI on Colab: enhance productivity, collaboration, and operate confidently at scale with robust security and compliance.
Petabyte-Scale Data Migrations to Google Cloud - Best Practices and Case Study
Migrate petabyte-scale data pipelines to Google Cloud, optimizing performance and reducing costs. Learn from Globo's experience in handling massive concurrent users for major events.

Introduction to Duet AI in Google Cloud - Boosting Productivity and Expertise
Explore Duet AI's features for boosting cloud productivity, including code assistance, AI-backed operations, data exploration, and no-code app building.
Next-Gen Data Modeling, Integrity, and Governance with YODA - Insights from Yotpo and ZipRecruiter
Explore next-gen data modeling strategies for large-scale systems. Learn about YODA, an internal tool combining developer experience, DBT, Databricks, and more, to address data standardization and governance challenges.
Real-Time Data Transformation and Analytics with dbt Labs
Explore real-time data transformation and analytics with dbt Labs. Learn about Modern Data Stack, streaming analytics, and best practices for building efficient data pipelines and democratizing data access.
The Future of Streaming Data - Challenges and Opportunities
Explore the future of streaming data, focusing on managing complex data connections, adopting Kafka internally, and addressing challenges in data governance, security, and movement across organizations.
What Apache Kafka Developers Can Learn from Online Gaming
Explore how online gaming concepts enhance large-scale event management in Apache Kafka, including latency masking, conflict resolution, and seamless collaboration techniques for improved real-time data processing.

Git for Data: Managing Data like Code with lakeFS
Explore lakeFS, an open-source tool transforming object storage into Git-like repositories for data version control. Learn its benefits for data management, reproducibility, and reprocessing in various industries.
Improving Scalability and Performance with Kafka Leader Election
Explore Kafka leader election's role in improving scalability and performance. Learn about failover processes, preferred leaders, and optimizations for efficient data replication and consistency in distributed systems.
Real-Time Machine Learning and Smarter AI with Data Streaming
Explore real-time machine learning and AI with data streaming. Learn how Airy's open-source platform uses Apache Kafka to improve customer experiences through integrated, accessible data and conversational AI.
The Present and Future of Stream Processing - Trends and Innovations
Explore trends in data streaming, Apache Kafka adoption, and the future of stream processing with industry experts. Gain insights on best practices, emerging use cases, and technological advancements.

Building and Designing Events and Event Streams with Apache Kafka
Learn to design effective event-driven architectures using Apache Kafka. Explore key concepts like internal vs. external events, fact vs. delta, and normalization strategies to build scalable, responsive systems.