
Large Scale Graph Analysis Using Scala and Akka
Explore large-scale graph analysis using Scala and Akka. Learn architecture, implementation, and optimization techniques for processing big data with graph structures and stream outputs.
Connecting Reactive Applications with Fast Data Using Reactive Streams
Explore integrating Spark Streaming with reactive applications using Reactive Streams, focusing on back pressure support and creating a fully reactive system for efficient data processing.
Spark 2.0
Explore Apache Spark 2.0's evolution, new APIs, and optimizations for big data processing. Learn about DataFrames, Datasets, and Structured Streaming for efficient distributed programming.
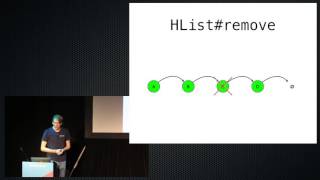
Roll Your Own Shapeless
Explore advanced Scala type system techniques to recreate Shapeless framework elements, focusing on HList operations, type-level functions, and Peano arithmetic without macros.
Discovering the Untold User Stories of Kubernetes With Applied Anthropology
Explore Kubernetes user stories through applied anthropology, integrating cultural concepts to gain insights into community interactions and refine Certified Kubernetes service definitions.
Teaching Ruby to Count
Explore advanced Ruby techniques for iteration, data series, and custom object generation. Learn to leverage Enumerable, Enumerators, and Ranges to create joyful interfaces for your teammates.
Fluent Bit - Swiss Army Tool of Observability Data Ingestion
Discover how Fluent Bit revolutionizes observability data ingestion, offering scalability, performance, and cost-efficiency. Learn about custom plugins, dynamic log metrics extraction, and overcoming data schema challenges.
Customized Cloud Native Logging - Fluent Bit in Open Service Mesh
Explore Fluent Bit integration in Open Service Mesh for customized cloud-native logging. Learn practical examples of filtering, annotating, and routing logs in containerized environments.
Scaling ML Pipelines with KALE - The Kubeflow Automated Pipeline Engine
Discover KALE, the Kubeflow Automated Pipeline Engine, for scaling ML pipelines. Learn how to transform Jupyter Notebook experiments into production-grade pipelines for efficient model training and real-time serving.
Exporting Your Trace Telemetry with OpenTelemetry and Fluent Bit
Learn to collect and export trace telemetry using OpenTelemetry and Fluent Bit for efficient cloud-native application monitoring and observability.
Scaling Log Collection with Fluent Bit
Explore efficient log collection scaling using Fluent Bit, featuring migration insights, benchmarks, and optimization strategies for various use cases.
ML Ops Design Patterns with Kubeflow Pipelines
Explore ML Ops design patterns using Kubeflow Pipelines to transition from notebook exploration to production, addressing challenges and implementing effective solutions.
Kubernetes Running Manufacturing Systems - A Perfect Match
Explore Kubernetes-based control systems for laser manufacturing, addressing data challenges and enabling dynamic edge analytics in distributed environments.
Observability with Consul Connect
Explore setting up and observing a service mesh platform using Consul Connect, focusing on effective monitoring through metrics, logs, and traces with Prometheus, Loki, Tempo, and Grafana.
Streaming Analytics on Edge with Kuiper and KubeEdge
Explore edge IoT data analytics using Kuiper and KubeEdge. Learn about cloud-edge collaboration, SQL analytics, and AI integration for efficient IoT data processing and management in resource-constrained environments.
Building and Managing a Centralized ML Platform with Kubeflow at CERN
Explore CERN's centralized ML platform using Kubeflow, covering data preparation, model training, and serving. Learn about resource optimization, integration challenges, and cloud expansion possibilities.
Scaling Apache Spark on Kube to Apple Scale
Explore scaling Apache Spark on Kubernetes at Apple's scale. Learn about workload portability, best practices, migration tips, and new enhancements for effective deployment in large-scale environments.
Fluency - How Big Data is Changing Incident Response
Explore how big data transforms incident response, comparing traditional methods with modern data analysis techniques for enhanced cybersecurity and threat detection.
Honeypots for Active Defense
Explore active defense strategies using honeypots. Learn about various honeypot types, implementation techniques, and tools for enhancing network security and threat intelligence.
Teach Me11 Developers Care and Feeding
Explore effective strategies for nurturing and supporting developers, enhancing productivity and job satisfaction in software development teams.
Open Secrets of the Defense Industry - Building Your Own Intelligence Program From the Ground
Learn to build an intelligence program from scratch, exploring open-source methods, data collection, and best practices for defending against cyber threats in the defense industry.