Introducing MLflow for End-to-End Machine Learning on Databricks
Explore end-to-end machine learning with MLflow on Databricks: from data engineering to model deployment, using health data to predict life expectancy through Spark, hyperopt, and interactive dashboards.
Scalable AutoML for Time Series Forecasting Using Ray
Explore scalable AutoML for time series forecasting using Ray, covering feature generation, model selection, and hyper-parameter tuning. Learn from real-world applications and experiences in various industries.
Accelerating the ML Lifecycle with Enterprise-Grade Feature Stores
Explore enterprise-grade feature store for ML lifecycle acceleration, addressing data engineering challenges, and empowering data scientists to streamline ML application delivery with centralized data management and instant feature serving.
Productionizing Machine Learning Pipelines with Databricks and Azure ML
Jumpstart ML projects with Databricks and Azure ML. Learn to build, track, and deploy production-ready pipelines using tools like MLflow, TensorFlow, and PyTorch for efficient, reproducible data science workflows.
Azure and Databricks Enabling Personalized Customer Experience at CVS Health
Explore how CVS Health leveraged Azure and Databricks to personalize customer experiences, implement machine learning models, and drive business value through data-driven decision-making and experimentation.
Deep Learning for Price Action Prediction Using Databricks and AWS
Explore deep learning techniques to enhance price action prediction using Databricks and AWS. Learn to optimize technical indicators and train models with Amazon SageMaker for improved financial forecasting.
The Killer Feature Store - Orchestrating Spark ML Pipelines and MLflow for Production
Explore feature store implementation as an orchestration engine for ML pipeline stages using Spark and MLflow, focusing on deployment management, A/B testing, discovery, and governance.
Benchmarks and How-Tos for Convolutional Neural Networks on HorovodRunner-Enabled Apache Spark Clusters
Explore benchmarks and implementation techniques for distributed deep learning using HorovodRunner on Apache Spark clusters, focusing on CNN tasks and scaling efficiency for both GPU and CPU clusters.
Tuning Machine Learning Models - Scaling, Workflows, and Architecture
Automating and scaling ML model tuning using Hyperopt and Apache Spark. Best practices for workflows, architecture, and optimization in hyperparameter tuning for improved performance and accuracy.
Productionalizing Models through CI/CD Design with MLflow
Explore MLflow integration with CI/CD for streamlined model deployment. Learn to design and implement automated pipelines using the model registry, enhancing efficiency in machine learning workflows.
Apache Spark NLP for Healthcare - Building Real-World AI Systems
Explore real-world healthcare AI systems using NLP, covering patient risk prediction, diagnosis automation, and revenue optimization. Learn key considerations for building domain-specific models and scalable ML pipelines.
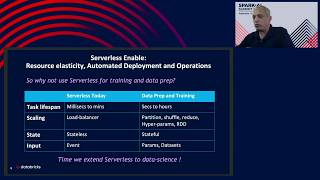
Productionizing Machine Learning with Microservices Architecture
Learn to deploy ML models as microservices using Spark, enabling auto-scaling, versioning, and security. Discover how to aggregate real-time and historical data for inferencing and create actionable insights.
Apache Pulsar - Next Generation Messaging and Queuing System
Overview of Apache Pulsar's architecture, features, and benefits as a scalable messaging system with unified storage, processing, and serverless capabilities for building end-to-end streaming applications.
Model Explanation and Prediction Exploration Using Spark ML
Explore techniques for explaining non-linear models, showing feature contributions, and performing what-if analysis using Spark ML. Implement these methods to enhance model interpretability and enable interactive prediction exploration.
Improving Broadcast Joins in Apache Spark SQL
Discover techniques to enhance broadcast joins in Apache Spark SQL, including executor-side broadcasting and memory optimization, for improved performance in large-scale ETL pipelines and complex data processing tasks.
Zeus - Uber's Highly Scalable Distributed Shuffle as a Service
Explore Uber's Zeus: a highly scalable, distributed shuffle service powering data processing. Learn its architecture, integration with Spark, and performance advantages over traditional external shuffle methods.
The Shift to Data Mesh: Fundamentals and Implementation Strategies
Explore Data Mesh fundamentals and how Avanade helps clients adopt a distributed, domain-led approach to improve data modeling, governance, and incremental transformation for faster performance.
Efficient Distributed Hyperparameter Tuning with Apache Spark
Learn to efficiently distribute hyperparameter tuning workloads using Apache Spark, avoiding common pitfalls and optimizing performance. Explore best practices with Hyperopt and joblib-spark for scaling ML model training.
Architect's Open-Source Guide for Data Mesh Architecture
Explore Data Mesh architecture, its principles, benefits, and implementation challenges. Learn about open-source tools like Apache Spark for building effective Data Mesh systems in real-world scenarios.
Using Docker Images in Production - Databricks Case Study
Learn how Condé Nast evolved Spire, their user segmentation service, from notebooks to Docker images on Databricks clusters. Explore the streamlined deployment workflow, challenges faced, and solutions implemented.
Advanced Natural Language Processing with Apache Spark NLP
Explore advanced NLP tasks using Apache Spark NLP, covering classification, named entity recognition, sentiment analysis, and more through hands-on Python notebooks and deep learning techniques.