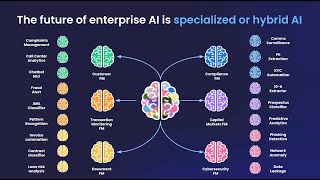
Leveraging Data to Unlock AI's True Potential in Enterprise Projects
Unlock AI's potential through data development. Learn to fine-tune LLMs for domain-specific tasks, leverage expert knowledge, and accelerate high-quality dataset creation using Snorkel Flow.
How Georgetown Helps Data Scientists and SMEs Collaborate on Machine Learning
Explore Georgetown's approach to enhancing ML project workflows and fostering collaboration between data scientists and subject matter experts using Snorkel.
How Data Transforms As It Moves Through An Enterprise
Explore data's journey across enterprises, unraveling its transformations and impact on decision-making, efficiency, and AI innovation through data-centric workflows.
How Caterpillar Links Data and Expertise to Predict Repairs
Discover how Caterpillar combines domain knowledge and data to predict heavy equipment repairs, enhancing value for the company, dealers, and customers through modern analytics.
How Data Can Close the Foundation Model Performance Gap
Explore data-centric development's role in bridging the gap between AI's power and its practical value for companies, focusing on Foundation Models.
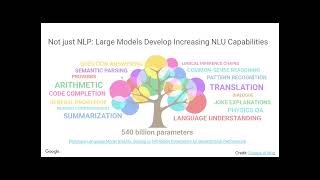
Google's Cloud Partner Engineer Chief on AI Ethics - Challenges and Benefits of Foundation Models for Enterprises
Explore challenges and benefits of Foundation Models for enterprises, focusing on inadequacies in current ML pipelines for FM development workflows.
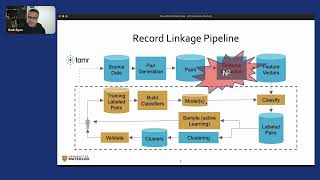
How ML-Powered Data Cleaning Streamlines the AI Pipeline
Explore ML-powered data cleaning techniques to streamline AI pipelines, automate labor-intensive tasks, and overcome impediments in data preparation for efficient data science workflows.
How to Create Data-Cleaning Auto-Pipelines With Python
Develop automated data cleaning pipelines using Scikit-Learn to streamline data processing, reduce time spent on preprocessing, and enhance reproducibility in your data science projects.
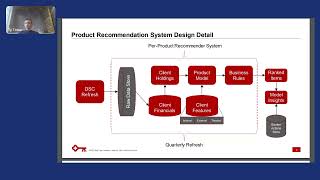
KeyBank's Innovative Approach to Recommender Systems in Financial Services
Explore KeyBank's innovative recommender systems for enhancing banker productivity. Learn about challenges, opportunities, and data-centric approaches in financial sector implementation.
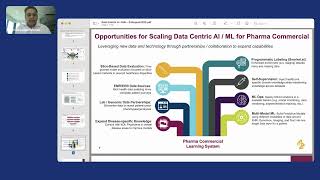
Data-Centric AI Approach in Pharmaceutical Industry - AstraZeneca Case Study
Explore data-centric AI in pharma: personalized doctor education, patient treatment optimization, and real-world data utilization for predictive modeling at AstraZeneca.
Transforming Call Center Operations with AI - A Financial Institution Case Study
Explore how a major financial firm enhanced customer service using Snorkel Flow's AI solution. Learn about implementation challenges, impacts, and future plans for integrating all customer touchpoints.
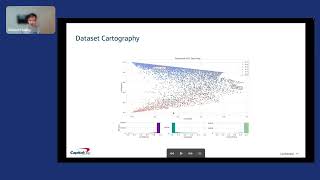
Dataset Cartography: What Capital One Monitors to Better Manage AI Training Data
Explore dataset cartography techniques used by Capital One to enhance AI training data management and improve model performance.
Towards Digital Twins for Precision Medicine
Explore digital twins in precision medicine, covering virtual trials, theranostics, AI, data management, and future prospects in personalized healthcare.
Recommender Systems: Metrics, Trends, and Challenges
Explore recommender systems' impact on digital strategies, from basic models to advanced approaches. Learn implementation strategies and address deployment challenges.
Don't Fix Bad Data, Do This Instead - Pragmatic Strategies for Data Quality
Explore pragmatic strategies for bridging the gap between data expectations and reality. Learn about integration tests, prioritization, and balancing technical and cultural measures in data quality management.
Caching for Jupyter Notebooks
Aprenda técnicas de caching para acelerar o desenvolvimento em Jupyter Notebooks, melhorando o fluxo de trabalho e reduzindo o tempo de espera em células dispendiosas.
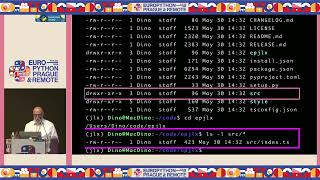
Creating Your Own Extensions for JupyterLab
Learn to create custom JupyterLab extensions, enhancing functionality and integrating complex tasks. Explore the extension infrastructure and build a step-by-step app with styling and parameter options.
DBT and Python - How to Write Reusable and Testable Pipelines
Develop reusable and testable data pipelines using DBT and Python. Learn best practices for version control, DAGs, and unit testing in SQL and Python-based models.

chDB - The Blazing Fast SQL Engine for Data Science
Explore chDB, a high-performance SQL engine for Python data ecosystem. Leverage its extensive data source support, ANSI SQL compliance, and seamless integration with popular libraries for efficient data analysis.
One Analysis a Day Keeps Anomalies Away - Detecting and Analyzing Data Anomalies
Explore Python techniques for data observability, anomaly detection, and root cause analysis in multivariate time series. Learn to distinguish anomalies from data drift and turn insights into opportunities.
Verifiable Data Science via Interactive Proofs
Explore interactive proofs for verifiable data science, enhancing trust and reliability in scientific computations and analyses.