Literate Statistical Programming for Reproducible Data Science
Learn a reproducible, auditable workflow for data science projects using Literate Statistical Programming principles, tools, and techniques for improved experimentation and iteration.
TMLS 2019
Explore machine learning insights with industry experts Amit Jain and Ronaldo Felipe at TMLS 2019, gaining valuable knowledge and perspectives on cutting-edge ML developments.
Building an Open Data Lakehouse Using Apache Spark, Apache Iceberg and Dremio
Explore the evolution of big data to data lakehouses, focusing on open architecture development, security, governance, and augmentation using Dremio, Apache Spark, and Apache Iceberg.
My Story as a Data Visualization Freelancer - Ups, Downs, and Lessons Learned
Discover the journey of a data visualization freelancer, exploring challenges, motivations, and valuable insights for success in the field.
Introducing Your Databricks Flight Assistant - Lakehouse AI Copilot
Explore Databricks' Lakehouse Assistant: Chat in English to generate SQL queries, scripts, and code explanations while navigating the Lakehouse with ease.
Power Query in 20 Minutes - How it Works
Explore Power Query's internals and gain a deeper understanding of this increasingly prevalent tool in Power BI and Fabric technologies.
Take a Self-Taught Journey into the World of Data
Discover how to transition from teaching to data analytics through self-learning, leveraging community support in the tech industry.
How to Get Noticed for a Power BI Job Interview
Stand out in Power BI job interviews with a simple yet effective trick to showcase your report creation skills, even without extensive experience.
Report Design and Psychology - Quick Tips
Learn intuitive report design techniques based on how the brain processes information, enhancing data visualization and communication effectiveness.
Generate Test Data Quick, Easy and in Large Volumes with the Databricks Labs Data Generator
Generate terabytes of proper test data quickly and easily using Databricks Labs Data Generator for dev environments across Azure, AWS, and GCP.
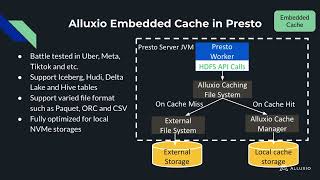
Caching Framework for Exabyte-Scale Data Lakes
Optimize exabyte-scale data lakes with open-source caching framework. Improve performance, reduce costs, and tackle challenges in complex data environments using Hadoop, Parquet, Hudi, and Alluxio.
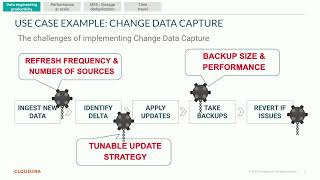
Four Technical Value Drivers of a Data Lakehouse with Iceberg
Explore four key technical value drivers of data lakehouses and how Apache Iceberg enhances these capabilities for data practitioners across various roles.
New Features of Apache NiFi - Tips and Techniques
Explore Apache NiFi's latest features, processors, and best practices. Build efficient data flows using cutting-edge techniques, with tips and guides for optimal implementation.
Utilizing Real-Time Transit Data for Travel Optimization
Optimize travel using real-time transit data from NYC's MTA. Learn to process and analyze public data feeds with Apache tools for efficient route planning and decision-making.
Inference at Scale with Apache Beam
Learn to deploy and scale machine learning models efficiently using Apache Beam for distributed inference on CPUs and GPUs, with practical insights on parallelizing workloads.
The Free Lunch is Over: Dealing with Unstructured Data in the Era of LLMs
Explore unstructured data processing using ML, LLMs, and Apache tools. Learn to handle audio, images, and text with vector embeddings for natural language analysis in data engineering pipelines.
Through the Looking Glass: Key Architectural Choices in Flink and Kafka Streams
Explore architectural differences between Apache Flink and Kafka Streams, gaining insights into stream processing fundamentals and design choices for improved system performance.
Declarative Reasoning with Timelines: The Next Step in Event Processing
Explore declarative reasoning with timelines for advanced event processing. Learn stream-native query abstractions and simplified time-based reasoning techniques for modern data processing challenges.
Batch and Stream Analysis with TypeScript Using Apache Beam
Explore batch and stream analysis using Beam's Typescript SDK. Learn API choices, usability, and functionality through demos. Discover how to leverage Typescript for efficient data processing workflows.
Apache Arrow and Go: A Match Made in Data
Explore Apache Arrow's Go implementation, covering Arrow and Parquet libraries, Flight server/client, C Data API integration, and performance optimization techniques.
Solr Eclipse - Zomato's Journey to 64 Million Search Queries a Day
Explore Zomato's journey scaling Apache Solr to handle 64 million daily searches across 100 million restaurant items in 13 languages, powering their homepage and overcoming technical challenges.