Delta Lake Roadmap 2021 H2 - Features Overview and Community Feedback
Overview of Delta Lake's 2021 roadmap, highlighting new features, integrations, and community-driven developments for enhanced data management and analytics capabilities.
Multi-Table Transactions with LakeFS and Delta Lake - Tech Talk
Explore multi-table transactions using LakeFS and Delta Lake for collaborative data lake management, enabling CI/CD deployment and simplified multi-table pipelines in cloud storage systems.
Hot Technologies in Data Analytics - What You Need to Learn
Discover essential emerging technologies in Data Analytics and learn how to evaluate them for your career advancement.
Databricks Fast Lanes - Better Performance and Lower Costs
Optimize SQL Endpoints with Databricks Fast Lanes for improved performance and cost-efficiency in analytics and data warehouse workloads.
Master Databricks and Apache Spark - SparkR Usage - Lesson 35
Explore SparkR for integrating R with Databricks and Apache Spark, covering architecture, APIs, libraries, and practical examples of data manipulation and analysis.
Master Databricks and Apache Spark - Introduction
Learn the fundamentals of Databricks and Apache Spark, exploring scale-up vs. scale-out concepts and laying the groundwork for mastering these powerful data processing tools.
Master Databricks and Apache Spark Step by Step - PySpark Using RDDs
Explore PySpark and RDDs in Databricks: Learn about lazy evaluation, transformations, and actions while analyzing data using Resilient Distributed Datasets.
Using SQL Window Functions in Databricks and Apache Spark - Lesson 16
Learn to leverage Spark SQL window functions for advanced data engineering on Databricks, including cumulative totals, ranking, and aggregations alongside detail rows, enhancing your data manipulation capabilities.
Using SQL Views in Databricks and Apache Spark - Lesson 12
Learn to create and utilize SQL views in Databricks for efficient data analysis and pipeline reuse. Explore common table expressions, aggregations, and case statements for advanced querying techniques.

Understanding Spark SQL - Lesson 6
Explore Spark SQL's powerful features for data engineering, including query optimizations and support for Python, R, and Scala, enhancing parallel processing performance.
Using the Data Science Process - Lesson 5
Explore the data science process from project inception to completion, covering key steps for successful implementation in Databricks and Apache Spark projects.
Create a Spark Cluster - Master Databricks and Apache Spark Step by Step - Lesson 4
Learn to create and use Apache Spark clusters, understand their differences from Databricks, and explore data querying with Zeppelin notebooks in this step-by-step guide.
Databricks Workspace Tour and Notebook Demo - Lesson 3
Comprehensive tour of Databricks Workspace, demonstrating tools and features with focus on the proprietary notebook IDE. Provides foundation for advanced Databricks and Apache Spark usage.
Create a Databricks Workspace - Lesson 2
Learn to create a Databricks workspace in Azure, understanding its components, pricing, and setup process. Gain practical skills for setting up your cloud-based data analytics environment.
Hitting and Resolving Azure Resource Limits
Learn to manage Azure resource limits, prevent deployment failures, and ensure smooth enterprise operations by understanding quota limits and how to increase them.
Fit and Predict With Logistic Regression for Bird Bath Observations in Australia
Learn to model bird bath observations in Australia using tidymodels, combining model specifications with feature engineering recipes for effective fitting and prediction.
Use Tidymodels Workflowsets to Predict Human-Computer Interactions from Star Trek
Explore machine learning with tidymodels workflowsets to predict speaker type in Star Trek interactions, featuring data preprocessing, model evaluation, and result analysis.

Predict Housing Prices in Austin TX with Tidymodels and XGBoost
Explore feature engineering for boosted tree models using Austin housing data. Learn to incorporate text information as indicator variables and tune models for accurate price predictions.
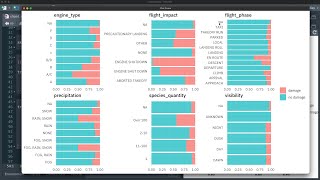
Class Imbalance and Classification Metrics With Aircraft Wildlife Strikes
Explore how handling class imbalance affects classification metrics using aircraft wildlife strike data, with focus on sensitivity and specificity in predictive modeling.
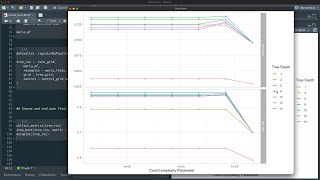
Partial Dependence Plots for Mario Kart World Records
Explore decision tree modeling and partial dependence profiles for Mario Kart world records using tidymodels and DALEX, with a focus on predicting shortcut usage.
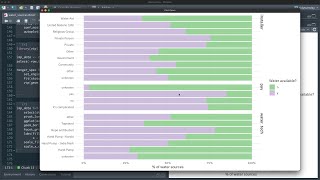
Predict Water Availability in Sierra Leone With Random Forests
Explore random forest modeling with tidymodels to analyze water sources in Sierra Leone, covering data preparation, model building, and evaluation techniques.