Rep-RAID: An Integrated Approach to Optimizing Data Replication and Garbage Collection in RAID-Enabled SSDs
Explore an innovative approach to optimizing data replication and garbage collection in RAID-enabled SSDs, improving I/O performance and reducing tail latency for enhanced data reliability.
How to Build a Planet-Scale Data Replication System - Google Cloud Infrastructure
Explore Google Cloud's planet-scale data replication infrastructure, challenges, and approaches for ensuring global data distribution, durability, and availability.
Spanner - Google's Distributed Database
Explore Google's Spanner: a planet-scale distributed database with innovative features like lock-free strong reads and globally consistent snapshots, enabled by GPS and atomic clocks.
How to Take Prometheus Planet Scale - Massively Large Scale Metrics Installations
Explore scaling Prometheus for massive metrics installations, covering field hint indices, query push down, GitOps deployment, and lessons learned from eBay's journey to planet-scale observability.
Snowcannon - Synchronous Data Replication in FDB
Explore Snowcannon, a synchronous data replication system for FoundationDB, enhancing disaster recovery with zero data loss and improved maintenance capabilities.
HiveMind - Distributed File Storage Using JavaScript Botnets
Explore distributed file storage using JavaScript botnets, covering WebSockets, encryption, and data prioritization. Learn about browser compatibility and potential challenges in this innovative approach.
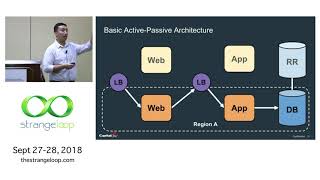
Architecting for Active-Active Resiliency in the Cloud
Explore multi-regional active-active resiliency in cloud architecture, covering data replication, availability calculations, and design patterns for maximizing service uptime and minimizing failures.
Apache Kafka Event Streaming Platform for .NET Developers
Explore Apache Kafka's event streaming platform for .NET developers, covering architecture, pub/sub messaging, and real-time stream processing applications at scale.

Systems That Run Forever - Self-Heal and Scale
Explore architectural principles for building scalable, fault-tolerant systems using isolated parallel components, error detection, and live code upgrades, with insights from Erlang's design.
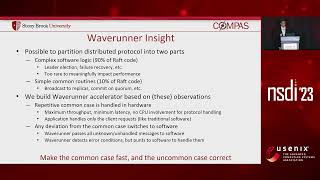
Waverunner - An Elegant Approach to Hardware Acceleration of State Machine Replication
Elegant hardware acceleration for state machine replication using FPGA-based SmartNICs. Achieves high performance in common scenarios while maintaining software flexibility for rare cases.
Offline First Apps with WebComponents
Explore offline-first web apps using WebComponents. Learn caching, in-browser databases, and data replication for seamless user experience, even without connectivity. Includes live coding demo.
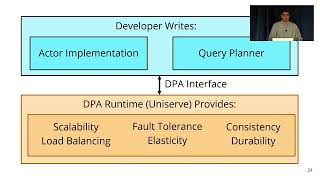
Data-Parallel Actors - A Programming Model for Scalable Query Serving Systems
Explore data-parallel actors, a programming model for building scalable query serving systems, offering simplified development and enhanced functionality for distributed data processing.
Re-Architecting Big Environments
Explore 5 architectural approaches for enhancing legacy systems with modern capabilities, illustrated through data replication and UI renovation examples from industry experts.
Building High Performance and Scalable Architectures for Enterprises
Learn enterprise architecture design using modern technologies and microservices patterns. Explore integration strategies, data management, and best practices for high-performance, scalable systems while addressing common challenges.
RubbleDB - CPU-Efficient Replication with NVMe-oF
Explores CPU-efficient replication in key-value stores using NVMe-oF, introducing novel mechanisms to address challenges and improve performance for write-heavy workloads.
Petabytes Data Migration and Load Balancing with Football+MARS
Explore efficient data migration and load balancing techniques using Football+MARS for large-scale container environments, focusing on cost savings and performance improvements.

Easy Geo-Redundant Handover + Failover with MARS + systemd
Simplify geo-redundancy and long-distance replication using MARS and systemd. Learn how to automate handover/failover for various application stacks, reducing complexity and costs.
Python and PostgreSQL for Huge Data Warehouses
Explore techniques for managing massive data warehouses using Python and PostgreSQL, covering connection pooling, data replication, optimization, and efficient querying strategies.
SQL Server Replication - Data Architecture
Explore log-based Change Data Capture for SQL Server replication, covering file system-level CDC, DDL propagation, and type/version support for high-volume environments.
Speed Racer - Local Persistent Volumes in Production
Explore best practices for using Local Persistent Volumes in Kubernetes, covering performance, limitations, operations, and use cases for high-performance stateful systems.
Piraeus - Local Persistent Volume Dynamic Provisioning, Management and HA
Explore Piraeus for dynamic provisioning, management, and high availability of local persistent volumes in Kubernetes, enhancing storage resource organization and data replication.