Building Billion Node Graphs for Machine Learning
Explore building billion-node graphs for machine learning, covering data ingestion, graph management, and algorithm execution at scale. Learn about challenges and solutions in handling massive datasets for GraphML research.
Processing Data at Scale with Rails
Strategies for handling large datasets using Rails, covering data ingestion, transformation, and storage with tools like ActiveRecord, Sidekiq, and Postgres.
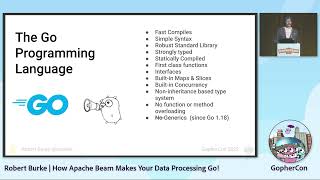
How Apache Beam Makes Your Data Processing Go
Explore Apache Beam's Go SDK for efficient distributed data processing, overcoming Go's unique challenges using reflection, interfaces, and generics for scalable pipeline execution.
Go, the Data Engineer's Missing Tool?
Explore Go's potential in data engineering, focusing on serialization, efficient processing, and reliability. Learn about challenges and benefits of introducing Go to this domain.
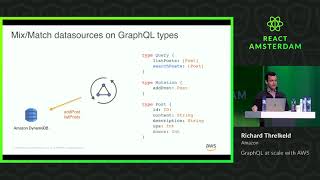
GraphQL at Scale with AWS
Explore GraphQL's scalability with AWS AppSync, covering offline data, subscriptions, authorization, and integration with various data sources for robust API development.
Streaming Algorithms in Javascript and Node.js
Explore streaming algorithms for efficient data processing in JavaScript and Node.js, covering techniques like the secretary algorithm, lossy counting, and greedy algorithms for real-time analytics.
Building a Distributed Data Ingestion System with RabbitMQ
Learn to build a distributed data ingestion system using RabbitMQ for cross-region data replication and processing. Explore Federation, multi-protocol support, and sharded queues with Consistent Hash Exchange.
How to Be a Web AV Artist
Explore audio visualization in browsers using Web Audio API, custom properties, and Web MIDI API for hardware control. Learn innovative techniques for processing and enhancing real-time music data.
Create the Internet of Your Things - The Microsoft Azure IoT Suite
Explore Microsoft's IoT approach using Azure IoT Suite. Learn to connect, store, and process data from distributed assets, redefining enterprise infrastructure and leveraging the Microsoft data platform.
Using Kafka for Real-Time Data Ingestion with .NET
Explore Apache Kafka's scalable messaging system for distributed architectures. Learn architectural principles and build a .NET project to efficiently produce and consume messages.
Protecting Sensitive Data in Huge Datasets - Cloud Tools You Can Use
Explore tools and techniques for protecting sensitive data in large datasets, including PII detection, k-anonymity, and data transformation methods for responsible public data release.
Privacy and GDPR - What All Developers Should Know
Explore GDPR's impact on IT systems through a practical example. Learn key privacy concepts, legal implications, and best practices for developers to ensure compliance and protect user rights.
Data Pipeline Scorecard: Evaluating Python Processing Approaches
Explore data processing approaches in Python, comparing different methods and their practical applications for building efficient data pipelines and optimizing workflow performance.
Scale Data Science Using Pandas API on Spark
Discover how to scale data science workflows using Pandas API on Spark, enabling efficient processing of large datasets while maintaining familiar pandas functionality and optimized performance.
Processing and Storing Time Series Instrument Data with Pandas and PySpark
Master data processing techniques for handling large-scale time series instrument data using pandas and PySpark, focusing on efficient solutions for scientific and laboratory information management challenges.
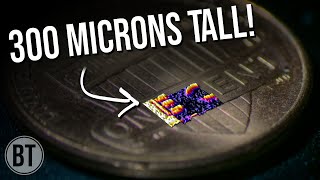
DIY Scanning Laser Microscope
Learn to build a DIY scanning laser microscope using 3D printing and open-source components. Explore confocal microscopy principles, optical setup, and data processing for 3D surface topology imaging.
How to Use Control Net Batch Processing to Make Videos with Colab, Deforum The LastBen Notebook
Learn to create videos using Controlnet batch processing with Colab and Deforum. Master image-to-video conversion, explore various Controlnet models, and unleash your creativity with fun animal-themed projects.
LinkedIn's Insights on AI Fairness in Hiring
Explore LinkedIn's approach to AI fairness in hiring, focusing on mitigating bias in algorithmic and product design, and data processing for more equitable recruitment practices.
The Challenges and Opportunities of Continual Learning in Real-Time Machine Learning
Explore challenges and opportunities in continual learning, covering stages, training types, key issues, and solutions for feature monitoring and evaluation in machine learning ecosystems.

Introduction to Apache Beam with Examples
Learn Apache Beam's unified model for batch and streaming data processing, with real-world examples from eBay and Mozilla's data pipelines.
Scale Your Batch, Big Data, and AI Workloads Beyond the Kubernetes Scheduler
Explore solutions for scaling batch, big data, and AI workloads on Kubernetes. Compare projects like Karmada, Koordinator, and Kueue to optimize cluster utilization and overcome scheduling challenges.