Scaling Machine Learning Feature Engineering in Apache Spark at Facebook
Explore advanced techniques for scaling ML feature engineering in Apache Spark, including Feature Injection and Feature Reaping, with optimizations for improved performance and efficiency at Facebook's scale.
Getting Started with Apache Spark on Kubernetes
Learn to deploy and optimize Apache Spark on Kubernetes with hands-on demos, covering environment setup, application sizing, performance tuning, and monitoring for efficient data pipeline management.
DBT Using Databricks and Delta
Learn to leverage Data Build Tool (DBT) with Databricks and Delta for efficient data lake management, including SQL-first approach, upsert capabilities, and Azure integration for enhanced observability.
Demystifying Delta Lake - Data Reliability for Data Lakes
Explore Delta Lake's reliability features for data lakes with Apache Spark creator Michael Armbrust. Learn about ACID transactions, metadata handling, and unified data processing.
Fugue: Unifying Big Data Analytics Ecosystems for ETL and Machine Learning
Unifying big data ecosystems with Fugue: SQL-like framework for ETL and ML pipelines, compatible with Spark, TensorFlow, and more. Simplifies development, improves performance, and enhances maintainability.
Presto on Apache Spark - A Tale of Two Computation Engines
Explore the integration of Presto and Spark, combining low-latency evaluation with robust execution for enhanced SQL experience in both interactive and batch use cases at Facebook scale.
Modernizing Apache Spark 3.0 Applications - Best Practices and Optimization Techniques
Optimize legacy Spark applications for 3.0: leverage Adaptive Query Execution, columnar processing, GPU acceleration, and ML integration. Concrete examples and lessons from modernizing analytics workloads.
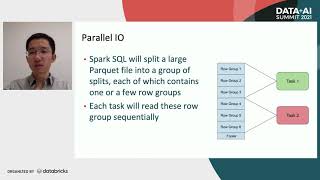
Optimizing Spark SQL Jobs with Parallel and Asynchronous IO
Optimizing Spark SQL jobs through parallel and async IO techniques, including file-level and row group-level parallel read, asynchronous spill, and parquet column family, resulting in 5-30% performance improvement.
Deep Dive into New Features of Apache Spark 3.1
Explore Apache Spark 3.1's new features: ANSI SQL compliance, streaming enhancements, Python improvements, and performance optimizations for faster, easier, and smarter data processing.
Configuration-Driven Reporting on Large Datasets Using Apache Spark
Configurable enterprise framework for generating and distributing diverse reports from large financial datasets using Apache Spark, with dynamic scheduling and data transformation capabilities.
Comprehensive View on Intervals in Apache Spark 3.2
Explore Apache Spark 3.2's interval enhancements, including ANSI SQL conformance, new interval types, and improved APIs. Learn to construct, use, and manage intervals effectively in Spark SQL and PySpark.
Migrating ETL Workflows to Apache Spark at Scale - Pinterest's Experience
Explore Pinterest's journey migrating ETL workflows to Apache Spark, covering challenges, solutions, and performance improvements. Learn about semantic gaps, thrift objects, and innovative Spark profiling techniques.
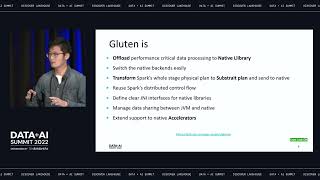
Gazelle-JNI: Offloading Spark SQL to Native Engines for Execution Acceleration
Explore Gazelle-Jni, a middle layer integrating native SQL engines with Spark SQL for accelerated execution through Substrait-transformed physical plan offloading.

Delta Live Tables: Modern Software Engineering for ETL Pipelines
Learn how Delta Live Tables simplifies ETL, enhances data pipeline reliability, and automates tasks. Discover modern software engineering practices for efficient data transformation and improved analytics, data science, and ML outcomes.
Master Databricks and Apache Spark - SparkR Usage - Lesson 35
Explore SparkR for integrating R with Databricks and Apache Spark, covering architecture, APIs, libraries, and practical examples of data manipulation and analysis.
Using SQL Views in Databricks and Apache Spark - Lesson 12
Learn to create and utilize SQL views in Databricks for efficient data analysis and pipeline reuse. Explore common table expressions, aggregations, and case statements for advanced querying techniques.
Estimate Change in CEO Departures With Bootstrap Resampling
Explore bootstrap resampling with tidymodels to analyze trends in CEO departures, using generalized linear models and #TidyTuesday data.
Impute Missing Data and Handle Class Imbalance for Himalayan Climbing Expeditions
Learn to predict survival in Himalayan climbing expeditions using tidymodels in R. Explore data handling, imputation, and modeling techniques for imbalanced datasets.
Databricks - How to Use Workflows
Learn to orchestrate and schedule complex multi-task processes using Databricks workflows, a powerful extension to the Jobs service that utilizes DAG architecture for efficient data processing and automation.
Pandas UDFs and Python Type Hints in Apache Spark 3.0
Explore redesigned pandas UDFs in Apache Spark 3.0, leveraging Python type hints for clearer, more Pythonic data science workflows and improved static analysis capabilities.
How Adobe Processes 2 Million Records Per Second Using Apache Spark
Explore Adobe's high-performance data processing using Apache Spark, covering optimization techniques, join strategies, structured streaming, skew handling, and integration with Redis for enhanced efficiency.