How Cleanlab Uses AI to Correct Errors in Any Dataset
Discover AI-powered tools for cleansing datasets, enhancing model training accuracy. Explore Cleanlab's innovative approach to data-centric AI and its practical applications.
Event Design and Event Streams Best Practices
Explore best practices for event design and streams: schemas, metadata, naming conventions, and unique IDs. Gain insights to optimize your event-driven architecture.

Processing Trillions of Records with Mini Serverless Databases at Okta
Explore serverless DuckDBs for efficient data processing, optimizing batch ETL, streaming, and SQL flexibility while addressing Kafka, latency, and ELT complexities in large-scale environments.
Pecan: Cost-Efficient ML Data Preprocessing with Automatic Transformation Ordering and Hybrid Placement
Optimize ML data preprocessing costs with Pecan's dynamic worker scheduling and transformation reordering, reducing preprocessing expenses by 87% and total training costs by up to 60%.
Best Practices for Data Preparation in Generative AI Development
Explore data preparation techniques for generative AI, covering quality, diversity, labeling, preprocessing, and optimization. Gain practical insights for enhancing model performance and accuracy.
Intro to Computer Vision - Fireside
Explore computer vision fundamentals, from basic concepts to problem-solving approaches, model building, and ethical considerations in this comprehensive introduction.
3D U-Net for Semantic Segmentation
Learn to implement 3D U-Net for semantic segmentation on volumetric data like FIB-SEM, CT, and MRI. Covers data preparation, model architecture, training, and multichannel image processing using Python libraries.
Multi-Class Language Classification With BERT in TensorFlow
Learn to build a multi-class language classification model using BERT and TensorFlow. Covers data preprocessing, model architecture, training, and prediction with transformers for NLP tasks.

Building and Designing Events and Event Streams with Apache Kafka
Learn to design effective event-driven architectures using Apache Kafka. Explore key concepts like internal vs. external events, fact vs. delta, and normalization strategies to build scalable, responsive systems.

Building a Flexible Data Platform for LLM Training Data
Explore LLM training data platforms: architecture, ingestion, preprocessing, and scaling challenges. Learn from Cohere's experience in managing petabyte-scale datasets for high-quality model training.
How Our Critical Systems Fail, and What We Do About It
Explore strategies for deploying critical health systems using Kubernetes and Kafka, ensuring seamless updates without compromising patient safety or data integrity.
From Tables to Documents - Changing Your Database Mindset
Explore the shift from SQL to document-based databases, learning key mindset changes for successful implementation and leveraging advantages like scalability and faster development.
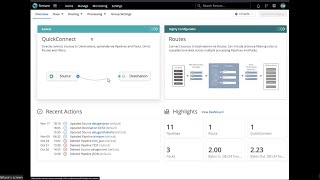
Exploring Cribl Stream and Cribl Edge - Data Collection and Observability Pipeline Demo
Discover how to manage observability pipelines with Cribl Stream and Edge, enabling flexible data collection, reduction, enrichment, and routing across your infrastructure for optimized business operations.
Data Preparation for RAG Applications Using Qdrant and FastEmbed
Master data preparation techniques for RAG applications using Qdrant and FastEmbed, covering chunking methods, embedding generation, indexing strategies, and efficient data loading processes.
Demystifying Data Curation for Pretrained Language Models
Dive into effective data curation techniques for language models, exploring key strategies and best practices for optimizing pretrained model performance through quality dataset preparation.
10 Data Science Uberhacks to Turbocharge Your Workflow
Discover 10 powerful data science techniques to dramatically boost productivity and efficiency in your workflow.
Data Preprocessing and Feature Engineering for Machine Learning
Master data preprocessing and feature engineering techniques for effective machine learning. Explore imputation, encoding, transformations, and more to maximize value from your data and improve model performance.
What is Machine Learning - Lecture 2
Explore machine learning fundamentals, data preprocessing, and Python basics for energy and petroleum applications.

Building and Deploying Machine Learning Models with Amazon SageMaker
Learn to build, train, and deploy ML models using Amazon SageMaker, covering data preprocessing, model selection, hyperparameter tuning, and evaluation.
Let's Talk About Raw Documents - Extracting Structured Data for ML Pipelines
Explore raw document processing for ML pipelines with Unstructured.io's open-source tools. Learn to extract structured data, build custom preprocessing APIs, and integrate with popular ML frameworks.
Building RAG-based LLM Applications for Production - LLMs III Talk
Develop and deploy scalable RAG-based LLM applications. Learn to handle data loading, preprocessing, embedding, and serving on clusters. Explore Anyscale Endpoints for cost-effective open-source model serving.