The State of Modern Data Architectures
Explore modern data architectures enabling agile, scalable solutions for IoT streaming, real-time analysis, and machine learning with large, multi-structured datasets in cloud environments.
Transforming Data Processing with Kubernetes - Journey Towards a Self-Serve Data Mesh
Explore Intuit's use of Kubernetes with Data Mesh principles to transform data processing, enabling efficient management of 100,000+ pipelines and fostering a collaborative data culture for improved decision-making.
Infinite Compression, Zero Knowledge Auth and Merkle Proofs - IPFS Connect Istanbul 2023
Explore w3up: UCAN-based upload API for web3.storage, enabling verifiable end-to-end data pipelines with infinite compression, zero-knowledge auth, and Merkle proofs.
How to Eliminate I/O Bottleneck and Continuously Feed GPU While Training in the Cloud
Optimize I/O for GPU-intensive machine learning training in the cloud. Learn a new architecture to maintain data throughput and implement it in Kubernetes for PyTorch workloads.
Build an Event-Driven Machine Learning Pipeline on Kubernetes
Explore building event-driven ML pipelines on Kubernetes, leveraging components for automated AI workflows, including model training, validation, serving, and operations with focus on eventing and pipeline CRDs.
Open Source DataOps and MLOps Strategies
Demystifying data challenges: interoperability, standardization, and vendor lock-in. Strategies for implementing DataOps and MLOps infrastructures using open source technologies.

Machine Learning for NCAA Tournament Bracket Predictions
Learn to build a machine learning model for predicting NCAA tournament outcomes, from data setup to final bracket creation, enhancing your predictive modeling skills and tournament strategy.
Bloomberg's Journey to a Multi-Cluster Workflow Orchestration Platform
Explore Bloomberg's evolution in cloud-native workflow orchestration, addressing challenges of rapid growth and discussing solutions for efficient multi-cluster resource deployment and management.
OpAMP in Action: User Configurable Observability Pipelines
Explore dynamic observability pipelines using OpAMP, addressing limitations of static configurations and enabling real-time adjustments for improved data processing and analysis.
From Configurations to Conclusions: Lessons from Fine-Tuning OpenTelemetry's Distributed Tracing
Explore Open Telemetry's distributed tracing capabilities, collector configurations, and performance optimization techniques. Learn valuable lessons from real-world implementation experiences.
DataOps as a Service
Explore DataOps as a Service: streamline data operations, enhance efficiency, and leverage cloud-native solutions for modern data management challenges.
Intelligent OT-Data Pipelines - Machines to Clouds
Explore Project Fledge's architecture for handling OT data's unique requirements, enabling automated factories and distributed edge applications from machine to cloud.
DataDevOps for the Modern Data Warehouse on Microsoft Azure
Explore DevOps principles for Big Data Analytical Pipelines using Azure Data Platform, including Data Factory, Databricks, and Data Lake Gen2. Learn to build and operationalize multi-source Modern Data Warehouses.
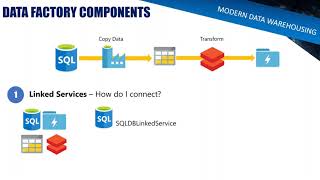
From ETL to Data Engineering with Azure Data Factory
Explore modern Azure Data Factory features for efficient, scalable data pipelines. Learn parameterization, dynamic workflows, and integration with Azure Databricks for cloud-native ETL solutions.

Reactive Spring Deep Dive - Building & Testing Reactive Cloud-native Java Microservices
Explore reactive programming in Spring for building resilient, responsive microservices. Learn integration, data pipelines, API design, and testing techniques for cloud-native Java applications.
Data Pipelines à La Mode
Explore pure data pipelines: reproducible, version-tracked, and efficient. Learn techniques from distributed build systems to improve algorithm updates and avoid redundant work.
Comparing Argo Workflows and Airflow in Distributed Environments
Explore workflow orchestration tools for distributed environments, focusing on Argo Workflows' advantages in Kubernetes-based pipelines and its scalability across multiple regions and zones.
Keeping Your NodeJS Promise in Production
Explore Node.js event loop architecture, asynchronous tasks, and production system challenges with live code samples for file I/O and data pipelines.
Bridging Data Science and Data Infrastructure with Apache Airflow
Explore how Apache Airflow bridges data science and infrastructure, enabling collaboration between teams and facilitating the development of flexible, observable, and resilient data pipelines.
Developing on Google Cloud with Python and DataFrames
Explore Google Cloud's enhanced Python experience for building applications, pipelines, and analytics, focusing on BigQuery integration and DataFrame support for impactful business solutions.
Getting Started with Polars
Explore Polars, a fast data manipulation library, through hands-on exercises with real-world datasets. Learn key operations, compare with Pandas, and optimize data pipelines.