GenAI Pipelines: From Data Exploration to Prototype to Production
Explore building GenAI data pipelines using PyAirbyte and ELTP framework. Learn efficient data sourcing, prototype-to-production steps, and strategies for managing LLM documents in the GenAI era.
Modernizing Data Pipelines with Databricks - IAS Journey
Discover how IAS modernized data pipelines using Databricks, migrating from Airflow to Workflows, implementing Data Mesh, and leveraging Unity Catalog for seamless data sharing and improved decision-making.
Drastically Reducing Processing Costs with Delta Lake
Optimize data pipelines using Delta Lake features on Databricks. Learn techniques to address read-write amplification, improve performance, and reduce costs in large-scale data processing.
Scalable Data Pipelines for ML - Integrating Argo Workflows and dbt
Discover how to build scalable ML data pipelines by integrating Argo Workflows and dbt. Learn to handle large datasets, optimize infrastructure, and enhance ML project efficiency through robust ELT processes.
Applying DevOps Practices in Data and ML Engineering
Explore DevOps practices in data and ML engineering. Learn to create efficient data pipelines using Versatile Data Kit. Gain insights on automating development processes and abstracting data journeys for agile, quality-focused data engineering.
Modular Solutions for Knowledge Management at Scale in RAG Systems
Discover how to build scalable RAG systems with modular document embedding pipelines, focusing on efficient processing, ingestion, and indexing for enterprise-level knowledge management.
Deep Dive into Network Observability and Data Correlation with Selector AI
Explore how Selector AI revolutionizes network issue remediation through advanced data correlation, observability, and automated incident management in this technical demonstration.
A Guide to Modern Data Stack - Building Efficient Data Infrastructure
Discover how to build and optimize a modern data stack with expert guidance on essential components, technologies, and best practices for efficient data management and analytics infrastructure.
GenAI Pipeline for Content Generation with Apache Airflow
Explore Apache Airflow's key features for building GenAI pipelines, including TaskFlow API, automatic retries, branching, and dynamic task mapping. Learn to overcome challenges in content generation workflows.
Productionising Data Science
Explore techniques for creating data pipelines, productionizing data science, and operationalizing machine learning with insights from experienced engineers.
Building a Fraud Detection Model with Feature Stores - Includes Shopify Case Study
Develop a real-time fraud detection system using ML data pipeline tools. Learn to build, deploy, and serve data pipelines with Feast and Tecton. Explore architectural patterns and model stages.
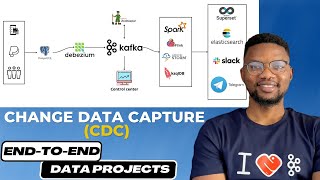
Realtime Change Data Capture Streaming - End-to-End Data Engineering Project
Implement real-time Change Data Capture streaming using Docker, Postgres, Debezium, Kafka, Apache Spark, and Slack. Create an efficient data pipeline for responsive data engineering projects.
Building Robust Data Pipelines for Modern Data Engineering - End-to-End Project
Develop robust data pipelines using Apache Spark, Azure Databricks, and DBT. Master end-to-end data engineering with Azure, covering ingestion, integration, and transformation in a modern data architecture.

Delta Live Tables: Building Reliable Data Pipelines with Databricks
Simplify ETL development with declarative pipelines, automatic testing, and deep visibility for reliable batch and streaming data on Databricks Lakehouse Platform.

Data Quality with Great Expectations
Master data validation techniques using Great Expectations to ensure high-quality inputs for AI/ML models, leading to more reliable and accurate results.
How to Win at Monetizing Games as a Service
Learn strategies for monetizing games as a service, from data engineering to AI/ML. Explore data pipelines, warehouses, and machine learning models to optimize game monetization.
Building Scalable and Effective Data Pipelines with Argo for Large-Scale Metadata Processing
Discover how to build high-performance data pipelines using Argo's parallelization techniques, achieving massive scale with 450% faster processing times and efficient metadata ingestion for large-scale data operations.
Processing One Million Data Points Daily with Dapr
Discover how to efficiently process massive daily data volumes using Dapr's distributed application runtime capabilities and cloud-native architecture patterns.
Building a ChatGPT RAG Data Pipeline with RisingWave Stream Processor and Vector Store
Discover how to build a real-time ChatGPT data pipeline using RisingWave stream processor, integrating Twitter feeds with vector embeddings for enhanced similarity search and RAG-based chatbot functionality.
Secure and Streamline Data Engineering Workloads with Azure Data Factory and Snowflake
Discover how to optimize data engineering workflows using Azure Data Factory and Microsoft Fabric with Snowflake, featuring bi-directional data access through Apache Iceberg for enhanced security and performance.
Fluent Bit - Building Better Pipelines for Observability and Telemetry Data Management
Discover how to build scalable data pipelines with Fluent Bit for efficient telemetry data collection, processing, and integration with Prometheus and OpenTelemetry formats.