A Tale of A Thousand Pipelines: Building Scalable Deep Learning Pipelines for Time-Series Datasets
Discover scalable deep learning pipelines for massive time-series datasets, reducing costs by 80% while training hundreds of models efficiently.

Using pgvector and PostgreSQL to Find Pictures at a Party
Explore using pgvector and PostgreSQL to automate finding photos of yourself at events. Learn to extract faces, calculate embeddings, and query image data efficiently.
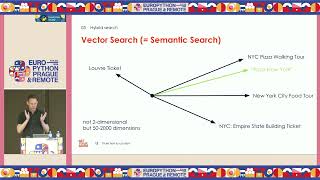
From Text to Context: How We Introduced a Modern Hybrid Search
Discover how to implement a modern hybrid search system combining BM25 and semantic vector models. Learn from real-world challenges and solutions in improving e-commerce search functionality.
OpenLineage: An Open Standard for Data Lineage
Explore OpenLineage, an open framework for data lineage metadata collection. Learn its purpose, data model, and integration with tools like Apache Airflow and Spark to enhance pipeline understanding and management.
Demystifying Apache Airflow - Separating Facts from Fiction
Unpack critiques of Apache Airflow, analyze its strengths and weaknesses, debunk myths, and compare with competitors. Make informed decisions about workflow management platforms.
Deep Skydiving into Data Factory in Microsoft Fabric
Explore advanced Data Factory scenarios in Microsoft Fabric, leveraging Data Pipelines and Dataflows Gen2 for scalable implementations.
Your First Flight with Data Factory in Microsoft Fabric
Explore Data Factory in Microsoft Fabric through a rapid tour, understanding its value for data integration in organizations.
End-to-End Data Validation Strategies in Microsoft Fabric
Explore strategic data validation in Microsoft Fabric's medallion architecture, enhancing end-user satisfaction through comprehensive WHY, WHEN, and HOW insights.
Deep Skydiving into Data Factory in Microsoft Fabric
Explore advanced Data Factory scenarios in Microsoft Fabric, leveraging Data Pipelines and Dataflows Gen2 for scalable implementations.
Roche's Maxim of Data Transformation - By Example
Explore Roche's Maxim through practical examples, learning to optimize data transformation processes for improved efficiency and effectiveness in data management.
Configuring Kafka Connect for Scalability - Best Practices
Optimize Kafka Connect clusters for scalability. Learn best practices to configure and manage Kafka Connect effectively, ensuring successful integration of external systems with Apache Kafka at scale.
Maximizing Real-Time Data Processing with Apache Kafka and InfluxDB - A Comprehensive Guide
Learn to create powerful data pipelines by combining Apache Kafka and InfluxDB for real-time processing, analysis, and visualization of large-scale data, especially in IoT applications.
Evolution of Streaming Pipeline at Lyft - Real-Time Optimization Platform
Explore Lyft's real-time optimization platform evolution, focusing on streaming infrastructure for marketplace balance, scalability, and decision-making using Kafka and data science tools.
Debezium Snapshots Revisited - Incremental Snapshots for CDC Pipelines
Explore innovative incremental snapshot techniques for Debezium CDC connectors. Learn to pause, resume, and parallelize snapshots, and customize snapshot contents for efficient data pipeline management.
From Raw Data to an Interactive Data App in an Hour - Powered by Snowpark Python
Develop a Streamlit data app to visualize advertising ROI using Snowpark Python. Learn data ingestion, transformation, ML modeling, and interactive visualization techniques.
Workflow Engines and Event Streaming Brokers - Can They Work Together?
Explore tradeoffs between workflow engines and event streaming brokers for microservices communication. Compare Apache Kafka and Temporal, examining their strengths and implementation challenges in various use cases.
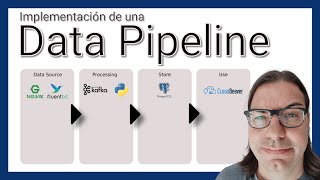
Creación de una Data Pipeline con KPIs - Fluentbit, Kafka, Python y PostgreSQL
Aprende a crear una Data Pipeline eficiente utilizando fluentbit, Kafka, Python y PostgreSQL. Domina la generación de KPIs y explora herramientas como CloudBeaver.
Tutorial de Apache Airflow: Desde Puesta en Marcha hasta API - Creación de DAGs y Uso de CLI
Aprende a instalar Apache Airflow, crear DAGs, utilizar operadores, ejecutar workflows, comunicar tareas y manejar el cliente CLI y API REST en este tutorial práctico.
A Deep Dive into the dbt Manifest
Explore dbt's manifest.json file, its production, and applications in data pipelines. Learn about deployment configurations, quality enforcement, and streamlined development workflows using real-world examples.
When to Move from Batch to Streaming and How to Do It Without Hiring an Entirely New Team
Demystify the transition from batch to real-time processing. Learn arguments, architectures, pitfalls, and open-source tools for stream processing without overhauling your team.

Declarative Orchestration: Why You've Been Thinking About the Wrong DAG the Entire Time
Explore declarative, asset-oriented orchestration in data pipelines. Learn how this approach simplifies tasks, ensures data integrity, and implements Data Mesh as a living asset graph.