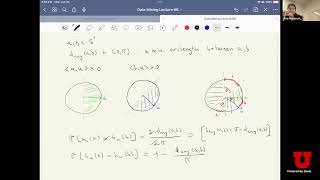
Understanding Distance Metrics in Data Mining - Spring 2023
Explore various distance metrics in data mining, from Euclidean and Manhattan to Mahalanobis and Angular, learning their applications, limitations, and relationships to LSH algorithms.
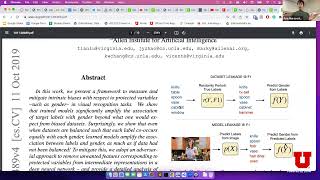
Data Mining: Embeddings and Representations in Machine Learning - Spring 2023
Explore data representation techniques from TF-IDF to contextualized embeddings, covering word analogies, societal biases, and image representations for advanced data mining applications.
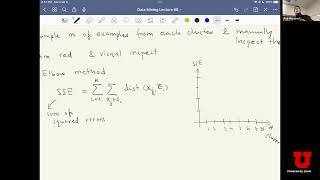
Data Mining: Understanding Hierarchical Clustering - Spring 2023
Master hierarchical clustering techniques, from basic concepts to advanced validation methods, including cluster proximity measures, stopping criteria, and efficiency considerations.
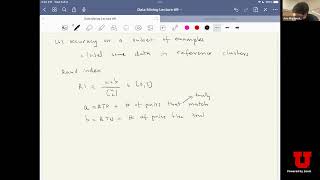
K-means Clustering and Validation Methods in Data Mining - Spring 2023
Master clustering algorithms through k-means, k-medoids, and Lloyd's algorithm, including initialization techniques, validation methods, and performance metrics for effective data mining applications.
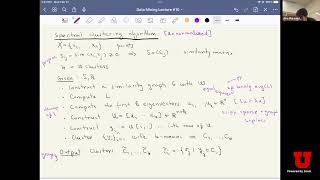
Spectral Clustering and Graph Partitioning - Data Mining Spring 2023
Master spectral clustering concepts through graph theory, Laplacians, eigenvalues, and practical algorithms for data partitioning and similarity analysis.
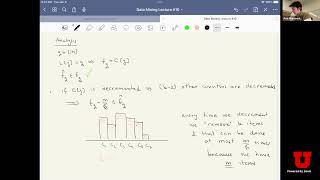
Data Mining: Streaming Algorithms and the Misra-Gries Algorithm - Spring 2023
Master streaming algorithms and frequency estimation through Misra-Gries techniques, spectral clustering, and majority algorithms for efficient data mining solutions.
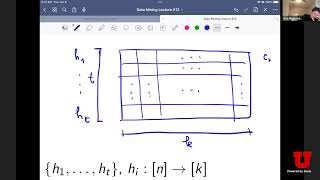
Data Mining: Sketch Algorithms and Count-Min Sketch Analysis - Spring 2023
Explore advanced sketch algorithms including Misra-Gries and Count-min techniques for efficient data mining, with detailed analysis and practical applications.
Data Mining: Introduction to Linear Regression - Spring 2023
Master linear regression fundamentals, from basic concepts to least squares method, while learning how to apply these techniques for effective data analysis and predictive modeling.
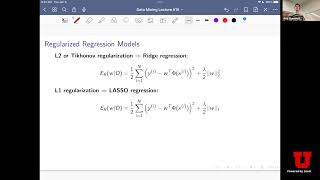
Nonlinear Regression and Regularization in Data Mining - Spring 2023
Master nonlinear regression concepts, from polynomial mappings to regularization techniques, while learning practical implementation in Python and understanding cross-validation for model optimization.
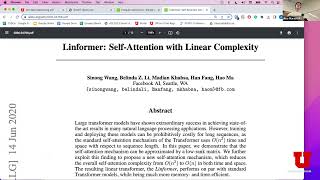
Data Mining: Frequent Directions and Random Projections - Spring 2023
Explore dimensionality reduction techniques through random projections, frequent directions, and SVD, with practical applications including the Linformer architecture for data mining.
Multidimensional Scaling and Linear Discriminant Analysis in Data Mining - Spring 2023
Explore multidimensional scaling (MDS) and linear discriminant analysis (LDA), learning key concepts, motivations, and practical applications in data dimensionality reduction and classification.
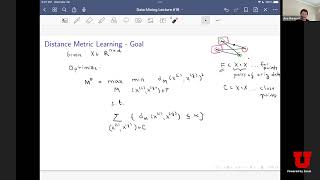
Distance Metric Learning and Outlier Detection in Data Mining - Spring 2023
Delve into advanced data mining concepts, focusing on distance metric learning, outlier detection techniques, and practical applications of DBSCAN for effective data analysis.
Matrix Completion and PageRank in Data Mining - Spring 2023
Dive into matrix completion techniques and PageRank algorithms, exploring fundamental concepts for data mining and graph analysis applications.
New Extractivism - Digital Exploitation in the Information Age
Explore how digital extractivism extends colonial practices into modern times, examining its impact on human behavior, DNA, emotions, and natural resources while reshaping global power dynamics.
Probabilistic Models of Relational Domains
Explore probabilistic models for relational domains with Stanford's Daphne Koller, covering advanced techniques for representing and reasoning about complex, interconnected data structures.
AI and the Impending Revolution in Brain Sciences - 2002
Explore the synergy between AI and brain sciences, examining how AI architectures interpret brain activity data and how machine learning discovers patterns in neurological research.
Speech and Language Processing: Where Have We Been and Where Are We Going - 2003
Explore the past, present, and future of speech and language processing with insights on technological trends, data mining, and shifting priorities in the field.
DeepWalk: Online Learning of Social Representations
Explore online learning of social representations with DeepWalk, a groundbreaking approach to understanding social networks and graph structures.
Discovery in High Dimensions - 2008
Explore statistical methods for uncovering hidden structures in high-dimensional data from various fields, including genetics, astronomy, and consumer behavior.
Finding Complex Patterns in Trajectory Data via Geometric Set Cover
Explore geometric set cover techniques for analyzing complex trajectory patterns, focusing on mathematical approaches to pattern recognition and data analysis in spatial movement.
Dated Data: Tracing Knowledge Cutoffs in Large Language Models
Explore the complexities of knowledge cutoff dates in Large Language Models, examining how training data timestamps affect model accuracy and investigating temporal misalignments in data collection.