Real-Time Smart Data Lake: Accelerating Big Data Analytics with Computational Storage
Discover how AirMettle's Real-Time Smart Data Lake revolutionizes big data analytics, offering up to 100x faster processing through innovative semi-structured data handling and computational storage integration.
Applying Engineering Best Practices in Data Lakes Architectures - Einat Orr
Explore engineering best practices for data lakes architectures, covering data infrastructure evolution, building blocks of data products, and practical tooling examples for effective data engineering.
Data Engineering and Storage Concepts - With ETL, ELT, Warehouse, Lake, and Lake House
Comprehensive overview of data engineering concepts, including storage solutions, ETL/ELT processes, and modern data architectures like data mesh, with practical examples and best practices for effective data management.
Funnel Analysis with Apache Spark and Druid for Advertising Campaign Effectiveness
Learn to perform funnel analysis at scale using Apache Spark, Druid, and DataSketches. Discover techniques for measuring campaign effectiveness and analyzing user behavior in chronological order for large-scale advertising campaigns.
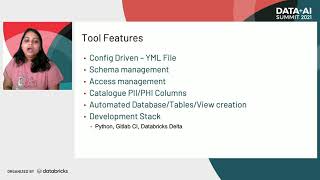
Automated Metadata Management in Data Lakes - A CI/CD Driven Approach
Discover a CI/CD-driven approach to automated metadata management in data lakes, focusing on balancing development speed, governance, and schema evolution for rapidly growing organizations.
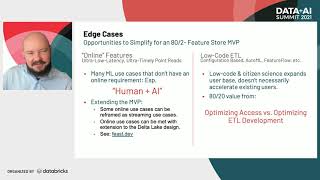
AI at Scale: Industrializing ML with Databricks
Learn to industrialize ML applications, accelerate model delivery, and optimize data science workflows while maintaining high governance standards using Databricks Lakehouse platform for enterprise-scale AI solutions.
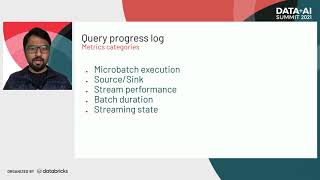
Delta Lake Streaming - Internals and Query Progress Logs
Explore Delta Lake streaming internals, focusing on structured streaming components, Query Progress Logs, and checkpoint directories for efficient real-time data pipeline management.
Why Lakehouse Architecture Now - Exploring Enterprise Data Warehouse Failures and the Need for Lakehouse Paradigm
Explore the shift from enterprise data warehouses to lakehouse architecture, focusing on benefits, challenges, and Starburst's role in powering SQL-based analytics on Delta Lake.
Engagement Activity Delta Lake for Einstein Analytics and Sales Cloud Einstein
Explore how Salesforce built an engagement activity platform using Delta Lake to support Einstein Analytics and Sales Cloud Einstein, covering data ingestion, incremental reads, and mutation handling.
Designing and Implementing a Real-time Data Lake with Dynamically Changing Schema
Learn to build a robust streaming ETL pipeline that handles dynamically changing schemas and new event types without downtime, using Delta Lake and Databricks for real-time data lake implementation.
Cost Efficiency Strategies for Managed Apache Spark Service with Databricks
Explore cost-efficient strategies for Azure Databricks, including resource management, tier selection, and best practices for optimizing Apache Spark workloads in a managed cloud environment.
Building a Cloud Data Lake with Databricks and AWS - Best Practices and Implementation
Explore building a cloud data lake using Databricks and AWS. Learn about data lake architecture, AWS services, Delta Lake for reliability and performance, and best practices for implementation.
DBT Using Databricks and Delta
Learn to leverage Data Build Tool (DBT) with Databricks and Delta for efficient data lake management, including SQL-first approach, upsert capabilities, and Azure integration for enhanced observability.
Demystifying Delta Lake - Data Reliability for Data Lakes
Explore Delta Lake's reliability features for data lakes with Apache Spark creator Michael Armbrust. Learn about ACID transactions, metadata handling, and unified data processing.
SQL Analytics and the Lakehouse Architecture - Data + AI Summit EU 2020 Keynote
Explore lakehouse architecture, Delta Lake, and SQL Analytics for unified data management. Learn how this approach combines data warehouse capabilities with data lake flexibility, enabling faster analytics and decision-making.
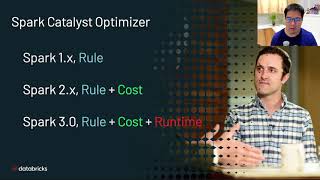
How Apache Spark 3.0 and Delta Lake Enhance Data Lake Reliability
Explore Apache Spark 3.0 and Delta Lake's enhancements for data lake reliability, including ACID transactions, schema enforcement, and time travel. Learn about performance improvements and new features in Databricks Runtime 7.0 Beta.
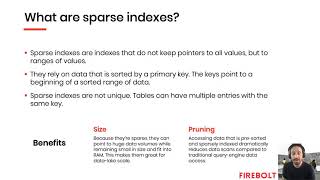
Low-Latency & High-Concurrency Analytics Over Data Lakes
Explore advanced techniques for achieving low-latency, high-concurrency analytics on large-scale data lakes. Learn about optimized storage, indexing, and practical approaches to handle massive data volumes efficiently.
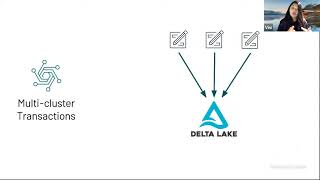
Delta Lake Roadmap 2021 H2 - Features Overview and Community Feedback
Overview of Delta Lake's 2021 roadmap, highlighting new features, integrations, and community-driven developments for enhanced data management and analytics capabilities.
Multi-Table Transactions with LakeFS and Delta Lake - Tech Talk
Explore multi-table transactions using LakeFS and Delta Lake for collaborative data lake management, enabling CI/CD deployment and simplified multi-table pipelines in cloud storage systems.
Redash - Open Source SQL Analytics on Data Lakes
Explore open-source SQL analytics on data lakes using Redash. Learn to create dashboards, develop workflows, and connect to Databricks for comprehensive analytics with Managed Delta Lake.
Data Science Across Data Sources with Apache Arrow - Accelerating Analytics and Interoperability
Explore Apache Arrow's columnar in-memory data representation for real-time analytics across distributed systems. Learn how it accelerates data processing and enables interoperability between various analytical tools and data sources.