Data Management - Full Stack Deep Learning - Spring 2021
Explore ML infrastructure for data management: ingestion, storage, processing, exploration, labeling, and versioning. Learn about tools and best practices for effective dataset handling in deep learning projects.
How to Set Up an ML Data Labeling Pipeline - Best Practices and Examples
Learn best practices for building ML data labeling pipelines through crowdsourcing. Explore real-life examples, requirements, and techniques for high-quality labeled data in supervised machine learning projects.
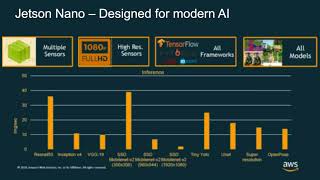
Deploy AI with AWS ML and IoT Services on Jetson Nano
Learn to deploy AI models on Jetson Nano using AWS ML and IoT services. Explore SageMaker, Greengrass, and real-time video processing for edge computing applications.
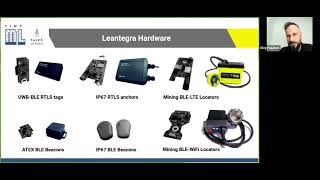
TinyML Talks Ukraine - Practical TinyML for Industrial Safety and Personnel Performance Monitoring
Practical implementation of TinyML for industrial safety and worker performance monitoring using custom hardware and TensorFlow Lite for motion recognition from IMU data.
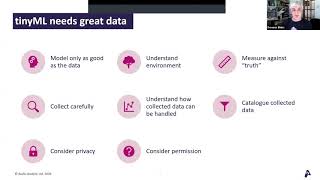
TinyML Talks - Dr. Dominic Binks- TinyML Doesn’t Need Big Data, It Needs Great Data
Explore challenges and solutions in obtaining quality audio data for tinyML sound recognition, focusing on data sources, collection methods, labeling strategies, and performance evaluation.
Identifying Sensitive Data and Mitigating Risk in Apache Spark and Databricks
Discover sensitive data in Apache Spark and Databricks using BigID's platform. Learn to scale discovery, label data, and apply necessary guardrails for compliance and risk mitigation in data analytics.
Getting ML Right in a Complex Data World
Explore efficient ML experimentation using data versioning tools to reproduce iterations, capture training data versions, and build intuitive infrastructure without duplicating resources.
Labeling Tools are Great, but What About Quality Checks?
Explore effective quality control strategies for data labeling in machine learning, ensuring accuracy and reliability in AI model training.
Ghost Work: The Human Labour Behind AI Technology
Explore the hidden workforce behind AI technology, examining ethical concerns and labor practices in data labeling and crowdsourcing platforms for AI development.
Local Llama 3.2 (3B) Tutorial - Summarization, Structured Text Extraction, and Data Labelling
Explore Llama 3.2 (3B) on Ollama for summarization, data extraction, and labeling. Learn setup, coding, and practical applications in this hands-on tutorial.
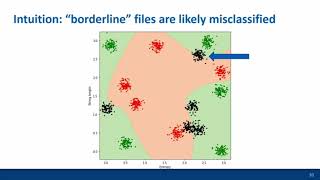
Measuring the Speed of the Red Queen's Race - Adaption and Evasion in Malware
Explore the dynamic evolution of malware and security measures using machine learning to quantify adaptation rates in the ongoing cybersecurity arms race.
Labeling the VirusShare Corpus - Lessons Learned
Explore insights and challenges in labeling large-scale malware datasets, drawing from experiences with the VirusShare Corpus. Gain valuable lessons for improving malware classification and analysis.
Developing an Intersectional Framework to Analyze Biases in Artificial Intelligence and Deep Neural
Explore an intersectional framework for analyzing biases in AI and deep neural networks, focusing on ethical tech development and mitigating discriminatory outcomes in machine learning.
No Silver Bullet - Multi Contextual Threat Detection via Machine Learning
Explore multi-contextual threat detection using machine learning, covering big data processing, modeling adversaries, and building custom solutions for defense at scale.
Using AI, 3D Printing and IoT in Diabetic Eye and Feet Diseases
Innovative use of AI, IoT, and 3D printing to tackle diabetic eye and foot complications, offering affordable screening tools and custom orthotics for improved healthcare accessibility in India.
When Humans Teach Machines
Explore an interactive DIY tool for non-data scientists to train and deploy classifiers, simplifying topic identification in large document sets with minimal data collection and quick model training and tuning.
Data Science in Action
Explore real-world applications of data science, from label data to unsupervised machine learning, with practical examples in wind energy, object detection, and automotive industries.
Machine Learning on Encrypted Data with CrypTen
Learn to develop machine learning models on encrypted data using CrypTen, a PyTorch-based framework for secure computing. Explore feature aggregation, data labeling, dataset augmentation, and model hiding techniques.
Data Labeling Best Practices for Fine-Tuning LLMs
Discover best practices for data labeling in LLM fine-tuning. Learn strategies for hiring, data preparation, and managing labelers to enhance AI model performance.
How to Prepare Annotations in Prodigy for Training SpaCy SpanCat Models - Part 2
Master the process of preparing and using Prodigy annotations to train SpanCat models in spaCy, focusing on data preparation, annotation techniques, and model training workflows.
AI-Driven Solutions for Text Anonymization - Implementing Machine Learning for Data Privacy
Explore AI-driven text anonymization techniques, from data labeling and NLP model training to implementing MLOps principles and human-in-the-loop processes for enhanced data privacy protection.