Generative Hyperloop Design - Managing Massively Scaled Simulations for Demand Modeling
Explore large-scale simulation framework for Hyperloop design, utilizing cloud computing, data pipelines, and machine learning to address key technical and business questions for safe and efficient mass transportation.
Real-Time Forecasting at Scale Using Delta Lake and Delta Caching
Explore real-time forecasting at scale using Delta Lake and Delta Caching. Learn efficient data sampling, storage, and caching techniques for handling massive datasets and achieving rapid forecast response times.
Building the Petcare Data Platform with Delta Lake and Spark ETL Pipeline
Explore Mars Petcare's data platform using Delta Lake and Spark ETL pipeline 'Kyte'. Learn about advantages over Azure Data Factory and leveraging Delta Lake for ETL configurations and data science.
Using Apache Spark for Predicting Degrading and Failing Parts in Aviation
Leveraging Apache Spark for predictive maintenance in aviation, enabling efficient data processing, anomaly detection, and component health scoring to improve fleet readiness and prevent failures.
Faster Data Integration Pipeline Execution Using Spark-Jobserver
Optimize data integration pipelines using Spark-Jobserver for faster execution, context reuse, and efficient resource management. Learn configuration, security, and API integration for improved performance.
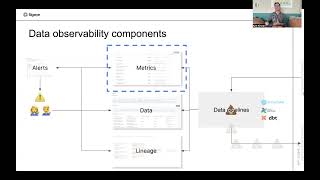
Reliable Pipelines and High Quality Data Without the Toil - Kyle Kirwan
Explore data observability's power in enhancing pipeline quality, reducing maintenance toil, and optimizing performance. Learn key components: metrics, data, lineage, and alerts for effective data management.
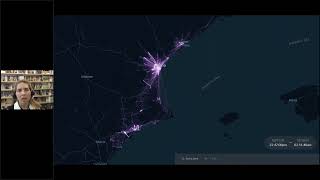
Data Science Against COVID-19 - Nuria Oliver, PhD
Explore how data science combats COVID-19 through mobility models, epidemiological predictions, and large-scale surveys. Learn key technical skills and insights from Dr. Nuria Oliver's multidisciplinary team of volunteer scientists.
Training and Ensuring Reliability of ML Models - The Power of ArgoCD, Flyte, and Argo Workflows
Explore Wolt's approach to reliable ML model training and deployment using ArgoCD, Flyte, and Argo Workflows. Learn strategies for scalability, consistency, and collaboration in ML operations.
Building Apache Druid on Kubernetes - How Dailymotion Serves Partner Data
Explore Dailymotion's implementation of Apache Druid on Kubernetes for partner data management, covering architecture, challenges, and optimizations for scalability and performance.
Kubernetes: The Cornerstone of Modern Data Engineering
Explore Kubernetes' impact on data engineering, focusing on open-source tools, scalability, and efficiency. Learn how it's shaping the future of data processing and management.
How to Avoid Overcomplicating Your Data Architecture
Explore strategies for simplifying data architectures, modernizing infrastructures, and leveraging real-time streaming for AI. Learn to navigate complexity and achieve faster results in data engineering.
Fluentd - A Complete Logging Ecosystem for Kubernetes
Explore Fluentd's internals, best practices, SDKs, and sub-projects for efficient logging in cloud-native environments, with a focus on Kubernetes integration and operational challenges.
Orchestrating Data Assets Instead of Tasks, With Dagster - Sandy Ryza
Explore data orchestration with Dagster, focusing on managing data assets over tasks. Learn about pipeline development, testing, deployment, and monitoring in data engineering and machine learning.
Demystifying Anomaly Detection in OpenSearch - Setup and Implementation
Explore OpenSearch's anomaly detection capabilities through a hands-on walkthrough of remote logging setup, using fluent-bit and creative techniques to spark ideas for larger-scale solutions.
Building a Business-Critical Data Platform to Process Over £34 Billion in Card Transactions
Explore the development of a PCI DSS compliant data platform on Kubernetes, addressing challenges in the UK payments infrastructure and discussing key considerations for fintech scalability.
Accelerating Spark Workloads in a Mesos Environment with Alluxio
Learn how Alluxio enhances Spark and Mesos performance by providing memory-speed data access across disparate storage systems, optimizing big data processing and enabling new workloads.
Getting Started with Delta Lake
Learn to create a Lakehouse architecture with Delta Lake, an open-source storage framework. Explore data reliability challenges, hands-on examples, and benefits for big data use cases in modern data engineering.
Building Modern Data Streaming Apps with Open Source
Discover best practices for building data streaming applications using open-source frameworks. Learn to orchestrate streams, perform ETL, enhance events, and make continuous queries with tools like Apache NiFi, Pulsar, Spark, and Flink SQL.
Efficient Data Parallel Distributed Training with Flyte, Spark and Horovod
Learn to optimize distributed training using Flyte, Spark, and Horovod for efficient data parallelism in machine learning workflows.
Self-serve Feature Engineering Platform Using Flyte and Feast
Explore a self-serve feature engineering platform leveraging Flyte and Feast technologies, enhancing data science workflows and machine learning model development.
Flyte - Cloud Native Machine Learning and Data Processing Platform
Explore Flyte, a cloud-native platform for machine learning and data processing, presented by Lyft engineers. Learn its features, benefits, and applications in modern data workflows.