Deep Dive into Network Observability and Data Correlation with Selector AI
Explore how Selector AI revolutionizes network issue remediation through advanced data correlation, observability, and automated incident management in this technical demonstration.
Transaction Log as the Heart of Delta Lake - Understanding Structure and Operations
Dive into the mechanics of Delta Lake's transaction log through hands-on PySpark exercises, exploring its structure, operations, and advantages over traditional data lakes.
A Guide to Modern Data Stack - Building Efficient Data Infrastructure
Discover how to build and optimize a modern data stack with expert guidance on essential components, technologies, and best practices for efficient data management and analytics infrastructure.
GenAI Pipeline for Content Generation with Apache Airflow
Explore Apache Airflow's key features for building GenAI pipelines, including TaskFlow API, automatic retries, branching, and dynamic task mapping. Learn to overcome challenges in content generation workflows.
Productionising Data Science
Explore techniques for creating data pipelines, productionizing data science, and operationalizing machine learning with insights from experienced engineers.
From Zero to Data Hero - Take Raw Data to Curated Data in Under 90 Minutes
Discover how to efficiently manage, process, and clean data using low-code tools. Learn to connect Apache Spark, Databricks, and TimeXtender for rapid data curation and confident decision-making.
Advanced SQL Techniques for Data Science
Expand SQL knowledge with complex conditions, functions, joins, and data engineering concepts. Learn from Facebook's Data Engineering Manager in this advanced session.
Fine-Tuning Language Models with Declarative ML Orchestration
Gain hands-on experience using Flyte to declaratively specify infrastructure for fine-tuning language models on your own data, overcoming compute resource challenges.
Building a Fraud Detection Model with Feature Stores - Includes Shopify Case Study
Develop a real-time fraud detection system using ML data pipeline tools. Learn to build, deploy, and serve data pipelines with Feast and Tecton. Explore architectural patterns and model stages.

Realtime Data Streaming - End-to-End Data Engineering Project
Build a real-time data streaming pipeline using Apache Airflow, Kafka, Spark, and Cassandra. Learn end-to-end data engineering, from ingestion to processing and storage, all containerized with Docker.
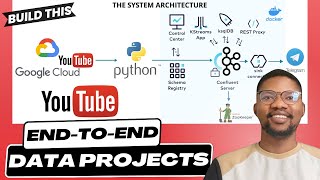
Google Cloud Real-Time Streaming - End-to-End Data Engineering Project
Build an end-to-end data engineering pipeline for real-time YouTube Analytics, using Python, Google Cloud, Docker, and Kafka. Learn to fetch, process, and stream data, with instant Telegram notifications.
Football Data Analytics: Azure End-to-End Data Engineering Project
Extract, clean, and analyze football data using Apache Airflow, Azure services, and Tableau. Build a comprehensive data pipeline from Wikipedia to interactive visualizations.
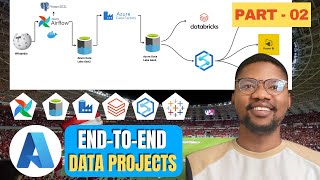
Football Data Analytics: Azure End-to-End Data Engineering Project - Part 2
Extract, store, and analyze football data using Azure services and Apache Airflow. Develop end-to-end data engineering skills through hands-on implementation of a real-world project.
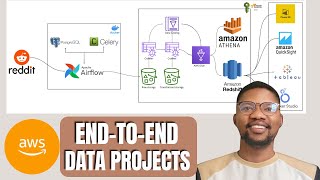
Reddit Data Pipeline Engineering with AWS - End-to-End Data Engineering
Build a comprehensive Reddit data pipeline using AWS services, integrating Airflow, S3, Glue, Athena, and Redshift for efficient ETL processes and analytics.
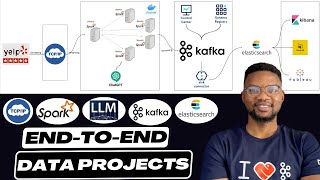
Realtime Socket Streaming with Apache Spark - End-to-End Data Engineering Project
Build a real-time data streaming pipeline using TCP/IP Socket, Apache Spark, OpenAI LLM, Kafka, and Elasticsearch. Process 7 million records for sentiment analysis and efficient data indexing.
Apache Airflow with Spark for Data Engineers - Full Course
Build end-to-end data engineering projects using Apache Airflow, Docker, Spark, and multiple programming languages. Learn to create and submit jobs to Spark clusters for processing and view real-time results.
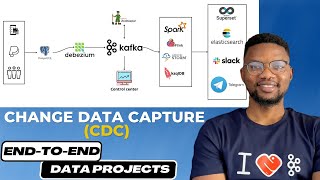
Realtime Change Data Capture Streaming - End-to-End Data Engineering Project
Implement real-time Change Data Capture streaming using Docker, Postgres, Debezium, Kafka, Apache Spark, and Slack. Create an efficient data pipeline for responsive data engineering projects.
Building Robust Data Pipelines for Modern Data Engineering - End-to-End Project
Develop robust data pipelines using Apache Spark, Azure Databricks, and DBT. Master end-to-end data engineering with Azure, covering ingestion, integration, and transformation in a modern data architecture.
Realtime Streaming with Data Lakehouse - End-to-End Data Engineering Project
Design, implement, and maintain secure, scalable lakehouse architectures using Apache Spark, Kafka, Flink, Delta Lake, AWS, and open-source tools. Unlock data's potential through advanced analytics and machine learning.
Realtime Algorithmic Trading with Apache Flink - End-to-End Data Engineering Project
Develop an end-to-end algorithmic trading system using Apache Flink, Kafka, and Python. Learn real-time data processing, custom algorithms, and financial market insights.

Delta Live Tables: Building Reliable Data Pipelines with Databricks
Simplify ETL development with declarative pipelines, automatic testing, and deep visibility for reliable batch and streaming data on Databricks Lakehouse Platform.