BigQuery as a Feature Store for AI/ML Applications
Discover how to transform BigQuery into an effective feature management system for AI/ML applications. Learn about designing feature tables, addressing challenges, and optimizing workflows without additional software.
Data Governance with Airflow and ECS Anywhere
Explore data governance compliance using Airflow and AWS ECS Anywhere for EU companies processing US data, ensuring legal adherence while maintaining efficient ETL processes.
Knative and Kafka - The Superheroes in Event-Driven Architecture
Explore event-driven architectures with Knative Eventing and Apache Kafka. Learn key concepts and see a live demo of a customer review moderation pipeline with AI/ML integration.
Feeding ML Models with Real-Time Database Data
Explore real-time data ingestion from databases to ML models using Change Data Capture. Learn about Debezium, challenges, and future improvements with a live TensorFlow demo.
Working with Filesystem in Time Series Databases
Explore techniques for building write-heavy applications, including write amplification mitigation, instant snapshots, and data corruption prevention, with real code examples from open-source projects.
A Holistic Approach to Securing Spark-Based Data Engineering
Learn to secure Apache Spark-based data engineering applications. Explore security best practices, identify threats, prioritize requirements, and implement practical steps for Kubernetes and object storage environments.
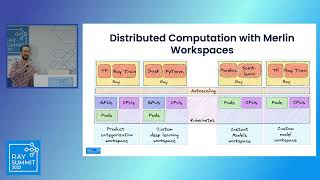
The Magic of Merlin - Shopify's New Machine Learning Platform
Explore Shopify's Merlin ML platform, its open-source stack, architecture, and how it scales ML work using Ray.
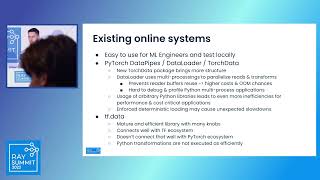
Cruise.data - A New Dataset Processing Pipeline for Cruise ML
Explore Cruise.data, a novel ML data pre-processing framework combining tf.data, PyTorch, and large-scale processing capabilities for efficient and scalable dataset handling in autonomous vehicle development.
Efficient AI: From Supercomputers to Smartphones
Explore techniques for efficient AI training and inference, from data ingestion to model compression, enabling powerful models on supercomputers and smartphones.
Using Julia as Part of an Anomaly Detection Pipeline
Explore Julia's role in anomaly detection pipelines, integrating data analysis, algorithm development, and real-time processing with Java-based web applications for efficient business solutions.
Become a Power Query Master in Excel in Less Than One Hour
Master Power Query in Excel: Learn to gather, clean, and transform data efficiently. Streamline your workflow, automate tasks, and optimize data preparation for analysis.
Streaming Data Pipelines From Supernovas to LLMs
Hands-on tutorial for building real-time data pipelines using Databricks, from ingesting NASA supernova data to implementing LLMs with RAG. Covers ETL, stream processing, and natural language analytics.
AT&T's Journey Towards a Serverless Data Intelligence Platform
Explore AT&T's evolution on Databricks Platform, scaling data projects with automated pipelining, serverless SQL warehouses, and AI/ML use cases while meeting security and regulatory requirements.
Databricks Asset Bundles: A Unifying Tool for Deployment
Explore Databricks Asset Bundles (DABs) for streamlined data project management. Learn core concepts, best practices, and deployment patterns using Databricks CLI, with real-world examples and future integrations.
Pivot Bio's Spatial Analytics Evolution with Databricks and CARTO
Explore how Pivot Bio revolutionizes agricultural analytics using Databricks and CARTO, integrating diverse datasets for comprehensive farming insights and empowering spatial analysis in modern agriculture.
Scaling Real-Time Healthcare Data Processing for Veterans Affairs
Optimizing VA healthcare data processing with Azure Databricks: Streamlining data ingestion, real-time analysis, and care delivery for 9 million veterans across 1,372 facilities.
NextGen Medical Affairs - Medical Response and Literature Review with GenAI
Revolutionizing medical insights with NLP and GenAI: Extract, analyze, and visualize unstructured data for efficient pattern identification and strategic decision-making in pharmaceutical research.
From Excel to Real-Time Insights Using Databricks, ThoughtSpot and Power BI
Transforme relatórios estáticos em insights em tempo real usando Databricks, ThoughtSpot e Power BI. Aprenda a construir uma plataforma de análise avançada para capacitar gerentes e analistas com dados atualizados.
Lakehouse Monitoring - Profiling, Diagnosing, and Enforcing Data Quality with Intelligence
Discover how Databricks Lakehouse Monitoring enhances data pipeline and ML model oversight, ensuring quality and governance for a self-serve data platform through continuous assessment and intelligent issue prevention.
How to Efficiently Scale Your Data Analytics Team with Databricks
Organizational framework for scaling data teams efficiently, focusing on role clarity, centralization vs. decentralization, data as products, governance, and leveraging Databricks for unified analytics.
Automating Spark Upgrades and Migrations at Netflix
Learn techniques for automating Apache Spark upgrades and migrations, including open-source tools for code rewriting, production testing, and job tracking. Discover strategies for seamless upgrades and pipeline validation.