Data Engineering in Microsoft Fabric - Getting Started with Notebooks and Lakehouse
Explore data engineering in Microsoft Fabric: Notebooks, Lakehouse flexibility, Spark configurations, and Copilot-enhanced efficiency for developers.
Roche's Maxim of Data Transformation - By Example
Explore Roche's Maxim through practical examples, learning to optimize data transformation processes for improved efficiency and effectiveness in data management.
Data Testing with HEDDA.IO
Enhance data quality with HEDDA.IO: Learn to integrate this versatile tool across Azure environments for accurate, reliable data testing in lake house and event-driven architectures.
New Features in Power Query for Power BI, Fabric, and Excel
Discover the latest Power Query features in Power BI Desktop, Fabric Dataflows, and Excel, enhancing data transformation capabilities.
Apache Flink for Sales Analytics - End-to-End Data Engineering Project
Develop an end-to-end sales analytics project using Apache Flink. Learn data ingestion, processing, complex transformations, and custom output formats for big data processing.
Building Data Lakehouse from Scratch - End-to-End Data Engineering Project
Design, implement, and maintain scalable lakehouse architectures using Apache Spark, Kafka, Flink, Delta Lake, AWS, and open-source tools. Enhance data potential through advanced analytics and machine learning.
Building a Winning Data Engineering Culture
Learn to build a successful data engineering team and culture, empowering engineers and partners for efficient data systems and fruitful projects. Explore critical roles and strategies for data-driven decision-making success.
Configuring Kafka Connect for Scalability - Best Practices
Optimize Kafka Connect clusters for scalability. Learn best practices to configure and manage Kafka Connect effectively, ensuring successful integration of external systems with Apache Kafka at scale.
Maximizing Real-Time Data Processing with Apache Kafka and InfluxDB - A Comprehensive Guide
Learn to create powerful data pipelines by combining Apache Kafka and InfluxDB for real-time processing, analysis, and visualization of large-scale data, especially in IoT applications.
Evolution of Streaming Pipeline at Lyft - Real-Time Optimization Platform
Explore Lyft's real-time optimization platform evolution, focusing on streaming infrastructure for marketplace balance, scalability, and decision-making using Kafka and data science tools.
Debezium Snapshots Revisited - Incremental Snapshots for CDC Pipelines
Explore innovative incremental snapshot techniques for Debezium CDC connectors. Learn to pause, resume, and parallelize snapshots, and customize snapshot contents for efficient data pipeline management.
From Raw Data to an Interactive Data App in an Hour - Powered by Snowpark Python
Develop a Streamlit data app to visualize advertising ROI using Snowpark Python. Learn data ingestion, transformation, ML modeling, and interactive visualization techniques.
5-Minute Practical Streaming Techniques That Can Save You Millions
Learn cost-effective streaming optimization techniques to drastically reduce infrastructure expenses. Discover simple SQL methods and advanced strategies for distributed storage and compute stacks.
Workflow Engines and Event Streaming Brokers - Can They Work Together?
Explore tradeoffs between workflow engines and event streaming brokers for microservices communication. Compare Apache Kafka and Temporal, examining their strengths and implementation challenges in various use cases.
Creación de una Data Pipeline con KPIs - Fluentbit, Kafka, Python y PostgreSQL
Aprende a crear una Data Pipeline eficiente utilizando fluentbit, Kafka, Python y PostgreSQL. Domina la generación de KPIs y explora herramientas como CloudBeaver.
Tutorial de Apache Airflow: Desde Puesta en Marcha hasta API - Creación de DAGs y Uso de CLI
Aprende a instalar Apache Airflow, crear DAGs, utilizar operadores, ejecutar workflows, comunicar tareas y manejar el cliente CLI y API REST en este tutorial práctico.

Tutorial DuckDB: La Base de Datos Rápida y Ligera para Analítica, ETL, Scripting y Microservicios
Explora DuckDB, una base de datos veloz y liviana para análisis, ETL, scripting y microservicios. Aprende sus ventajas y aplicaciones prácticas.
The Fun Sized MLOps Stack from Scratch
Build a fully-fledged MLOps platform for small companies using open-source tools. Learn about common problems, popular tools, recent OSS projects, and a realistic roadmap for improving data and ML maturity.
The End of History? Convergence of Batch and Realtime Data Technologies
Explore hybrid approaches like Lambda and Kappa architectures for combining batch and real-time systems. Learn about SaaS platforms and managed services that simplify implementation of these powerful data technologies.
Building an ML Experimentation Platform for Easy Reproducibility
Learn to build an ML experimentation platform using lakeFS for version control and reproducibility. Explore creating frameworks, reproducing iterations, and building intuitive infrastructure with open-source tools.
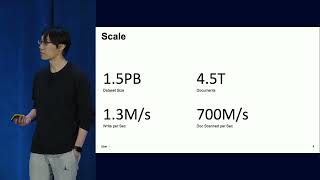
Scaling Uber's Metric System from Elasticsearch to Apache Pinot
Explore Uber's journey in scaling their metric system, transitioning from Elasticsearch to Apache Pinot for improved reliability and performance in real-time data processing.