How AI Will Transform Your Data Platform
Explore AI's impact on data engineering, from code writing with GitHub Copilot to data exploration with Power BI Copilot and data cleaning using Azure OpenAI Service in CluedIn.
Automating Azure Databricks Lakehouse Setup with BimlFlex - 20 Minute Guide
Automate a Lakehouse system for Azure Databricks using BimlFlex in just 20 minutes, streamlining your data management process.
Top 10 Azure Data Factory Tips and Tricks for Speed, Cost, and Performance
Discover 10 essential Azure Data Factory tips to enhance performance, reduce costs, and streamline data integration solutions for improved efficiency.
Data Lakehouse vs Data Warehouse in Microsoft Fabric - Choosing the Right Solution
Compare data lakehouse and data warehouse solutions in Microsoft Fabric to determine the best fit for your data engineering needs and migration goals.

Choosing Between Microsoft Fabric, Azure Synapse Analytics and Azure Data Factory
Compare Microsoft Fabric, Azure Synapse Analytics, and Azure Data Factory to select the optimal Data Integration solution for your project. Gain insights on their strengths and limitations.
Creating and Submitting Scala Jobs to Spark Clusters Using Airflow
Build end-to-end data engineering project using Airflow, Docker, Spark, Scala, Python, and Java. Create and submit jobs to Spark clusters, process data, and view real-time results.
Creating and Submitting PySpark Jobs to Spark Clusters
Create and submit PySpark jobs to Spark clusters in an end-to-end data engineering project using Airflow, Docker, and multiple programming languages. Learn job creation, cluster submission, and result visualization.
End-to-End Data Engineering with Apache Airflow, Docker, and Spark Clusters - Using Python, Scala, and Java
Build an end-to-end data engineering project using Apache Airflow, Docker, Spark Clusters, Scala, Python, and Java. Create and submit jobs in multiple languages to a Spark cluster for processing and real-time results.
Football Data Analytics with Tableau - Azure Data Engineering Project Part 3
Explore football data engineering: Extract Wikipedia data, store in Azure, migrate with Data Factory, query with Synapse, and visualize in Tableau. Master end-to-end data processes.
Creating and Submitting Java Spark Jobs to Spark Clusters
Create and submit Java Spark jobs to clusters. Learn end-to-end data engineering with Airflow, Docker, Spark, Scala, Python, and Java. Build and process jobs in multiple languages for live results.
AI-Driven Edge to Core Data Pipelines for Retail
Automate AI/ML model deployment in retail with an opinionated solution for continuous release cycles from edge to core data pipelines.

Challenges Using Apache Kafka for Data Streaming Systems
Explore key capabilities of streaming platforms and compare self-managed Apache Kafka with Confluent Cloud's fully-managed services for efficient data streaming operations.
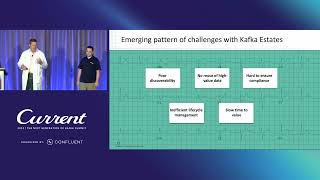
How Curing "Kafkatosis" Can Improve Your Stream Management and Governance
Learn to recognize and overcome "Kafkatosis" in Kafka environments. Discover strategies to optimize stream management, improve application onboarding, and enhance operational efficiency in diverse cloud and on-prem setups.
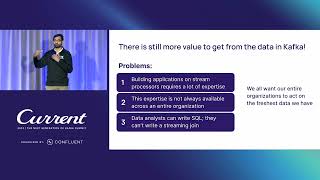
Operationalizing Pluralsight's Data with Materialize
Discover how Pluralsight leverages Materialize to replace complex streaming systems, enabling real-time analytics and applications through SQL-based materialized views for faster, cost-effective data operations.
From Edge to Cloud: Creating Data Pipelines Using Open-source with Strimzi on Kubernetes
Learn to create data pipelines from edge to cloud using open-source Strimzi on Kubernetes, enabling real-time data streaming across your organization.
Squeezing the Most From Your Kafka Infrastructure
Explore challenges and clever solutions for expanding Kafka infrastructure. Learn to optimize resources, streamline pipelines, and refocus on core business objectives as your system grows.
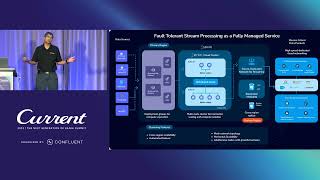
Striim: Unifying Change Data Capture, AI/ML, and Exactly-once Processing in a Managed Platform
Explore Striim's unified data streaming platform for rapid deployment of event stream pipelines, enabling real-time analytics and AI with built-in CDC and exactly-once processing.
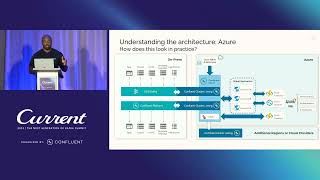
Unlocking Real-Time Data Insights: Leveraging Confluent Cloud on Azure
Leverage Confluent Cloud on Azure to build real-time data flows, capture changes instantly, and simplify data pipeline development. Boost productivity and innovate faster with streaming data pipelines and self-service access.
Govern Your Data Clients the Right Way to Scale
Learn to scale data governance, create supportive frameworks for data clients using open-source tools, and adapt to business changes. Gain insights on mitigating risks associated with uncontrolled growth.
Continuous Data Pipeline for Real-Time Benchmarking and Data Set Augmentation
Generate datasets and real-time precision/recall splits to detect data shifts, prioritize data collection, and retrain models for improved ML system accuracy and performance.
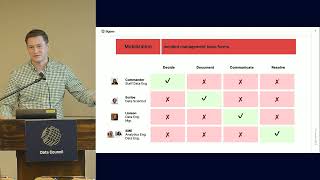
Incident Management for Data People
Learn how data teams can apply incident management practices to reduce disruptions in analytics and ML applications, improving pipeline reliability and data quality.