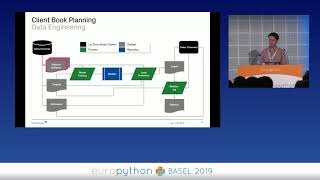
Building Data-Driven Client Relationship Management in Banking with Python
Transforming banking sales with Python: data-driven client management, machine learning pipelines, and automated processes for improved efficiency and personalized service.
Building Data Workflows with Luigi and Kubernetes
Learn to build complex data pipelines using Luigi, package them as Docker images, and deploy on Kubernetes for scalable Big Data workflows with on-demand scaling and cost reduction.
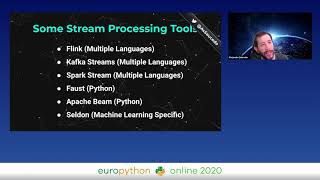
Real Time Stream Processing for Machine Learning at Massive Scale
Practical insights on building scalable data streaming ML pipelines for real-time processing using Python, Kafka, SpaCy, and Seldon. Covers key concepts and best practices through a Reddit comment moderation case study.
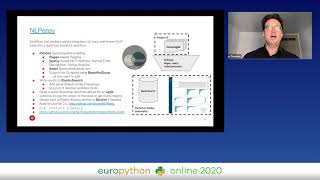
NLPeasy - A Workflow to Analyse, Enrich, and Explore Textual Data
Discover NLPeasy: a streamlined workflow for analyzing, enriching, and exploring textual data using pre-trained models, Docker, and Jupyter Notebooks. Simplify your NLP projects with this powerful Python package.
Automating Machine Learning Workflow with DVC
Discover how to automate and streamline machine learning workflows using DVC, from data ingestion to model deployment. Learn to organize pipelines efficiently, regardless of project size.
Mastering a Data Pipeline with Python - 6 Years of Learned Lessons from Mistakes
Explore key insights and best practices for building robust data pipelines with Python, covering data acquisition, transformation, storage, and workflow management based on 6 years of experience.
Writing and Scaling Collaborative Data Pipelines with Kedro
Discover how Kedro framework facilitates collaboration between data scientists and engineers, enabling scalable and sustainable data pipelines while balancing flexibility and stability.
Data Ingestion and Big Data
Learn web scraping, crawling, and API usage for data retrieval. Explore technical and ethical considerations in simulating user navigation and leveraging data APIs for analysis and business opportunities.
Data Warehouses Meet Data Lakes
Explore modern data architecture using PySpark, Hudi, Delta.io, and Iceberg to address datalake challenges, supporting real-time processing and enterprise-wide digital transformation.
PyArrow and the Future of Data Analytics
Explore PyArrow's transformative impact on data analytics, covering its in-memory format, disk format, network protocol, dataframe library, and query engine integration with NumPy and Pandas.
Orchestrating Python Workflows in Apache Airflow
Explore Apache Airflow for efficient Python workflow orchestration. Learn strengths, weaknesses, key features, and how to create custom operators based on 5 years of production experience.
Too Big for DAG Factories?
Explore dynamic generation of thousands of DAGs with Airflow to transform, optimize, and scale data workflows. Learn use cases and techniques for efficient data pipeline management.
Rust for Python Data Engineers
Explore how Rust can enhance data engineering workflows, offering improved performance and safety. Learn about Rust's ecosystem for data processing, databases, and scientific computing to build scalable systems.
Apache Spark vs Cloud-Native SQL Engines
Opinionated comparison of Apache Spark and cloud-native SQL engines, exploring their strengths, use cases, and complementary nature for data processing and business intelligence tasks.
Apache Arrow and Substrait - The Secret Foundations of Data Engineering
Explore Apache Arrow and Substrait's impact on data engineering, including their role in interoperability, query planning, and building efficient database systems with minimal code.
Windows Azure SQL Database Design - Silver Lining and Dark Side
Explore Windows Azure SQL Database design, covering editions, limitations, costs, data types, and modeling. Learn 10 tips for effective design and migration strategies.
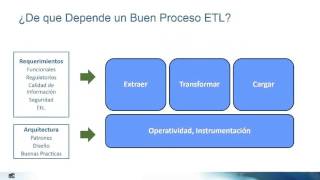
Principios de diseño para procesos de ETL
Aprende principios de diseño para procesos ETL eficientes, abordando desafíos comunes y mejores prácticas para una arquitectura sólida en el manejo de datos.
Rethink Your ETL with BIML
Revolutionize data warehousing with BIML: Learn to create templates for corporate standards and generate multiple packages efficiently, reducing weeks of SSIS development to hours.
The Role of Polybase in the Modern Data Warehouse
Explore PolyBase's role in modern data warehousing: streamline ETL, export dimensions, use Hadoop for archiving, and enrich relational data with ambient data from Hadoop.
Common Data Science Mistakes
Explore common pitfalls in data science, from data preparation to analysis. Learn to avoid mistakes in statistics, outlier handling, and visualization for more accurate insights and predictions.
Building Modern Data Pipelines with Spark on Azure HDInsight
Explore common patterns for building end-to-end data analytics pipelines using Apache Spark on Azure HDInsight, covering architecture, integration points, and various pipeline options.